
For the last two decades, the government has been engaged in a massive, expensive project called “Digital Transformation.” In practice, this often meant taking a paper form, turning it into a PDF, and putting it on a website. While this saved trees, it didn’t save time. The underlying logic of government work remained linear: a constituent submits a form. It sits in a queue. A human reviews it. Eventually, a decision is made. If the human is sick, the process stops. If volume doubles, the backlog quadruples.
We’re now witnessing the end of that era and the birth of something fundamentally different: the Agentic State.
As 2026 unfolds, we aren’t just automating tasks. We’re deploying autonomous agents. Unlike the brittle chatbots of the past, these agents can reason, plan, and execute complex workflows alongside human public servants. This isn’t science fiction – it’s already happening in cities like Kyle, Texas, and agencies like the Wisconsin Economic Development Corporation (WEDC).
This is the authentic, expert roadmap for how AI-powered public sector services are turning PSS workflows into autonomous engines of service.
Why Traditional Digitization Failed? (And Why AI Agents Are Different?)
The Structural Crisis of Linear Governance
To understand why autonomous agents matter, you first need to understand why the government is drowning in paperwork despite two decades of “digital transformation.”
A citizen applies for a business license. It takes three weeks. Someone files a complaint about a pothole. It sits in an inbox for days. A benefits application lands on a caseworker’s desk. They spend hours verifying eligibility manually. These aren’t edge cases. They’re the norm across most public sector organizations.
This friction isn’t accidental. It’s a byproduct of the “sequential handoff” model that dominates public sector solutions (PSS) architectures. In a traditional workflow, a case moves along a linear path:
Intake → Validation → Review → Decision → Disbursement
Each arrow in this chain represents a potential point of failure. If the “Validation” step requires a specialist who is on leave, the entire process halts. If the “Intake” form contains a minor error, it’s rejected and returned to the start, initiating a “ping-pong” cycle that consumes weeks of time.
For a small business owner, a three-week delay in licensing isn’t an administrative inconvenience. It’s an economic freeze, delaying hiring and revenue generation. For a vulnerable citizen awaiting housing benefits, the delay is an existential threat.
Why Simple Automation Didn’t Fix This?
The previous response to this crisis was Robotic Process Automation (RPA) and basic rules-based automation. These technologies promised efficiency but delivered fragility.
RPA bots could move data from Field A to Field B. But they lacked “agency” – the ability to reason through ambiguity or handle exceptions. If a form was non-standard, or if the data structure changed, the bot failed, defaulting the case back to a human queue. Traditional automation just executes pre-defined rules.
It doesn’t understand the context. It can’t look at a benefit application, realize that a supporting document is missing but that the applicant likely has it on file in a different department, and autonomously retrieve it.
This limitation meant that the most complex cases – which in government are often the majority due to the nuance of human life – remained strictly in the domain of human caseworkers, leaving the core bottleneck of human bandwidth unresolved.
The Shift to Autonomous Agents
The fundamental shift observed in late 2025 and solidifying in 2026 is the move to autonomous agents. Unlike chatbots that passively wait for a query, or RPA scripts that blindly execute a sequence, autonomous agents are goal-oriented. They possess a “cognitive architecture” that allows them to perceive a state, reason about the steps required to achieve a goal, and execute those steps across multiple systems.
When the City of Kyle deployed their AI-powered 311 system, they didn’t merely install a chatbot to answer FAQs. They deployed a system capable of accessing permit histories, inspection records, and council minutes to provide context-aware answers and updates. This represents a fundamental change in the “physics” of government work.
The agent becomes a “digital worker” that sits alongside human staff, handling high-volume, repetitive cognitive tasks (verification, synthesis, triage) and freeing humans to focus on high-touch, high-judgment interactions.
What AI-Powered Public Sector Services Actually Are?
Let me be direct: AI-powered public sector services aren’t just chatbots that respond to FAQs. They’re intelligent systems programmed to act on public sector information, make decisions within defined guardrails, and coordinate work across multiple systems and humans.
Think of it this way: a traditional PSS workflow moves data from one step to another in a line. Someone reviews an application. Someone else verifies eligibility. A third person approves the decision. Each handoff is a moment where things can slow down or break.
Autonomous agents fundamentally change this. Instead of sequential human steps, you have intelligent agents working in parallel, handling exception cases, flagging anomalies, and coordinating complex work.
Here’s what makes this different from previous automation attempts: autonomous agents don’t just execute pre-defined rules. They reason. They make contextual decisions. They pull information from multiple sources. They communicate with other agents. They adapt when circumstances change. For the government, this matters because public sector workflows aren’t simple. They involve complex eligibility logic, multiple data sources, regulatory constraints, and decisions that affect real people’s lives.
What Autonomous Agents Actually Do?
When you deploy an AI agent into your PSS workflow, you’re putting an intelligent worker into your case management system that can:
Handle intake completely.
A citizen applies for a benefit. Instead of waiting for someone to review their form, an agent immediately validates their submission, checks for completeness, flags missing documents, communicates with them about next steps, and categorizes their application by complexity. All of this happens instantly. If the application is straightforward, the agent moves it forward. If it’s complex, it goes to a human caseworker pre-staged with all the context they need.
Execute routine decisions instantly.
Eligibility checks. Document verification. Regulatory cross-reference. An agent can do in seconds what takes a human an hour. It pulls income data, checks household composition, verifies residency, calculates benefit amounts, and identifies any anomalies that need human judgment. The caseworker doesn’t have to do the legwork. They just handle the exceptions.
Coordinate across systems and departments.
Public sector workflows are fragmented. Information lives in legacy systems. Different agencies have different data. An agent can integrate across these systems, pull information from multiple sources, correlate data, and present a unified picture to the caseworker. It’s like having a research assistant who never sleeps and never makes mistakes pulling data.
Provide 24/7 citizen engagement.
Someone needs to know the status of their permit application. They can’t reach a human at 11 PM on a Saturday. An agent can. It has their complete application history. It can explain what’s happening, why, when they can expect completion, and what they can do to move things forward. This happens in multiple languages. It never misses a deadline or forgets context.
Detect problems before they become urgent.
Machine learning embedded in agents can spot patterns. It flags applications that look like fraud. It identifies cases at risk of going past service level agreements. It predicts which permits are likely to be denied based on regulatory analysis. It surfaces resource constraints before they cause delays. Instead of discovering problems when things go wrong, you identify them proactively.
Summarize and analyze complaints to surface trends.
When someone files a complaint about pothole maintenance, an agent analyzes that complaint, compares it to historical complaints, identifies related issues, suggests solutions, and flags if this represents a systemic problem (like “West side street maintenance is consistently delayed”). A supervisor gets a summary showing that pothole complaints jumped 40% in a specific area, helping them allocate resources where they’re actually needed.
The Architecture of Autonomy: How These Agents Actually Think?
The transition to an agentic model isn’t merely a software upgrade. It requires a fundamental re-architecting of the government technology stack. The Salesforce Agentforce ecosystem, as the primary vehicle for this transformation in the public sector, relies on a sophisticated interplay of data, reasoning engines, and integration layers.
The Cognitive Core: Atlas Reasoning Engine
At the heart of the agent is the Atlas Reasoning Engine. This is the “brain” that differentiates an agent from a script.
When an agent receives a goal – for example, “Process this business license application” – the Atlas engine engages in a planning process:

Perception:
It analyzes incoming inputs such as application forms, uploaded PDFs, and constituent emails.
Retrieval:
It queries the Data Cloud to retrieve relevant context, including the applicant’s history, existing permits, and applicable zoning laws.
Refinement:
It validates completeness and consistency, handles ambiguity or missing data, and determines whether escalation is required before proceeding.
Planning:
It evaluates available tools (APIs, workflows, actions) and constructs an executable sequence of steps to achieve the goal.
Action:
It executes the plan by calling the required systems to validate the address, check for tax liens, and verify insurance.
This “reasoning loop” is what enables the agent to handle the variability inherent in public sector work. It allows the system to adapt to the messiness of real-world data in a way that rigid automation never could.
The 2026 Recalibration: Hybrid Reasoning and Agent Script
By early 2026, a critical realization hit the enterprise AI market: autonomy without guardrails is unscalable.
The initial euphoria regarding “fully autonomous” agents – where the AI figures everything out on its own – encountered the hard reality of regulated environments. In the public sector, a decision cannot be “mostly right” or “creative.” It must be lawful. A probabilistic LLM cannot be trusted to “guess” at eligibility criteria for Medicaid or Housing Assistance.
This led to a strategic recalibration and the introduction of Hybrid Reasoning. This architecture acknowledges that while LLMs are excellent at empathy, conversation, and summarization (probabilistic tasks), they’re poor at rigid rule adherence (deterministic tasks).
To solve this, Salesforce introduced Agent Script, a human-readable scripting language that allows agencies to enforce strict business logic. This creates a hybrid workflow:

Deterministic Logic (The Script): The agency defines the statutory rules. “IF Household_Income > Threshold THEN Deny.” The agent must follow this path. There is no room for hallucination.
Probabilistic Reasoning (The LLM): The agency defines the tone and explanation. “Draft a notification letter explaining the denial based on the income criteria, using empathetic language and offering resources for appeal.” The LLM uses its reasoning capabilities to generate a human-centric communication based on the deterministic outcome.
This combination is the “missing link” for government adoption. It provides the auditability of code with the flexibility of AI. It ensures that the outcome is predictable (compliance) while the interaction is natural (service).
Data Cloud: The Unification Imperative
Data unification is foundational to any AI strategy. This is realized through Data Cloud (often referred to as Data 360).
Government data is notoriously fragmented. A citizen’s property tax record lives in a mainframe. Their permit application is in a SQL database. Their email correspondence is in Outlook. Their supporting documents are PDFs on a file server. An agent cannot reason across these silos.
Data Cloud ingests this disparate data, harmonizing it into a single “Citizen 360” profile. Crucially, the 2026 release of Intelligent Context allows agents to ingest and understand unstructured data. This is a game-changer for the public sector, where so much critical information is trapped in “digital paper” – scanned forms, architectural drawings, handwritten notes.
The agent can now “read” a PDF of a building plan to verify setback requirements, grounding its decision in the specific document provided.
Integration: MuleSoft Agent Fabric
Agents need hands as well as brains. To be useful, they must be able to do things – update a record, schedule an inspection, issue a payment. This requires integration with the legacy systems of record that underpin government operations.
MuleSoft Agent Fabric provides the orchestration layer for these actions. It allows IT teams to expose legacy system functions as “tools” that the agent can call. Instead of building a custom integration for every possible task, the agency registers the “Update Address” API with the Agent Fabric. The Atlas Reasoning Engine then “sees” this tool and knows it can use it when a constituent asks to move.
This layer also provides the necessary governance, logging every API call the agent makes for audit purposes – a mandatory feature for public sector accountability.
Security and Trust: The FedRAMP Standard and Einstein Trust Layer
No discussion of public sector technology is complete without addressing security. The “trust deficit” is a major barrier to adoption.
As of 2026, Agentforce for Public Sector has achieved FedRAMP High Authorization. This authorization is critical. It validates that the system can handle the government’s most sensitive unclassified data – Personally Identifiable Information (PII), health records, and law enforcement data – within a secure cloud environment.
The architecture utilizes the Einstein Trust Layer, which acts as a secure gateway. When an agent needs to use an LLM, the data is masked, sent to the model for inference, and the response is unmasked – but the data is never retained by the LLM provider for training. This “Zero Data Retention” policy is the bedrock of government trust in AI.
Real-World Examples: What’s Actually Happening Now?
Case Study 1: City of Kyle, Texas – The “311” Revolution
The City of Kyle serves as the definitive “Customer Zero” for public sector agent deployment. Facing a population explosion from roughly 20,000 to nearly 70,000 residents, the city’s infrastructure was buckling. They had over 75 different phone numbers for various services, creating a fragmented and frustrating experience for residents.
The Implementation:
The city deployed an AI-driven 311 system powered by Agentforce. This wasn’t just a website update. It was a unification of their service model. They consolidated their data – ordinances, fees, service history – into a data lake accessible by the agent.
The Metrics of Success:
The results validate the efficiency claims of the agentic model:
- Speed: The average service delivery time dropped to 2.41 days, significantly beating the SLA target of 4.37 days
- Resolution: The system achieves an 88.2% to 90% first-contact resolution rate
- Efficiency: Average call handling time stabilized at 2 minutes, 32 seconds, with after-hours calls (handled by the agent) averaging just 51 seconds
- Adoption: 21% of all service requests are now submitted via the web/mobile agent interface
Qualitative Impact:
Jesse Elizondo, Assistant City Manager, noted that the system allowed staff to escape the “grind” of routine calls (e.g., “When is the pool open?”). By offloading these 6,000+ routine interactions to the agent, staff could focus on high-complexity issues. This “redeployment” of human effort is the core value proposition: amplifying the capacity of a small staff to serve a booming population.
Case Study 2: Wisconsin Economic Development Corporation (WEDC) – High-Stakes Grant Administration
While Kyle illustrates the “service” use case, WEDC illustrates the “administrative” use case. As an agency responsible for deploying nearly $200 million in grants and loans, WEDC operates in a high-stakes financial environment.
The Application:
WEDC utilizes Salesforce to streamline the grant application lifecycle. Agents assist in the intake process, analyzing applications for completeness and summarizing complex business plans for human reviewers. This creates a “front door” for businesses that is always open, providing transparency into the status of applications – a critical requirement for an agency managing public funds.
The Metric Strategy:
WEDC measures success not just by speed, but by the quality of the human-agent interaction. Their metrics include:
- Decrease in case creation time (indicating efficient agent-driven intake)
- Decrease in training requests (indicating that staff are using the agent for “on-the-job” guidance)
- Increase in requests sent to the agent (indicating trust in the system)
The result: a small staff (155 people) can manage a massive portfolio with transparency and strategic focus – shifting from “did you sign page 4?” to “is this project good for Wisconsin?”
Pre-Built Solutions: The Future of Rapid Deployment
Beyond these custom implementations, the 2026 market has shifted toward industry-specific, pre-built agents. Salesforce now offers “Agentforce for Public Sector” with out-of-the-box capabilities for:
- Recruitment Management: Screening resumes and matching candidates to government roles
- Compliance Management: Analyzing inspection data to flag violations
- Benefits Management: Automating eligibility checks and recertification workflows
These pre-built solutions significantly reduce the “Time-to-Value,” allowing agencies to deploy standard agents in weeks rather than months.
The Economics: Cost, Pricing, and Workforce Impact
The Efficiency Dividend
The economic case for agents is built on the “Efficiency Dividend.” Research indicates that 64% of government leaders expect significant cost savings from AI. This is not derived from firing staff, but from avoiding the “linear cost scaling” of traditional operations.
In a manual model, handling 2x the applications requires 2x the staff. In an agentic model, handling 2x the applications requires only marginal additional compute power, as the agent absorbs the volume spike.
For agencies processing thousands of applications monthly, the impact is transformative. When you can reduce processing time from 3 weeks to 3 days, you don’t need proportionally more staff to handle the same volume. You handle more volume with the same staff.
Pricing Models: From Seats to Consumption
The shift to digital labor has disrupted traditional software pricing. In 2025/2026, the market moved toward consumption-based models. Salesforce introduced Flex Credits, charging approximately $2 per conversation or based on the number of actions performed.
However, for the public sector, variable costs are a liability. Government budgets are appropriated annually and are fixed. To address this, the market has “recalibrated” toward Agentforce Editions and “unlimited usage” models for employees, capped by a per-user license fee. This provides the budget predictability CIOs need while still enabling access to agentic capabilities.
Workforce Impact: Redeployment, Not Replacement
The narrative of AI often centers on job loss, but the public sector data suggests a different reality: the “Silver Tsunami” of retirements has left many agencies chronically understaffed. Agents act as a bridge for this skills gap.
HR leaders project a 327% growth in agent adoption by 2027. The strategy is redeployment: moving staff from data entry roles to “human-centric” roles. In fact, 23% of the workforce is expected to shift to entirely new roles focused on managing AI or handling complex casework.
The projected 30% productivity boost is effectively the only way for shrinking government workforces to meet rising citizen expectations.
The Strategic Roadmap: A Four-Phase Implementation Blueprint
The following roadmap synthesizes lessons from 2025-2026 into a coherent strategy for agency leaders.
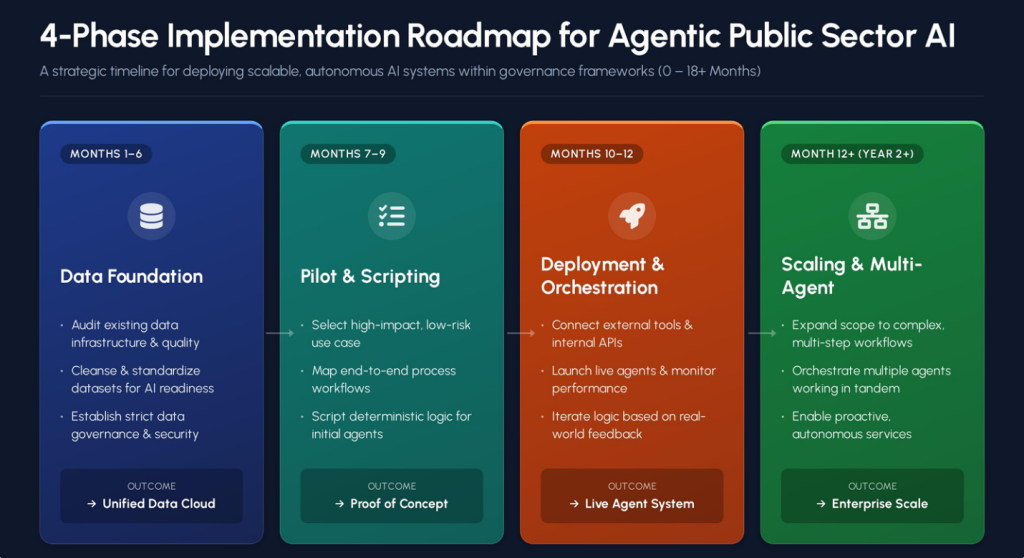
Phase 1: The Data Foundation (Months 1-6)
Audit and Unify: Before deploying an agent, agencies must unify data using Data Cloud. Identify the “sources of truth” for citizen data.
Cleanse: “Garbage in, garbage out” is the rule. An agent cannot verify an address if the database contains three variations of it.
Governance: Establish the AI Governance Board. Define the “Guardrails” using the Einstein Trust Layer.
This phase is unglamorous. It’s boring. But it’s where implementations succeed or fail. Agencies that rush this step deploy agents that don’t actually work well with their reality.
Phase 2: The Pilot and “Agent Scripting” (Months 7-9)
Select the Use Case: Choose a high-volume, low-risk workflow (for example, FAQ, simple permit intake). Don’t start with Child Protective Services.
Map the Workflow: Define the exact decision tree.
Script the Logic: Use Agent Script to hard-code the statutory rules. Ensure the agent cannot deviate from legal requirements.
Hybrid Design: Design the LLM prompts for the “empathy layer” of the interaction.
Phase 3: Deployment and Orchestration (Months 10-12)
Connect the Tools: Use MuleSoft Agent Fabric to connect the agent to the backend systems of record.
Launch and Monitor: Deploy to a subset of users. Use Agentforce Observability to track resolution rates and sentiment.
Iterate: Use the feedback loop to refine the Agent Scripts and prompts.
Phase 4: Scaling and Multi-Agent Systems (Year 2+)
Expand: Roll out to complex use cases (for example, Benefits Adjudication).
Orchestrate: Deploy “Manager Agents” that coordinate multiple specialist agents.
Proactive Service: Shift from reactive response to proactive notification (for example, “Your permit is about to expire, would you like to renew?”).
The Honest Challenges – What Actually Makes This Hard
Let’s be real about this. Autonomous agents in public sector workflows aren’t magic. There are legitimate challenges.
Legacy System Integration.
Many government agencies run on systems that are 15+ years old. They have inconsistent data formats. They don’t have clean APIs. Integrating agents into these environments is hard. It requires building custom connectors, data transformation layers, and careful testing. This isn’t a 3-month project. It’s 6-12 months of solid engineering.
Data Quality Is Foundational.
If your citizen data is messy – inconsistent formats, missing information, incorrect values – agents will produce garbage. You can’t skip data cleansing and unification. This is boring work. It’s unglamorous. But it’s mandatory.
Workflow Complexity.
Public sector workflows involve nuance. Eligibility rules aren’t always binary. There’s case-by-case judgment involved. You have regulatory constraints that interact in complex ways. Mapping this at the level agents need is hard.
Change Management Is Real.
Caseworkers who’ve done their jobs a certain way for 10 years might resist agents. You have to be transparent about what’s changing, involve them in the design, help them understand how agents amplify their effectiveness rather than replace them.
Regulatory and Compliance Constraints.
Every public sector workflow operates under regulatory constraints. Data must be retained for specific periods. Decisions must be defensible. Audits must be possible. Privacy rules must be followed. These constraints are real and they complicate agent design.
Skills Gap in Government IT
Most government IT teams aren’t trained in AI, orchestration, or modern integration patterns. You’ll need either to upskill your team or bring in external expertise.
Real talk: This isn’t for every workflow yet. Autonomous agents work best in workflows with high volume, repeatable decision logic, clear data sources, acceptable escalation rates, and clear success metrics.
Start with benefits processing, permit application intake, complaint triage – these are sweet spots. Complex investigations, policy interpretation, cases involving vulnerable populations where nuance is critical – be realistic about what agents actually do.
Practical Next Steps – If You’re Considering This
If you’re a government IT leader or innovation director considering Agentforce for Public Sector, here’s what actually happens:
1. Assess Your Current State.
Pick one PSS workflow that’s causing pain. License processing. Benefit applications. Complaint intake. Whatever creates the most bottleneck. Map it in detail. This takes 2-3 weeks.
2. Define Your Data Strategy.
Be honest about your data. Is it consistent? Connected? Or fragmented? Do you have a single citizen view or are citizen records scattered across systems?
3. Build a Proof-of-Concept.
Don’t plan a massive rollout. Pick one workflow. Define one agent. Run it against historical data. Verify it makes decisions you’re comfortable with. A good POC takes 8-12 weeks.
4. Invest in the Foundation.
If you’re serious about this, data unification isn’t optional. Salesforce Data Cloud or equivalent. Modern integration layers. Clean processes. Plan 4-6 months and significant budget for this phase.
5. Plan for Governance.
Before you deploy, define what success looks like. What metrics matter? What compliance requirements must be met? How will you explain agent decisions to auditors?
What Actually Changes? When You Deploy Agents?
Here’s what government agencies actually experience when they deploy AI agents in their workflows:
Processing timelines collapse.
Permits that took 3 weeks take 3 days. Benefit applications that took 15 days take 2-3.
Citizens can actually track progress. A pothole report isn’t a black hole. A citizen can check their permit status anytime. A benefit applicant knows what’s happening. This transparency reduces anxiety and improves satisfaction.
Caseworkers focus on actual work. They’re not doing data entry. They’re not chasing information. They’re not coordinating across systems. They’re actually talking to citizens, understanding their situations, and helping them. This is what they went into public service to do. They like this change.
Agencies catch problems early. Fraud patterns are detected early. Cases at risk of missing deadlines get flagged. Resource constraints surface before they cause delays. You’re proactive, not reactive.
The economics work. Cost per transaction drops. Processing capacity increases without proportional staff increase. You can serve more citizens with the same resources.
Comparative Framework – Traditional vs. Agentic Workflows
To understand the transformation, here’s how the two models compare:
| Feature | Traditional PSS Workflow | Agentic PSS Workflow (2026) |
| Trigger | Human submission (Form) | Proactive event or submission |
| Process Flow | Linear, Sequential | Parallel, Orchestrated |
| Decision Logic | Human Judgment (Slow) | Hybrid: Deterministic Script + AI Reasoning (Fast) |
| Data Access | Siloed, Manual Lookups | Unified Data Cloud (Citizen 360) |
| Availability | Business Hours (8-5) | 24/7 Always-On |
| Scalability | Linear (Add Staff) | Exponential (Add Compute) |
| Citizen Experience | “Black Hole” (Wait & See) | Transparent, Real-Time Interaction |
| Staff Role | Data Entry & Processing | Complex Case Management & Service |
| Exception Handling | Escalation to Human | Agent Reasons, Then Escalates if Needed |
| Audit Trail | Fragmented Logs | Complete, AI-Generated Decision History |
Key Metrics That Matter – The Data Behind the Transformation
Here’s what the numbers actually say about this shift:
| Metric | Value | Context |
| Gov Leader Cost Savings Expectation | 64% | Percentage of leaders expecting significant savings from AI |
| Public Openness to AI Services | 90% | Citizens willing to use AI for government services if it improves speed |
| City of Kyle Resolution Time | 2.41 Days | Down from target of 4.37 days |
| City of Kyle First Contact Resolution | 88.2% – 90% | Requests resolved without callback/transfer |
| Expected Productivity Gain | 30% | Per-employee gain from agentic AI |
| Agent Adoption Growth Projection | 327% | Projected growth by 2027 |
| Workforce Role Shift | 23% | Of workforce expected to shift to new AI-focused roles |
| Agentforce Authorization Level | FedRAMP High | Authorized for sensitive US Government data |
The Bottom Line – The Inevitability of the Agentic State
What if your entire workflow could operate 24/7, handling complex decisions without human intervention? The evidence from 2026 suggests this is no longer a “what if.” It is an operational reality in cities like Kyle and agencies like WEDC.
The transition to the Agentic State is driven by necessity. The linear, human-dependent workflows of the past cannot scale to meet the demands of the present. By embracing autonomous agents – architected with hybrid reasoning, grounded in unified data, and secured by FedRAMP standards – government agencies can break the cycle of paperwork and return to their core mission.
This is not a future where machines replace public servants. It is a future where machines liberate them. It is a future where the “grind” of governance is automated, leaving the “service” of public service to the humans best equipped to provide it.
Why This Matters Now:
The “Silver Tsunami” of government retirements combined with rising citizen expectations creates an impossible equation for traditional linear workflows. Agentic AI is not a luxury. It’s the only viable way for shrinking workforces to meet growing demands.
The Path Forward:
Agencies that start now – even with POCs and pilots – will gain 12-18 months of experience and organizational learning. They’ll refine their data strategies, test Agent Script patterns, and build internal expertise. By 2027, these agencies will be significantly ahead of the curve, with proven implementations and battle-tested processes.
The question isn’t “Should we do this?” The question is “Can we afford not to?”
Your OmniScript is running smoothly in production. Users are navigating through steps, data is flowing, Integration Procedures are executing. And then – nothing.
A user hits step three, calls Integration Procedure, and something breaks. The error message says “Remote Action Error” but doesn’t tell you WHY. You check the logs. Three different systems to investigate. You find the IP failed, but why? Was it a timeout? API rate limiting? Bad data? Field mapping issue?
Your team spends three hours digging. You check Apex logs, DataRaptor mappings, network requests, governor limits, external API response codes. By the time you finally connect the dots and realize it was an API rate limit hit at 2 PM when system load was highest – you’ve lost hours of productivity and user trust.
And the worst part? It’ll probably happen again next week. Same time. But you won’t know until users complain.
If you’ve been there, you know this is one of the biggest pain points in OmniScript troubleshooting. And here’s the thing: humans are really slow at finding these patterns. You’d need to see thousands of failed executions across months to notice “hey, every Tuesday at 2 PM we hit rate limits.” Without that pattern recognition, you’re stuck firefighting instead of preventing.
This is where AI agents for Salesforce troubleshooting actually become useful. They don’t get tired. They see all the data. They find patterns in a thousand failed executions while you’re still reading the error message. And once trained, they flag problems before your users even hit them.
This guide walks you through exactly how to train an AI agent to troubleshoot OmniScript failures. We’re talking about real implementation – not theory. The data you need to collect, the machine learning approaches that actually work, how to build this in Agentforce, and what happens when it breaks (because it will, and that’s okay).
What Does It Actually Mean to Train an AI Agent for OmniScript Troubleshooting?
Here’s the thing: we need to be clear about what we’re building, because it’s not what you might think.
Training an AI agent to troubleshoot OmniScript failures isn’t about creating some magic black box that solves problems. It’s about teaching a machine learning model to recognize patterns in your OmniScript ecosystem that would take humans hours or days to spot.
Think of it like this. Every time your OmniScript executes, it leaves a trail.

Step 1: User enters data (form inputs).
Step 2: System validates it (Set Errors elements).
Step 3: OmniScript calls a DataRaptor to fetch related records.
Step 4: OmniScript triggers an Integration Procedure to push data to an external system.
Step 5: If any of this breaks, you get a log entry.
When you have weeks or months of this data, patterns emerge. Real patterns. Not guesses.
“Integration Procedure timeouts always happen between 2 PM and 3 PM on Tuesdays” = API rate limiting under peak load.
“DataRaptor failures only occur when Account.Type = Prospect AND Amount > $100,000” = Query performance issue under specific data conditions.
“Remote Apex call errors happen after processing 50+ records in a single transaction” = Governor limit violation.
An AI agent trained on this historical data learns these patterns. It establishes a baseline of what “healthy” OmniScript execution looks like in YOUR org (not a generic definition). Then when something deviates from that baseline, it flags it immediately. Not weeks later. Not when the bug report comes in. Now.
That’s the power: Early detection, pattern recognition, and root cause analysis at machine speed.
The Five Types of OmniScript Failures You’re Probably Experiencing Right Now
Before you train an AI agent, you need to understand what you’re actually trying to predict. Each failure type has a distinct signature in your logs.
┌─────────────────────────────────────────────────────────────┐
│ OMNISCRIPT FAILURE TYPE DISTRIBUTION │
│ (Based on Real-World Organizations) │
└─────────────────────────────────────────────────────────────┘
↓
🔴 INTEGRATION PROCEDURE FAILURES ████████████ 40%
(Most Common – API timeouts, field mapping, rate limiting)
Frequency: Very Common
Severity: HIGH
🟠 DATRAPTOR FAILURES ███████ 25%
(Performance degradation, data condition issues)
Frequency: Common
Severity: MEDIUM
🟡 VALIDATION/ERROR HANDLING FAILURES ██████ 20%
(False positives, broken cross-step dependencies)
Frequency: Medium
Severity: MEDIUM
🟡 TIMEOUT/PERFORMANCE FAILURES ███ 10%
(Slow queries, governor limits, large payloads)
Frequency: Medium
Severity: HIGH (Silent failures)
🟢 PERMISSION/ACCESS FAILURES ██ 5%
(Field security, object permissions, custom checks)
Frequency: Rare
Severity: LOW (Usually one user affected)
Integration Procedure Execution Failures (Most Common – 40%)
Your OmniScript calls an Integration Procedure to handle business logic – fetching data from Salesforce, calling an external API, calculating something complex. The IP starts executing. Then somewhere in the middle: it breaks.
Common causes:
- API timeouts (external service is slow or down)
- Field mapping failures (data doesn’t match expected format)
- Conditional logic errors (decision step returns unexpected data)
- Rate limiting (hit API quota limits)
- Credential issues (token expired, authentication failed)
The error bubbles back to OmniScript as “Remote Action Error” and users see a vague message.
DataRaptor Failures (Common – 25%)
Your OmniScript tries to load or manipulate data through a DataRaptor. The DataRaptor worked fine yesterday but fails today. Why?
- Performance degradation (works with 100 records, times out with 10,000)
- Data condition failures (fails when specific field is null or contains unexpected value)
- Mapping misconfiguration (doesn’t handle complex nested data structures)
- SOQL inefficiencies (DataRaptor generates non-optimal queries)
Validation and Error Handling Failures (Medium – 20%)
You’ve configured Set Errors elements to catch issues. You have custom error messages. But the validation logic is brittle.
- False positives (valid data flagged as invalid)
- Missing validations (invalid data allowed through)
- Error message paths misconfigured (users see cryptic messages instead of helpful guidance)
- Cross-step dependencies broken (change in one step breaks validation in another)
Timeout and Performance Failures (Medium – 10%)
The OmniScript doesn’t crash – it just hangs. The user hits “Next,” waits 30 seconds, and gets a timeout. These are the sneaky ones because the system doesn’t technically fail.
Common causes:
- Inefficient queries (N+1 query problem, missing indexes)
- Governor limit violations (approaching CPU/query limits)
- Slow external APIs (callout takes 20+ seconds)
- Large JSON payloads (moving gigabytes of unnecessary data)
- Browser performance (heavy LWC components, too many conditional blocks)
Permission and Access Failures (Rare – 5%)
An OmniScript works fine for most users, then fails for one specific profile. Why? Permissions.
- Field-level security (user can’t see a field being accessed)
- Object-level permissions (user can’t access the object)
- Custom permission checks (business logic denies access)
- Integration user permissions (agent user lacks required access)
Building Your AI Training Dataset: Everything Starts Here
Here’s the uncomfortable truth: you can’t train an AI agent without data. And not just any data.
You need:
- The right kind of data (structured, labeled, comprehensive)
- Enough of it (minimum 2 weeks, realistic minimum 60-90 days)
- From multiple sources (not just OmniScript logs – you need the full stack)
Most organizations skip this part. They try to build AI agents with two weeks of data and wonder why they get false positives everywhere.
Step 1: Enable Error Logging for Integration Procedures
Navigate to Setup → Omni Interaction Configuration.
Create a new configuration: name it ErrorLoggingEnabled (or be creative, but be consistent).
Enable it.
What happens next: Salesforce captures detailed information about every failed Integration Procedure step. Errors land in the OmniComponentErrorLog object. You’ll now see:
- Which step failed
- What error it returned
- What data it was processing
- Execution timestamps
Winter ’26 made this more granular. You now get visibility into individual step failures instead of just “the IP failed.” This is huge for training data.
Step 2: Capture Integration Procedure Events
Every IP call from your OmniScript logs events. These go into VlocityTrackingEntry__c.
You want to capture:
- Which step failed (IP_StepName__c)
- Input data provided (InputData__c)
- Error returned (ErrorMessage__c)
- How long it took (StepExecutionTime__c)
- Transient vs. persistent (did retry succeed? Did it fail consistently?)
This is your raw training data. Every row is a datapoint your AI model will learn from.
Step 3: Multi-Layer Log Correlation (This Is Critical)
Here’s where most organizations get it wrong: they only look at OmniScript logs.
But OmniScript failures almost always originate from deeper in the stack.
When you train an AI agent, you need to correlate data across:
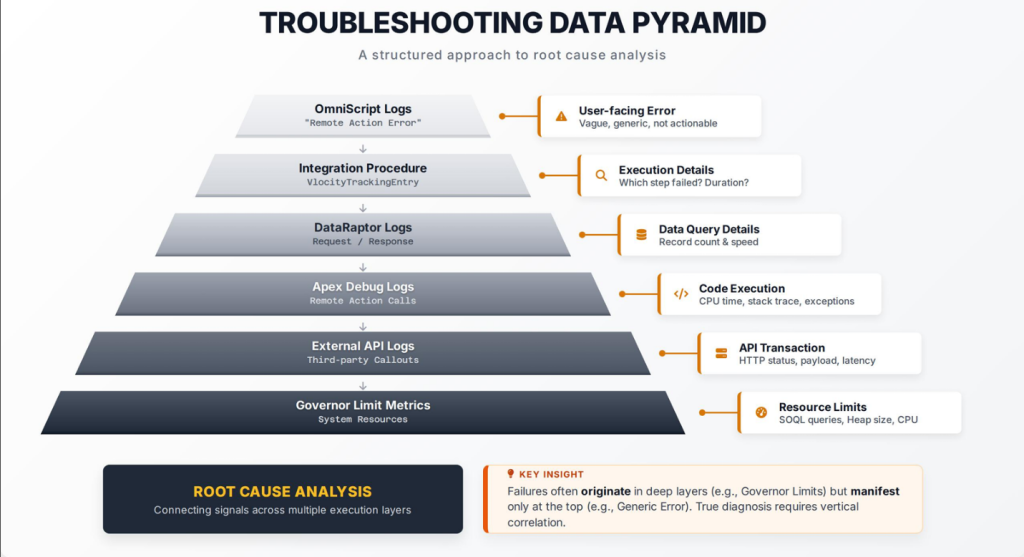
OmniScript Logs → Integration Procedure Logs → DataRaptor Requests/Responses → Apex Debug Logs (Remote Action calls) → External API Callout Logs → Salesforce Governor Limit Logs
Example: You see an Integration Procedure timeout. But is it:
- The number of records being processed? (data volume)
- The time of day? (system load)
- A recent change to that IP?
- A recent schema change?
- API rate limit information?
Only multi-layer correlation answers these questions.
Step 4: How Much Data Do You Actually Need?
Minimum: 2 weeks of continuous data.
Why 2 weeks? Anomaly detection algorithms establish baselines from historical behavior. With only 2 days, the model can’t tell what’s normal.
Realistic minimum: 30 days.
This captures:
- Different times of day with varying system load
- Different user types with different data patterns
- Rare failure modes that only happen occasionally
Optimal: 60-90 days.
With 60-90 days you’ve captured:
- Full monthly cycles
- Month-end closing peaks
- Seasonal patterns
- Rare edge cases that only happen once a month
If you have an org with existing logs? You’re in good shape. If you’re starting from scratch? Plan to collect data for a month before building anything serious.
Four Machine Learning Approaches (And Which One To Actually Use)
Not all machine learning is created equal. When troubleshooting OmniScript failures, you have options. Each has trade-offs.
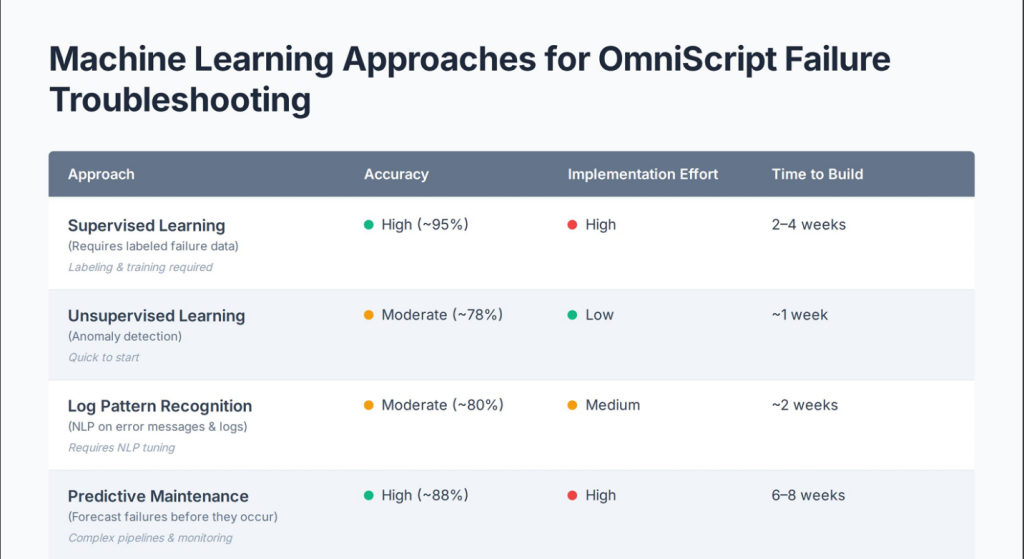
Approach 1: Supervised Learning (The Labeled Data Method)
How it works: You label historical OmniScript executions as “successful” or “failed.” Then you extract features from each execution: execution time, number of IP calls, number of DataRaptor queries, API callout count, data volume, etc. You feed these examples to an algorithm (random forest, gradient boosting, neural networks) and it learns the pattern.
Advantage: High accuracy. If you have 1,000 failure examples and 10,000 success examples, the model learns what separates them with high confidence.
Disadvantage: Labor intensive. Someone has to label 11,000 examples. Failures are easy (they’re in error logs). But you have to manually verify successful executions to ensure consistency.
Practical implementation:
- Extract all failed OmniScript executions from last 90 days
- Extract random sample of successful executions (same time period)
- For each execution, calculate: execution time, IP count, DataRaptor count, API callout count, data volume, timestamp features
- Train a random forest model (it handles mixed feature types well)
- For new executions predicted to fail, inspect feature importance to understand why
Realistic timeframe: 2-4 weeks to label data and train model.
Approach 2: Unsupervised Learning (Anomaly Detection Without Labels)
How it works: You don’t label anything. Just feed all your OmniScript logs (successes and failures mixed) into an anomaly detection algorithm. The algorithm finds which executions are statistical outliers.
Simple concept: if 99% of your executions complete in 500-2000 milliseconds, an execution taking 45 seconds is an outlier worth investigating.
Advantage: No labeling required. The model finds unusual patterns automatically. Can detect entirely new failure modes you’ve never seen before.
Disadvantage: Noise. Not every outlier is a failure. Maybe a slow execution is legitimate (large dataset processing). The system was under heavy load so everything ran slow. The model flags these as anomalies when they’re normal.
Practical implementation:
- Collect all OmniScript execution logs
- Calculate metrics: response time, error presence, retry count, IP failures, DataRaptor timeouts
- Feed into isolation forest or local outlier factor algorithm
- Algorithm returns anomaly score (0 = normal, 1 = very anomalous)
- Flag scores > 0.8 for investigation
Realistic timeframe: 1 week. Much faster than supervised learning.
When to use this: You don’t have clean labels, or you want to discover patterns nobody explicitly documented.
Approach 3: Log Pattern Recognition (NLP on Error Messages)
How it works: Instead of extracting numeric features, you analyze the actual error messages. “Integration Procedure TaxCalculation returned error: TIMEOUT_EXCEEDED” gets parsed. The algorithm identifies the template and groups similar messages.
Then it tracks frequency. “Integration Procedure [*] returned error: TIMEOUT_EXCEEDED” normally happens 1x per day. If you suddenly see it 50x per day, that’s flagged.
Advantage: Works directly with actual messages your system generates. No manual feature engineering.
Disadvantage: Requires good error messages. If your errors are vague (“Something went wrong”), this approach struggles.
Practical implementation:
- Collect all OmniScript error logs
- Use NLP to parse error templates
- Track frequency of each pattern
- Flag sudden spikes
Realistic timeframe: 2 weeks. Requires some NLP expertise.
Approach 4: Predictive Maintenance (Forecast Before Failures Occur)
How it works: You don’t just detect failures after they happen. You forecast failures before they occur.
You collect metrics that precede failures. For example: “IP execution time gradually increases over 4 hours, then timeout occurs.” Or “DataRaptor response time increases 20% above baseline, then failure happens 30 minutes later.”
A predictive model trained on this learns: “When IP execution time increases by 20% compared to moving average, there’s a 78% chance of timeout in the next hour.”
Advantage: Proactive. Alert admins BEFORE users hit errors. Instead of “Your IP failed,” you get “I’ve detected a pattern that typically precedes failures. Check API rate limits.”
Disadvantage: Most complex to implement. Requires understanding what metrics precede failures (which you discover through analysis).
Practical implementation:
- Analyze historical failures to identify leading indicators
- Collect time-series data (metrics over time)
- Train a time-series forecasting model
- Alert when predictions exceed threshold
Realistic timeframe: 6-8 weeks. Requires deep analysis of your failure patterns first.
Building Your First AI Agent: Step-by-Step in Agentforce
Now for the practical part: building this in Agentforce.
Agentforce is Salesforce’s agent platform. Winter ’26 added Observability features that make troubleshooting way easier. Here’s how to actually do this.
Step 1: Create an Agent User
An agent user is a Salesforce integration user with specific permissions. It needs:
✓ Read: OmniComponentErrorLog
✓ Read: VlocityTrackingEntry__c
✓ Read: Integration Procedure records
✓ Read: OmniScript records
✓ Write: Case records (if creating tickets)
✓ Read: Custom Log objects (if you built them)
Principle: Least privilege. Only permissions it needs to troubleshoot.
Step 2: Ground Your Agent With Knowledge
An AI agent without context is useless. It needs to understand:
What you have:
- What OmniScripts exist in your org
- What they do (business purpose)
- What Integration Procedures they call
- What those IPs do
- What DataRaptor mappings are in use
- Recent changes (deployments, config updates)
How to provide this:
- Internal knowledge articles (document your OmniScript architecture)
- Change logs (what changed last week? last month?)
- Historical incident records (root causes your team identified)
- API documentation (external integrations, rate limits, webhook configs)
In Agentforce terms, this is “grounding your agent.” With proper grounding, your agent doesn’t just flag anomalies – it explains them in business terms.
Step 3: Set Up Agentforce Observability (Winter ’26 Feature)
This is new in Winter ’26. It’s a game-changer.
You get:
- Centralized dashboard showing all agent activities
- Real-time monitoring of what your agent is doing
- Debugging tools to simulate error scenarios before production
- Logic tracing showing why the agent reached each conclusion
This matters because AI agents make mistakes. They misinterpret patterns. They draw wrong conclusions. With observability, you catch these mistakes and refine behavior.
Step 4: Build an Integration Procedure That Aggregates Error Data
Your troubleshooting agent needs to query error data constantly.
Create an Integration Procedure called AggregateOmniScriptErrors that:
- Takes as input: date range, OmniScript name, optional error code filter
- Queries OmniComponentErrorLog for failures in that range
- Groups failures by: error type, time of day, user profile, data characteristics
- Calculates failure rate trends
- Returns structured JSON with statistics
This becomes your agent’s data source.
Step 5: Create Agent Actions
In Agentforce, Agent Actions are things your agent can execute.
Create an action:
- Type: Integration Procedure
- Reference: AggregateOmniScriptErrors
- Input params: date range, OmniScript name
- Output: Shows failure analysis in conversation
Step 6: Define Agent Topics
A “topic” is something your agent knows how to handle.
Your agent should have topics like:
- “Investigate OmniScript timeout”
- “Diagnose Integration Procedure failure”
- “Identify DataRaptor issues”
- “Why are timeout errors spiking?”
- “Which users were affected?”
Step 7: Write Agent Instructions
This is where you teach your agent the patterns.
Example instruction:
“When asked about OmniScript failures:
- Always run AggregateOmniScriptErrors for the requested date range
- Examine error patterns
- If TIMEOUT_EXCEEDED errors spike between 2-3 PM, this indicates API rate limiting
- Recommend checking external API quota usage
- Suggest implementing exponential backoff in Integration Procedure”
Step 8: Test With Simulation Mode
Before deploying to production, use Agentforce’s simulation mode.
Test scenarios:
- Scenario 1: User reports 50 failures at 2:30 PM → Agent should identify timeout pattern
- Scenario 2: User reports failures affecting only one profile → Agent should check permissions
- Scenario 3: User reports failures only after recent deployment → Agent should check deployment changes
Root Cause Analysis: Teaching Your Agent to Dig Deeper
Detecting failures is one thing. Finding root causes is another.
The 5 Whys: Training Your Agent to Question
You start with an observation and ask “why” five times.
- Why did OmniScript fail? → Integration Procedure timeout
- Why did IP timeout? → API call was slow
- Why was API slow? → External service under load
- Why was external service under load? → They were running database maintenance
- Why didn’t we know about maintenance? → No monitoring of their status page
You teach your agent this technique:
Agent Instructions for RCA:
First: What error did the IP return?
Second: Check IP execution logs. Did a specific step timeout? Did an API return error?
Third: If API error, check response code. 429 = rate limiting, 5xx = server error
Fourth: For rate limiting, check request volume. For server errors, check their status page
Fifth: Recommend preventive measures (retry logic, fallback, monitoring)
The Fishbone Diagram: Organizing Root Causes
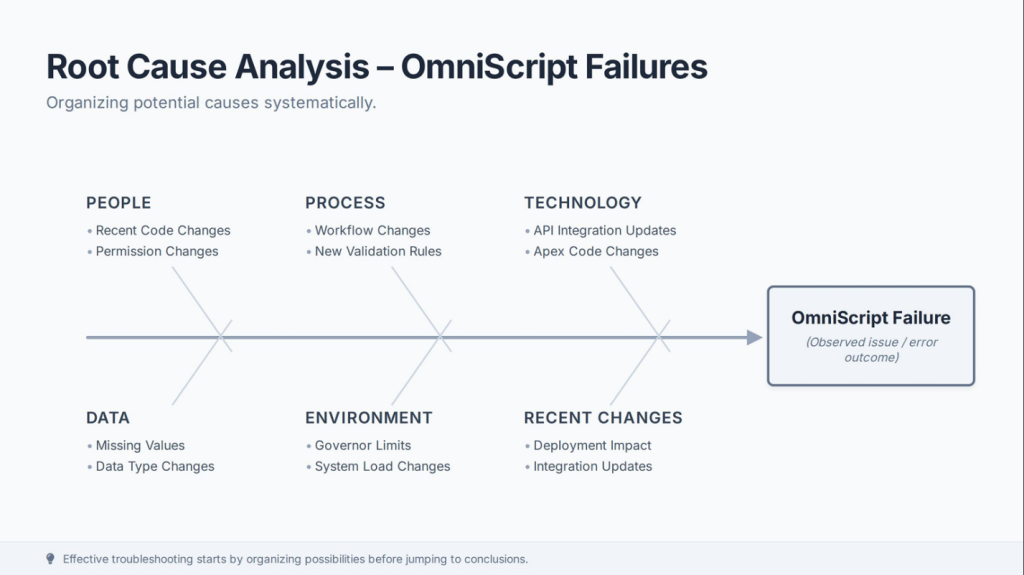
Fishbone (Ishikawa) categorizes potential causes:
PEOPLE → Recent code change, Permission changes
PROCESS → Workflow change, New validation
TECHNOLOGY → API integration update, Apex code change
DATA → Data type changes, Missing values
ENVIRONMENT → Governor limits, System load
Your agent applies this framework:
When investigating failures:
- Check Timeline: What changed in last 7 days?
- Check People: Did anyone modify OmniScript/IP/Apex?
- Check Process: Did validation rules change?
- Check Data: Are there new field values?
- Check Environment: Are we hitting governor limits?
Machine Learning for Root Cause Inference
Beyond manual techniques, you train ML models specifically for root cause prediction.
You collect:
- Observed symptoms (timeout, error type, affected users)
- Root causes (identified by your team)
- Contributing factors (recent deployments, data changes)
The model learns patterns:
“Timeout errors + small data + no recent changes = external API issue”
“Timeout errors + large data + recent deployment = performance regression”
With this model, your agent makes informed guesses about root causes, dramatically speeding troubleshooting.
The Messy Part: False Positives and Model Drift
Nobody talks about this, but AI agents in production aren’t perfect. They make mistakes.
False Positives: When Your Agent Cries Wolf
Your model flags an OmniScript as “likely to fail” when it actually succeeds.
Why? Maybe the system was under heavy load that day, so everything ran slow. But it didn’t actually fail.
If your agent raises false alarms too often, people stop trusting it. They ignore recommendations. You lose the benefit entirely.
How to handle this:
First: Tune thresholds carefully. Don’t flag executions deviating by 20%. Set threshold high enough that you’re catching real problems. Aim for 95% normal / 5% flagged.
Second: Implement feedback loops. Agent predicts failure. System observes actual outcome. If agent was right, great. If wrong, log that mismatch. Use mismatches to retrain and improve accuracy.
Third: Always provide context. Not “OmniScript likely to fail.” But “OmniScript execution time is 3x slower than normal (likely system load), but historical data shows it still completes 95% of the time. Proceed with caution.”
Model Drift: When Yesterday’s Patterns Stop Working
Your model trains on 2024 data. Becomes very good at predicting based on those patterns.
Then it’s February 2025. You:
- Upgraded infrastructure
- Changed API endpoints
- Hired new developers with different coding patterns
- Migrated to new external service
Suddenly your model’s predictions are way off. It learned patterns that no longer apply. This is model drift.
How to prevent it:
Continuous retraining: Don’t train once and leave. Retrain monthly or quarterly with recent data. Model should get better as you collect more data.
Performance monitoring: Track accuracy over time. Precision dropping? Recall dropping? Time to retrain.
Version control: Keep multiple model versions. New model performs worse? Quickly rollback.
Human validation: For high-impact predictions, have humans verify before taking action.
What’s Actually Coming in 2026?
Salesforce is investing heavily in AI troubleshooting.
Agentforce Observability (Winter ’26 – Available Now)
Centralized dashboard for monitoring agents. You see:
- What agent is doing in real-time
- What data it’s querying
- What decisions it’s making
- Why it made those decisions
- Success rates for different tasks
Critical because it validates your agent actually works correctly.
Enhanced Logging (Winter & Spring ’26)
Integration Procedure error logs are getting more granular. New fields in OmniComponentErrorLog give better failure context.
Spring ’26 adds IF statements to Formula Elements in Integration Procedures. Gives you more flexible error handling.
New Agentforce Builder (Beta in Winter ’26)
Design agents using natural language instead of complex instructions.
Most important: simulation mode. Before deploying to production, simulate thousands of scenarios. See how the agent responds. Catch mistakes before they affect users.
Einstein Studio Model Customization
Available now. Customize AI models for your specific use cases. Adjust temperature, frequency penalty, presence penalty.
For troubleshooting, tune for precision (low temperature, high penalties). You want focused recommendations, not creative hypotheticals.
Agent Script (Spring ’26)
Define deterministic logic in agent flows. Troubleshooting agents shouldn’t be probabilistic. They should follow structured logic paths.
IF Integration Procedure error = ‘TIMEOUT_EXCEEDED’ AND time = 14:00-15:00 THEN recommend checking API rate limits
Your 6-Phase Implementation Roadmap
Phase 1: Data Foundation (Month 1-2)
- Enable OmniComponentErrorLog and IP event tracking
- Start collecting logs from all OmniScripts
- Set up queries to analyze failure patterns
- Document your OmniScript architecture
Phase 2: Initial Anomaly Detection (Month 3-4)
- Analyze 60-90 days of historical data
- Implement unsupervised anomaly detection
- Test against actual failure logs
- Tune thresholds, identify false positives
Phase 3: Build Your First Agent (Month 5-6)
- Create troubleshooting agent in Agentforce for critical OmniScript
- Define topics and actions
- Connect to aggregation Integration Procedures
- Use Observability to monitor and refine
Phase 4: Supervised Learning & RCA (Month 7-9)
- Collect labeled training data
- Train supervised learning models for failure prediction
- Implement 5 Whys and Fishbone techniques
- Teach agent to apply these techniques
Phase 5: Scale & Optimize (Month 10-12)
- Extend agent to handle multiple OmniScripts
- Implement continuous retraining
- Set up performance monitoring
- Reduce false positives
Phase 6: Advanced Features (2026+)
- Implement predictive maintenance
- Use Spring ’26 Agent Script
- Experiment with custom Einstein Studio models
- Integrate with incident management
Real Implementation Challenges
Challenge 1: Getting Historical Data
If your org is new, you have zero training data. You have to wait. For at least a month. Maybe two.
Solution: Start logging NOW even if you can’t build the agent yet. By the time you’re ready to build, you’ll have data.
Challenge 2: Labeling Data
Supervised learning requires labeled examples. Failures are easy to identify. Success is harder to define.
Solution: Define “success” clearly. “No errors AND execution time < 5 seconds” for example. Then stick with that definition.
Challenge 3: External API Variability
Your IP calls an external API. That API is sometimes slow. Sometimes fast. Same endpoint, same data, different performance.
This makes patterns hard to identify.
Solution: Track API performance metrics separately. Your model learns “API was slow on Tuesday at 2 PM, so slower IP execution is normal.”
Challenge 4: False Positive Burnout
You deploy your agent. First week, it’s great. Then it starts flagging things that aren’t actually problems.
Your team stops trusting it. Stops reading its recommendations.
Solution: Be conservative with thresholds initially. Better to miss some problems than annoy your team with false alarms.
Challenge 5: Keeping Knowledge Updated
You document “Integration Procedure XYZ calls external API at vendor.com.” Six months later, they change their API.
Your agent still recommends checking the old endpoint.
Solution: Implement a knowledge update process. When you change an IP or external integration, update agent knowledge base immediately.
Conclusion: This Is Happening. You Can Lead or Follow.
Training an AI agent to troubleshoot OmniScript failures isn’t futuristic anymore. The tools exist. Agentforce Observability is available now. Einstein generative AI is built in. The logging infrastructure is there.
What’s missing in most organizations isn’t technology. It’s a structured approach to building these agents. It’s willingness to invest in the foundation (data collection) before jumping to fancy ML models.
Here’s what happens:
You start by enabling logging. Boring. Unglamorous. But critical.
You collect 60-90 days of data. You’re not building anything yet. Just collecting.
Then you run anomaly detection against that data. Nothing fancy. Just “find the outliers.”
You look at those outliers. Some are real problems. Some are false positives. You tune your threshold.
Once you’re confident in your detection, you build your first Agentforce agent for your most critical OmniScript.
You test it with simulation mode. You catch mistakes before production.
You deploy. It helps. It also makes mistakes. You document those mistakes. You retrain.
A few months in, your agent is actually useful. You extend it to another OmniScript. Then another.
A year in? Your team is spending way less time reading error logs. Spending way more time building features.
That’s the journey.
The teams that figure out AI-driven troubleshooting first will have significant advantage. They’ll move faster, resolve issues quicker, spend less time in firefighting mode. That advantage compounds.
So start now. Don’t wait for the “perfect” moment. Enable logging today. Collect data this month. Build your first agent next month.
Join the organizations turning OmniScript troubleshooting from a manual nightmare into something actually intelligent and automated.
Your future self will thank you.
Ready to Implement AI-Driven OmniScript Troubleshooting?
This journey from manual troubleshooting to AI-powered pattern recognition isn’t quick, but it’s worth every month of investment. Start enabling error logging today – your team will thank you when they’re spending less time in error logs and more time building.
Explore more Salesforce OmniStudio insights:
YouTube: https://www.youtube.com/@2CreativeSolutions – Watch practical implementation tutorials
Website: https://2creative.ca/ – Read more technical guides and case studies
LinkedIn: https://www.linkedin.com/company/2cretiv – Stay updated on latest Salesforce innovations
If you’ve spent the last three years watching your sales team battle spreadsheets while finance teams manually reconcile invoices against outdated quotes, you’re not alone. Revenue Cloud Advanced (RCA) to fix quote-to-cash pipelines has become the go-to solution for enterprises drowning in operational friction. The problem isn’t new – it’s old. But the solution is finally here, and it’s native to Salesforce.
This isn’t a marketing pitch. This is what’s actually happening in enterprise revenue operations, and the results speak for themselves.
The Real Problem: Where Quote-to-Cash Breaks Down
Before we talk about Revenue Cloud Advanced and how it fixes these broken Quote-to-Cash pipelines, let’s be honest about what “broken” looks like.
The Disconnection Between Systems
Your sales team closes a deal. They’ve configured a complex bundle – let’s say it’s a SaaS platform with add-ons, usage-based features, and a subscription term. The quote looks pristine in Salesforce. Then it gets signed, and something happens on the way to fulfillment.
The order management system doesn’t recognize one of the bundled components. It wasn’t coded into the fulfillment rules. Finance sees a quote for $50,000 but receives an order for $47,000 (with discounts that somehow didn’t transfer). The billing system, disconnected from both, starts generating invoices based on old pricing information.
This isn’t a glitch. It’s the architecture of legacy systems talking to each other through duct tape and custom integrations.
In a 2025 study by Gartner, enterprises can lose 1-5% of EBITDA annually due to revenue leakage tied directly to quote-to-cash breakdowns. That’s not theoretical. That’s millions of dollars per company.
The Manual Process Trap
| Stage | Legacy System Reality | Time Impact | Error Risk |
| Quote Creation | Sales rep builds in spreadsheet, manually applies rules | 3-4 hours | High – manual discount errors, forgotten constraints |
| Pricing Calculation | Multiple systems replicate logic differently | +2-3 days | Critical – quote vs. order price mismatch |
| Approval Routing | Manual email chains, unclear ownership | +5-7 days | High – approvals get stuck or overlooked |
| Contract Generation | Legal manually creates from quote template | +2-3 days | Medium – terms don’t always match quote |
| Order Creation | Manual data entry from approved quote | +1-2 days | High – fields omitted, values mistyped |
| Fulfillment Routing | Manual assignment to fulfillment teams | +1-2 days | High – fulfillment ignores terms, discovers issues late |
| Billing Setup | Finance manually configures invoice schedule | +3-5 days | Critical – billing doesn’t match contract |
| Total Time | 14-21 days | — | Multiple error points |
Manual Processes Creating Latency and Errors
When quotes get complex, your sales team often resorts to Word documents and Excel spreadsheets. Why? Because your CPQ system can’t handle the complexity of your actual products and pricing models.
A customer asks for a modified configuration. Your rep updates the quote in a spreadsheet. It takes a week to push through approval workflows. By then, the customer lost interest. Meanwhile, fulfillment discovers the quote violates service qualification rules, requiring yet another revision.
Every manual step introduces two things: delay and risk. Delay costs you deals. Risk costs you revenue.
The Subscription and Amendment Nightmare
If you’re managing recurring revenue, amendments and renewals are where your systems truly fracture. A customer wants to upgrade mid-contract. You adjust the quote manually. Billing doesn’t know about it. Finance has to manually adjust revenue recognition schedules.
And then there are proration calculations. One miscalculation, one missed field update, and suddenly your customers are overcharged or undercharged. You’re issuing credits, management is asking questions, and your team is buried in manual fixes.
The fundamental issue? Your existing systems – whether it’s Salesforce CPQ paired with a separate billing tool, or legacy on-premise solutions – were architected for a different era. They don’t talk to each other. They don’t scale. And they certainly don’t handle modern business models like usage-based pricing or multi-currency, multi-entity contracts.
Enter Revenue Cloud Advanced: A Different Architecture
Revenue Cloud Advanced is built on a premise that makes obvious sense now but was genuinely revolutionary when Salesforce started this journey: the entire quote-to-cash lifecycle should live in one platform, with one source of truth.
Not one integrated system. One platform.
The Native Architecture Difference
Here’s the core distinction: Revenue Cloud Advanced isn’t a managed package layered on top of Salesforce (like legacy CPQ tools). It’s natively built on Salesforce’s Einstein 1 Platform, which means:
- It follows Salesforce’s release schedule. New features every quarter, not every two years.
- It scales with Salesforce’s infrastructure. No separate database to manage, no sync delays.
- It leverages Salesforce’s API-first architecture, meaning headless implementations and real-time data flow are the default, not a special request.
When you configure a quote in Revenue Cloud Advanced, that configuration doesn’t need to be translated, mapped, or transformed before it reaches order management. The data lives in the same system. It’s one version of truth.
Seven Pillars That Actually Work Together
Revenue Cloud Advanced is built around seven interconnected pillars, and here’s the critical part: they’re not separate modules. They’re integrated components of a unified platform.
RCA Seven Pillars Architecture

Product and Service Design: Build your product catalog once, with dynamic attributes that can be reused across variations. In legacy CPQ, adding a new attribute means recreating dozens of product records. In RCA, you define the attribute once and apply it across your catalog. This alone cuts product setup time by 60-70%.
Pricing Management: Pricing waterfalls, tier-based discounts, customer-specific pricing, region-based adjustments – all configured in one place. When you adjust a discount rule, it instantly cascades through every quote, order, and invoice calculation. No spreadsheet updates. No manual syncing.
Configure, Price, and Quote (CPQ): Yes, RCA includes CPQ, but it’s not the traditional “pull products, apply rules, generate quote” flow. It’s guided selling with AI, real-time price calculation, constraint-based configuration that prevents invalid combinations, and automated workflows that move quotes from draft to signature in hours instead of days.
Contract Lifecycle Management (CLM): Generate contracts from quotes automatically. Embed obligations and compliance tracking. When a contract is amended, the system updates assets, recalculates revenue, adjusts billing schedules, and generates new invoices – all without manual intervention. This is contract management that actually works at scale.
Order Management: Orders are created directly from quotes. They’re pre-validated against your fulfillment capabilities, inventory availability, and service qualifications. When Dynamic Revenue Orchestration kicks in, complex orders get decomposed into manageable fulfillment steps, each with dependencies and automation triggers.
Billing: Invoices are generated from active orders on a configurable schedule. Billing automatically reflects everything in the quote and contract – discounts, payment terms, usage data (for consumption-based models), proration rules for amendments, and renewal schedules. Your billing team stops managing spreadsheets. They start managing billing policies.
Revenue Lifecycle Intelligence: Real-time dashboards show pipeline health, deal velocity, churn risk, renewal schedules, and revenue forecasts. Finance teams get accurate, compliant revenue recognition (ASC 606 / IFRS 15) without manual journal entries. Sales teams see which deals are at risk. Everyone’s operating from the same data.
How RCA Actually Fixes Broken Pipelines: Real Mechanics
Talking about architecture is fine. Let’s talk about what actually changes when you implement Revenue Cloud Advanced to fix quote-to-cash pipelines.
1. Eliminating the Catalog Problem
In most enterprises using legacy systems, product data is a mess. Your product catalog in Salesforce doesn’t match your fulfillment system. SKUs are named differently. Bundles have different hierarchies. Nobody’s sure which products are actually available.
Revenue Cloud Advanced introduces Product Catalog Management (PCM). You define products once. You attach attributes (e.g., “memory size,” “storage capacity,” “support level”) to attribute categories. Then you create product classifications – think of these as templates that automatically apply attributes to new products.
Here’s the mechanical benefit: when your sales team configures a laptop bundle in a quote, they’re not manually assembling pieces. They’re selecting from predefined, constrained options. The system automatically validates: “If you choose 16GB RAM, you can’t also choose the low-performance processor.” These constraints are built into the Advanced Configurator, which can process 10,000+ configurations per second.
The fulfillment team sees the exact same product configuration the customer agreed to. No translation needed. No discovery of incompatibilities three weeks later.
Product Catalog Hierarchy in RCA
| Level | Component | Example |
| 1. Product | Base sellable item | “Cloud Storage Service” |
| 2. Attributes | Product characteristics | Storage capacity (10GB, 50GB, 100GB), Support tier (Basic, Premium, Enterprise) |
| 3. Attribute Categories | Groupings for organization | Infrastructure Attributes, Support Attributes |
| 4. Product Classification | Template for automatic attribute assignment | SaaS Enterprise Template (auto-assigns Premium Support, 100GB storage) |
| 5. Bundles | Multi-product offerings | “Enterprise Package” = Cloud Storage + Support + Advanced Analytics |
| 6. Dynamic Attributes | Configurable during quote | Seat count (1-1000), Regional deployment zone |
2. Pricing Accuracy Through Pricing Procedures and Price Waterfalls
Pricing in legacy systems is opaque. A rep applies a discount, but nobody’s really sure how it interacts with volume tiers, regional adjustments, customer-specific contracts, and proration rules.
Revenue Cloud Advanced includes Pricing Procedures – a declarative engine that calculates price step by step. You define:
- Base price (list price or cost-plus)
- Volume discounts (tiered or percentage-based)
- Regional adjustments (by geography or market segment)
- Customer-specific pricing (by account, contract, or tier)
- Time-based adjustments (seasonal, promotional)
- Usage-based components (for consumption pricing)
Sample Price Waterfall Calculation
Product: SaaS Platform License (50 users)
─────────────────────────────────────────────────
Step 1: List Price
└─ 50 users × $200/user/month = $10,000/month
Step 2: Volume Discount (51-100 users = 10% off)
└─ Applied: $10,000 × 0.90 = $9,000/month
Step 3: Regional Adjustment (APAC = 15% surcharge)
└─ Applied: $9,000 × 1.15 = $10,350/month
Step 4: Customer-Specific VIP Contract (12-month commitment = 8% off)
└─ Applied: $10,350 × 0.92 = $9,522/month
Step 5: Promotional Period (Winter 2025 launch = 5% off)
└─ Applied: $9,522 × 0.95 = $9,045.90/month
─────────────────────────────────────────────────
FINAL QUOTED PRICE: $9,045.90/month
(Discount summary: 28.5% from list price)
Each step is visible in a Price Waterfall. Your sales rep can show a customer exactly where the final price comes from. When the quote converts to an order, those same pricing procedures calculate the actual invoice. No replication of logic. No manual overrides. Same rules, same result.
3. Setup Rules and Constraint Models: Preventing Invalid Configurations
This is where Salesforce RCA starts to feel genuinely different. Setup rules (or constraint models) are guardrails for your business logic.
Let’s say you sell telecommunications services. A customer can bundle:
- Basic connectivity (required)
- Premium support (optional)
- Network monitoring (only available with premium support)
Valid combinations:
- ✅ Basic connectivity + no premium support
- ✅ Basic connectivity + premium support
- ✅ Basic connectivity + premium support + network monitoring
Invalid combination:
- ❌ Basic connectivity + network monitoring (no premium support)
Constraint Model Example: Telecom Service Bundle Rules
| Rule Name | Logic | Outcome |
| Connectivity Required | Connectivity must always be selected | Block config if connectivity = empty |
| Monitoring Requires Premium Support | If Monitoring = Enabled, then Support must be Premium | Block config if (Monitoring=”Enabled” AND Support≠”Premium”) |
| Premium Support Allows Monitoring | Premium Support can include monitoring | Allow combination of Premium Support + Monitoring |
| Basic Support Blocks Monitoring | If Support = Basic, Monitoring must be disabled | Disable Monitoring field when Support=”Basic” |
| Max Bundle Size | Prevent oversized bundles (cost control) | Block if bundle components > 5 items |
In legacy CPQ, you’d write complex product rules, stacking them like: selection rule, validation rule, alert rule. The logic gets hard to maintain.
In Revenue Cloud Advanced, you define a constraint model. In the visual builder (or using the Constraint Modeling Language for power users), you sketch out the valid combinations:
constraint(
OR(
AND(connectivity == “basic”, support == “none”),
AND(connectivity == “basic”, support == “premium”),
AND(connectivity == “basic”, support == “premium”, monitoring == “enabled”)
),
“Invalid combination”
);
The Advanced Configurator checks this in real-time as your rep configures. Invalid combinations are blocked before the quote even gets to approval. This cuts quote errors by 80-90% in most implementations.
4. Subscription and Amendment Workflows That Actually Scale
This is where enterprises with subscription revenue models see the biggest win.
Subscription Lifecycle States

When you set up a subscription product in RCA, you define:
- Subscription type (annual, monthly, evergreen)
- Subscription term (12 months, 24 months, open-ended)
- Proration policy (for mid-term changes)
- Renewal behavior (automatic renewal, override renewal term, no renewal)
When an order is created from a subscription quote, RCA tracks the asset lifecycle. Your sales team (or customer success team) can:
Amend the subscription mid-term: Customer wants to upgrade from 10 to 20 user seats. RCA calculates the prorated charge based on the remaining term. It creates a new amendment order, generates an updated invoice, adjusts revenue recognition schedules, and updates the billing system – all automatically. No spreadsheet. No finance team intervention. No delays.
Renew the subscription: At renewal, RCA lets your team choose automatic renewal (extends the existing term) or override renewal term (change the term length). It creates a renewal order, adjusts the asset lifecycle, and schedules new billing.
Cancel the subscription: If the customer wants out, RCA handles the cancellation date, calculates any remaining credits, updates the asset, and stops future billing – all in one action.
Each of these actions updates the revenue recognition schedule automatically, so your finance team’s books stay clean without manual adjustments.
5. Dynamic Revenue Orchestration: Making Complex Orders Manageable
Here’s a scenario that breaks most systems: A global enterprise customer orders a complex bundled solution. They’re buying software (immediate delivery), custom implementation services (over three months), hardware (needs to be manufactured), and ongoing support (starts on day one).
The order needs to be:
- Partially fulfilled immediately (software license, support begins)
- Queued for manufacturing (hardware, 4-week lead time)
- Scheduled as project work (implementation, starts after hardware delivery)
- Billed differently for each component (software upfront, services monthly, hardware on delivery, support recurring)
Dynamic Revenue Orchestration: Complex Order Decomposition
CUSTOMER ORDER
“Enterprise Software + Implementation + Hardware + Support”
│
▼
DRO DECOMPOSITION
(Split by fulfillment & billing type)
│
▼
┌─────────────┬─────────────────┬─────────────┬─────────────┐
│ SOFTWARE │ IMPLEMENTATION │ HARDWARE │ SUPPORT │
│ LICENSE │ SERVICES │ │ │
└─────────────┴─────────────────┴─────────────┴─────────────┘
│ │ │ │
│ │ │ │
▼ ▼ ▼ ▼
SOFTWARE HARDWARE SUPPORT
──────── ──────── ───────
Deploy (Day 1) Manufacture (Day 1) Activate (Day 1)
Invoice $50K (Upfront) Lead Time: 4 weeks $2K / month
Activate Asset QA Review (Day 28) Recurring
│
▼
IMPLEMENTATION
──────────────
Start: Day 29
Duration: 3 months
Billing: $10K / month
(Depends on Hardware QA)
Billing Timeline
Month 1 : Software $50K + Support $2K = $52K
Month 2 : Services $10K + Support $2K = $12K
Month 3 : Services $10K + Support $2K = $12K
Month 4 : Services $10K + Support $2K = $12K
Month 5+: Support $2K / month
In legacy systems, this becomes a manual nightmare. Fulfillment tracks pieces in different systems. Finance reconciles invoices manually. The customer gets confused because fulfillment, billing, and support aren’t aligned.
Dynamic Revenue Orchestration (DRO) in Revenue Cloud Advanced lets you define this upfront. You create a fulfillment plan that:
- Decomposes the order into fulfillment-relevant components (software, hardware, services, support)
- Chains steps with dependencies (hardware must complete before implementation starts)
- Assigns manual tasks where needed (QA review, customer sign-off)
- Handles exceptions (if hardware is delayed, what happens to the implementation schedule?)
- Updates the billing and asset management systems as steps complete
From a single order, DRO automatically orchestrates work across teams and systems. Your customer gets accurate progress updates. Billing knows exactly what to invoice and when. Finance has clean revenue recognition because every completion milestone is tracked.
6. Revenue Recognition That Stays Compliant
ASC 606 and IFRS 15 changed the revenue recognition game. Revenue is recognized when control of goods or services transfers to the customer, not when payment is made. This creates complexity for companies with multi-year contracts, installment payments, or performance obligations that span time periods.
Revenue Recognition for Complex Contracts
Customer Contract: $100,000 total value
Performance Obligations Identified:
───────────────────────────────────
1. SOFTWARE LICENSE (Point in time)
└─ Control transfers: Day 1 (deployment)
└─ Revenue recognized: $40,000 (Day 1)
2. IMPLEMENTATION SERVICES (Over time)
└─ Control transfers: Monthly (as services are delivered)
└─ Duration: 3 months
└─ Revenue recognition: $30,000 ÷ 3 = $10,000/month
├─ Month 1: $10,000
├─ Month 2: $10,000
└─ Month 3: $10,000
3. ANNUAL SUPPORT (Over time)
└─ Control transfers: Monthly
└─ Duration: 12 months
└─ Revenue recognition: $30,000 ÷ 12 = $2,500/month
Revenue Recognition Schedule (Auto-generated by RCA):
──────────────────────────────────────────────────────
| Month | License | Implementation | Support | Total Rec. | Deferred |
|——-|———|—————–|———|———–|———-|
| 1 | $40,000 | $10,000 | $2,500 | $52,500 | $47,500 |
| 2 | — | $10,000 | $2,500 | $12,500 | $35,000 |
| 3 | — | $10,000 | $2,500 | $12,500 | $22,500 |
| 4-12 | — | — | $2,500 | $2,500 | $0 |
| | | | | **$100K** | |
RCA Updates Schedule Automatically On Amendments:
──────────────────────────────────────────────────
IF Customer adds: “Premium Support” (+$1,000/month) in Month 2
THEN: New performance obligation created, revenue schedule recalculated,
ERP gets updated journal entries automatically.
Revenue Cloud Advanced includes revenue recognition automation that:
- Splits contract value across performance obligations (subscription + implementation + support = three separate revenue lines)
- Creates revenue schedules based on when control transfers
- Adjusts schedules when contracts are amended (customer adds features mid-term, you recalculate the deferred revenue)
- Integrates with your ERP (NetSuite, SAP, Oracle) so finance has one view of truth
Your finance team stops managing spreadsheets of revenue schedules. The system maintains compliance automatically.
7. Real-Time Visibility That Changes How Teams Operate
Here’s what changes psychologically when you implement RCA correctly: your teams start operating from the same data.
Real-Time Dashboards by Role
Sales Leadership Dashboard
PIPELINE HEALTH
────────────────────────────────
Total Pipeline Value $4.2M
Expected Close (30 days) $850K
Avg Deal Velocity 12.5 days
Deals at Risk (churn) 3
Deals Stalled (10+ days) 7
[ Pipeline by Stage + Velocity ]
[ Risk & Churn Indicators ]
Finance – Revenue Forecasting (Auto-Updated)
REVENUE FORECAST
────────────────────────────────
Q4 2025
Recognized Revenue $2.1M (75%)
Deferred Revenue $580K
Q1 2026 (Forecast)
From Current Contracts $1.8M
From Renewals $320K
From New Deals $890K
Forecast Total $3.01M
Confidence Level 85%
[ Forecast vs Historical Trend ]
[ Renewal Pipeline View ]
Operations – Fulfillment Status
FULFILLMENT STATUS
────────────────────────────────
Open Orders 23
On Track 19 (83%)
At Risk 4 (17%)
By Component
Software Delivery 23 / 23 complete
Hardware Manufacturing 15 / 23 in queue
Implementation Services 8 / 23 in progress
Support Activation 19 / 23 active
Top Exceptions
• OD-5623 Hardware delayed (+5 weeks)
• OD-5641 Implementation blocked
• OD-5789 Customer sign-off pending
[ Fulfillment Timeline vs SLA ]
Sales sees a unified pipeline dashboard: which deals are stalled, which are moving toward signature, which are at risk of cancellation (based on churn prediction from historical patterns).
Finance sees real-time revenue forecasting: based on active quotes, signed contracts, and upcoming renewals, here’s our expected revenue for next quarter and beyond. No wait for sales to provide updated forecasts. It’s live.
Operations sees order fulfillment status: orders decomposed by component, fulfillment steps with live status, exceptions that need manual intervention, and customer delivery dates.
Billing sees invoicing queue: which orders are ready to bill, which are waiting on fulfillment completion, which customers have outstanding payments, and which renewals are coming due.
Every team has a dashboard that’s a reflection of the same platform. Decisions are made faster because nobody’s reconciling conflicting versions of truth.
Real-World Impact: What Enterprises Actually See
Let’s ground this in what’s actually happening at companies using Revenue Cloud Advanced to fix quote-to-cash pipelines.
Impact Metrics Across Industries
| Metric | Before RCA | After RCA | Improvement | Business Impact |
| Quote-to-Signature Time | 14-21 days | 2-3 days | 85-90% faster | 12-15 additional deals closed per quarter |
| Quote Error Rate | 8-12% | 0.5-1% | 85-90% reduction | 90% fewer billing disputes, manual credits |
| Revenue Leakage (Annual) | $2-3M | $400-600K | 70-80% reduction | Direct EBITDA impact: $1.4-2.6M recovered |
| Finance Processing (Monthly Hours) | 40 hours | 4 hours | 90% reduction | Equivalent to 0.5 FTE freed up annually |
| Amendment Processing Time | 5-7 days | <1 day | 85-90% reduction | Customer satisfaction: faster mid-term upgrades |
| Renewal Quote Generation | 3-4 hours (manual) | 15 minutes (auto) | 80% faster | 100+ renewals/quarter vs. 30 previously |
| Billing Accuracy | 95% (manual reconciliation) | 99.5% (automated) | 4.5% improvement | Invoice-to-cash cycle improves 10+ days |
| Revenue Forecast Accuracy | 75-80% | 95%+ | 15-20% improvement | Better capital planning, quarterly predictability |
Real-World Case: SaaS Company Transformation
Company Profile: Global B2B SaaS with 400+ enterprise customers, $80M ARR, complex bundling
Before RCA:
- Average 14-day quote-to-signature cycle
- Sales reps spending 4+ hours on complex quotes
- $2.3M annual revenue leakage (quote-to-billing misalignment)
- Finance team: 40 hours/month reconciling revenue schedules
- 30% of renewals missed due to manual process delays
After RCA (6 months):
- Average 2-hour quote-to-signature cycle
- Guided selling reduces configuration time to 20 minutes
- Revenue leakage: $400K annually (83% reduction)
- Finance team: 4 hours/month policy review (90% time savings)
- 100+ renewals processed quarterly (vs. 30 previously)
- Revenue forecast accuracy: 97% (vs. 76% previously)
Financial Impact:
- EBITDA improvement: +$1.9M annually
- Equivalent to hiring 5-7 sales operations staff
- 18-month ROI on implementation investment
Real-World Case: Insurance Company
Company Profile: Enterprise insurance provider, 500+ enterprise policies, complex amendments
Before RCA:
- Amendments took 5-7 days (manual review and re-billing)
- 40 hours/month ASC 606 compliance reconciliation
- Churn rate: 18% (partially due to slow amendment process)
After RCA (4 months):
- Amendments processed in <1 day (automated)
- 4 hours/month compliance review (90% time savings)
- Churn rate: 14% (4 percentage point improvement)
- Customer satisfaction NPS: +15 points
Financial Impact:
- Churn reduction worth $3.2M annually
- Operational cost savings: $400K annually
- Total value: $3.6M, ROI exceeded in Year 1
The Implementation Reality: What You Need to Know
Revenue Cloud Advanced isn’t a flip-a-switch implementation. But it’s also not the 18-month behemoth that legacy CPQ implementations became.
Implementation Timeline & Complexity Matrix
IMPLEMENTATION TIME
▲
│ ● Enterprise (9+ months)
│
│ ● Mid-Size (5–6 months)
│
│ ● Simple (3–4 months)
│
└──────────────────────────────────────────►
Data Pricing Custom Global Legacy
Quality Logic Config Rules Systems
Implementation Phases Breakdown
| Phase | Timeline | Activities | Team Involvement |
| Discovery & Planning | 2-4 weeks | Define requirements, map current state, identify quick wins, scope data migration | Product, Sales, Finance, IT |
| Data Foundation | 4-8 weeks | Product catalog cleanup, pricing logic documentation, customer data consolidation | Product, Finance, Data teams |
| Build & Configure | 6-12 weeks | Advanced Configurator setup, constraint models, pricing procedures, CLM templates | Salesforce Architects, Business Analysts |
| Testing & QA | 3-4 weeks | UAT by business users, performance testing, security review | QA, End Users, Security team |
| Go-Live Preparation | 2-3 weeks | Training, data cutover planning, support desk readiness | Training, Operations, Support |
| Phased Rollout | 4-12 weeks | Phase 1: New products/regions; Phase 2: Renewals; Phase 3: Legacy migration | Everyone |
| Optimization & Handoff | Ongoing | Tuning, user adoption tracking, continuous improvement | Support, Business teams |
Planning the Data Foundation
First, you’re mapping your product catalog. Not as it exists in disparate systems, but as it should exist: atomic products with reusable attributes, organized in catalogs and classifications.
You’re documenting your pricing logic: discounts, regional adjustments, customer-specific terms, usage-based components. These become pricing procedures.
You’re identifying your constraint rules: which product combinations are valid? When is a bundle complete? What messages should appear?
If you’re coming from Salesforce CPQ, you’re reverse-engineering existing product rules (which often start simple and become a tangled mess after five years) and rebuilding them as cleaner constraint models in RCA. This is tedious but therapeutic. You’re simplifying while you’re translating.
Building the Configurator
The Advanced Configurator is built in two ways:
Visual Builder: Non-technical users drag and drop rules. “If product A is selected, show field B” or “Require product C when product A is in the bundle.” This works for 80% of configurations.
Constraint Modeling Language (CML): For complex logic, you write rules in code. It’s declarative, not procedural, so it reads more like business rules than programming. You can handle multi-dimensional constraints, numeric ranges, date-based logic, and dynamic pricing calculations.
Most implementations use a combination. Your business users build simple rules in the visual builder. Your architects handle complex scenarios in CML.
Permission Sets and Role-Based Access
RCA Permission Set Configuration
| Role | Permission Set | Capabilities | Key Access |
| Sales Rep | Rule Engine Runtime | Execute configured quotes, view pricing, submit for approval | Quote creation, pricing visibility, PDF generation |
| Sales Manager | Rule Engine Runtime + CPQ Admin (limited) | Manage team quotes, approve quotes, bulk operations | Quote approval, team pipeline, discount overrides |
| Product Admin | Product Catalog Designer | Create/edit products, attributes, classifications | Product management, catalog organization |
| Pricing Admin | Pricing Administrator | Create/manage pricing procedures, test pricing logic | Pricing strategy, procedure management |
| Configurator Builder | Advanced Configurator Designer | Build constraint models, visual rules, CML logic | Constraint modeling, visual builder access |
| Finance/Billing | Revenue Lifecycle Manager | Review orders, manage billing, revenue recognition | Order management, billing queues, invoicing |
| Contract Manager | Contract Lifecycle Admin | Draft/manage contracts, amendments, compliance | Contract generation, obligation tracking |
You need to assign permission sets carefully. Getting these wrong leads to mysterious “I can’t see the button” issues downstream.
Going Live: Phase It
Most enterprises don’t flip a switch from CPQ to RCA. They phase it:
Phase 1: Implement RCA for new products and new regions where you can start from a clean slate. Let legacy CPQ handle existing contracts for a while.
Phase 2: Migrate legacy contracts to RCA-based renewal processes. This happens naturally as contracts come up for renewal.
Phase 3: Decommission legacy CPQ (or keep it for archival, read-only access).
This phased approach reduces risk and gives your teams time to learn the new system.
Timeline and Resourcing
Simple implementations (single country, straightforward products, no complex legacy systems to integrate): 3-4 months.
Mid-size implementations (multiple countries, subscription + usage-based products, ERP integration): 5-6 months.
Enterprise implementations (multiple businesses, complex legacy migrations, global compliance requirements, extensive customization): 7-9 months or longer.
The biggest variable is data: cleaning up your product catalog and pricing rules takes time, but it’s not wasted effort. You’re building a foundation that will serve you for the next five years.
Winter ’26 and Beyond: What’s Coming
Salesforce released Winter ’26 (October 2025) with significant RCA enhancements that make fixing quote-to-cash pipelines even more efficient.
Latest Features (Winter ’26)
| Feature | What It Does | Business Impact |
| Improved Constraint Model Mgmt | Edit constraint models directly from product records (not separate tab) | Faster rule maintenance, more intuitive workflow |
| Advanced Configurator Upgrades | Import component groups, use object data for constraints (50K+ rows), auto-convert existing rules | Reduces manual rule rebuilding by 40-50% |
| Asset Transfer Between Accounts | Move subscriptions/assets to new accounts automatically | Customer M&A scenarios handled elegantly |
| Rollback Asset Actions | Undo amendments/cancellations if needed | Reduces need for manual credits/corrections |
| Auto Co-termination | Quotes from contracts auto-terminate at contract end | Prevents orphaned quotes, cleaner data |
| Price-Only Amendments with CPI Rules | Adjust pricing without touching terms (inflation adjustments) | Handles inflation-linked contracts automatically |
| Salesforce GO for RCA | Guided setup wizard, organized by feature area | Faster onboarding for new implementations |
| Deep Clone Quotes | Clone entire quote with all line items in one action | Cuts renewal quote generation from hours to minutes |
| Multi-Output Formulas in Pricing | More sophisticated pricing calcs without custom code | Complex pricing models possible in declarative UI |
Future releases (expected in 2026) will likely include deeper Agentforce integration—imagine an AI agent automatically generating quotes for customer requests, submitting them for approval, and even managing routine amendments without human intervention.
Key Takeaways: How RCA Fixes Broken Pipelines
Let’s be direct about what Revenue Cloud Advanced actually solves:
Summary Comparison Table
| Area | Legacy CPQ / Manual Process | Revenue Cloud Advanced | Advantage |
| Data Coherence | Multiple systems, conflicting versions of truth | One platform, single source of truth | Eliminates reconciliation work, 100% data accuracy |
| Speed | 14-21 days quote-to-signature | 2-3 days quote-to-signature | 85-90% faster deal closure |
| Accuracy | 8-12% quote errors, manual workarounds | <1% error rate, auto-validated | 90% fewer disputes, auto-correct |
| Scalability | Processing time increases with volume | Sub-second constraint checking, auto-scaling | 10x transaction volume, same resources |
| Visibility | Lag time (daily/weekly reports) | Real-time dashboards by role | Live decision-making, 10+ days better forecasting |
| Compliance | 40+ hours/month manual ASC 606 work | Automatic revenue recognition | Clean financials, 90% time savings |
| Integration | Custom API bridges, sync delays | Native API-first, real-time flow | Clean ERP integration, no data latency |
| Implementation | 12-18 months | 3-9 months | 40% faster, 30% lower cost |
- Data Coherence: One source of truth for products, pricing, quotes, orders, contracts, assets, and billing. When data flows through one system, downstream systems get accurate, consistent information.
- Speed: Guided selling, automated pricing, and streamlined approvals compress quote-to-signature cycles from weeks to days or hours.
- Accuracy: Constraint-based configuration and pricing procedures eliminate most quote errors before they reach the customer. Errors that do exist are caught and corrected early, not discovered during billing reconciliation.
- Scalability: Dynamic product attributes, subscription management, and consumption tracking let you handle 10x the transaction volume without proportional increases in manual effort.
- Visibility: Real-time dashboards across sales, finance, and operations mean every team operates from current data, not stale reports.
- Compliance: Automatic revenue recognition, contract obligation tracking, and audit trails mean finance teams stay compliant without spreadsheet gymnastics.
- Flexibility: An API-first architecture means Revenue Cloud Advanced integrates cleanly with your ERP, billing systems, and custom tools. It’s not a replacement for everything; it’s a hub that connects your systems and keeps them in sync.
The Real Truth About Broken Pipelines
Broken quote-to-cash processes aren’t usually the result of bad tools. They’re the result of tools that were architected for a different era. Legacy CPQ tools were built when most businesses sold simple products with straightforward pricing. Modern business is subscription-based, usage-driven, globally distributed, and heavily compliant.
Revenue Cloud Advanced is the architecture built for right now – and for the next five years. It’s not perfect for every use case (nothing is), but for enterprises with complex revenue operations, broken pipelines, and the pain of quota to cash misalignments, it’s honestly the first platform that actually addresses the problem at its root.
The companies implementing it aren’t doing it for feature richness. They’re doing it because their old systems don’t work anymore. And after implementation, they’re surprised by how much faster and cleaner their entire revenue operation becomes.
If your quote-to-cash process feels broken, that feeling is probably legitimate. And Revenue Cloud Advanced is built specifically to fix it.
At 2Creative Solutions, we help organizations fix broken quote-to-cash pipelines by designing Revenue Cloud Advanced the right way – scalable, flexible, and built for growth.
Explore how we do it: https://2creative.ca/
The conversation isn’t about whether to migrate from Salesforce CPQ to Revenue Cloud Advanced anymore – it’s about when, and more importantly, how your organization will manage the complexity of doing it right. If you’re a Salesforce architect tasked with this migration, you’re stepping into one of the most significant platform transitions in recent Salesforce history, and there’s a lot more nuance here than simply upgrading software.
Let me be direct: migrating from CPQ Classic to RCA migration requires you to rethink how your organization manages quotes, billing, revenue recognition, and every touchpoint in between. The underlying architecture is fundamentally different, the data model has been reimagined, and the assumptions you made when building your CPQ implementation no longer apply. But – and this is critical – RCA also gives you capabilities that make the effort worthwhile.
Why Now? The Strategic Shift Behind Revenue Cloud Advanced
Salesforce announced in March 2025 that CPQ Classic is no longer recommended for new implementations and will eventually reach end-of-support. This isn’t a casual deprecation. It’s a clear signal that Salesforce has moved on, and organizations still relying on CPQ need to be thinking seriously about their long-term strategy.
But the “why now” goes deeper than just deprecation dates. Three structural shifts in how companies do business have made RCA not just better, but necessary:
Subscription and recurring revenue models are the default. Whether you’re selling SaaS, telecommunications services, insurance policies, or managed services, the days of pure transaction-based sales are largely over. According to recent analysis, companies are losing up to 5% of potential revenue annually due to operational leakage in their quote-to-cash cycle when they’re trying to force subscription logic into a system designed for one-time deals. Revenue Cloud Advanced was built from the ground up for recurring revenue. It handles subscriptions, usage-based billing, amendments, renewals, and terminations as first-class citizens, not as bolt-on features.
Compliance and revenue recognition have become mission-critical. The accounting standards ASC 606 and IFRS 15 aren’t theoretical frameworks anymore – they’re board-level concerns. When your CFO is worrying about audit readiness and revenue timing, a system that requires manual reconciliation between your quoting tool, billing system, and ERP becomes a liability, not an asset. RCA brings revenue recognition logic directly into the platform, making your revenue operations audit-ready by default.
Organizations can’t afford to lose revenue due to disconnected systems. Manual handoffs between sales, finance, and operations aren’t just inefficient – they’re dangerous. Quotes that don’t flow cleanly into orders, orders that don’t feed billing accurately, billing that doesn’t match revenue recognition… these gaps add up. In financial services, insurance, and telecom specifically, we’re seeing migrations driven by regulatory pressure and the simple fact that CPQ plus external billing plus manual processes equals operational risk.
These three forces combined mean that for most organizations, CPQ to RCA migration has moved from “nice to have” to “must do.”
The Architecture: Understanding How Different These Systems Really Are
Before you dive into migration planning, you need to understand that RCA isn’t just a “better CPQ.” It’s built on a fundamentally different architecture, and that shapes everything about your migration strategy.
The Core Shift: From Managed Package to Native Platform
CPQ Classic is a managed package. It comes with its own custom objects (SBQQ__Quote__c, SBQQ__QuoteLine__c, SBQQ__ProductOption__c, and dozens more), its own APIs, and its own ecosystem of dependencies. When you implement CPQ, you’re layering a fairly comprehensive but ultimately separate system on top of Salesforce CRM.
Revenue Cloud Advanced, by contrast, is built on native Salesforce standard objects. It uses the standard Quote object, Quote Line Item, Order, Asset, and other native objects that are integrated directly into the Einstein 1 Platform. This matters because:
- Native objects get updates with every Salesforce release
- Native Flows replace custom Apex code for many use cases
- Native Lightning components work seamlessly
- API architecture is headless and more flexible
The implications for migration are significant. You’re not just moving data from one managed package’s database to another. You’re fundamentally changing how data is stored, accessed, and processed.

The Data Model: From Fragmented to Unified
Here’s where most architects encounter the first major surprise in migration planning:
In CPQ, your quote-to-cash flow looks something like this:
- Sales rep creates a Quote (SBQQ__Quote__c)
- Quote contains Quote Lines (SBQQ__QuoteLine__c)
- Contract is created from Quote
- Subscriptions are created from Contracts
- Assets are separate records
- Billing happens in a different system
- Revenue recognition happens in yet another system
Each of these pieces often requires data transformation, custom logic, and manual reconciliation. Your integration layer ends up thick and fragile.
In Revenue Cloud Advanced, the flow is unified:
Quote → Quote Line Item → Order → Order Product → Asset → Asset Action → Billing → Revenue Recognition
Everything flows through the same data model. When you modify a quote, that change cascades automatically. When you create an order from a quote, no re-entry of data. When billing happens, revenue recognition follows from the same source data. This unified approach eliminates entire categories of integration work and reconciliation risk.
The Asset Model: The Most Significant Change
If we had to point to one area where RCA is genuinely revolutionary compared to CPQ, it’s asset management.
In CPQ, you manage renewals and amendments through a contract-and-subscription model. Let’s say a customer buys a software license for $10,000/year on January 1st, 2026. You create:
- One Subscription record with quantity = 1, start date = 1/1/26, end date = 12/31/26
Six months later, the customer wants to upgrade. In CPQ, here’s what typically happens:
- You create an amendment quote
- You cancel the existing subscription
- You create a new subscription for the upgraded product at a new price
- You now have two subscription records in your history – the old one (terminated) and the new one (active)
In Revenue Cloud Advanced, it’s completely different. You have:
- One Asset record representing that product sold to that customer
- Multiple Asset Actions representing what happened to that asset over time
The customer’s upgrade is an Asset Action, not a cancellation and replacement. The amendment is tracked in the Asset Action history. Renewals, downgrades, amendments, terminations – each is an Asset Action with its own Asset State Period. When your finance team or sales ops team looks at what happened with that customer over the year, they see a complete timeline, not a mess of overlapping records.
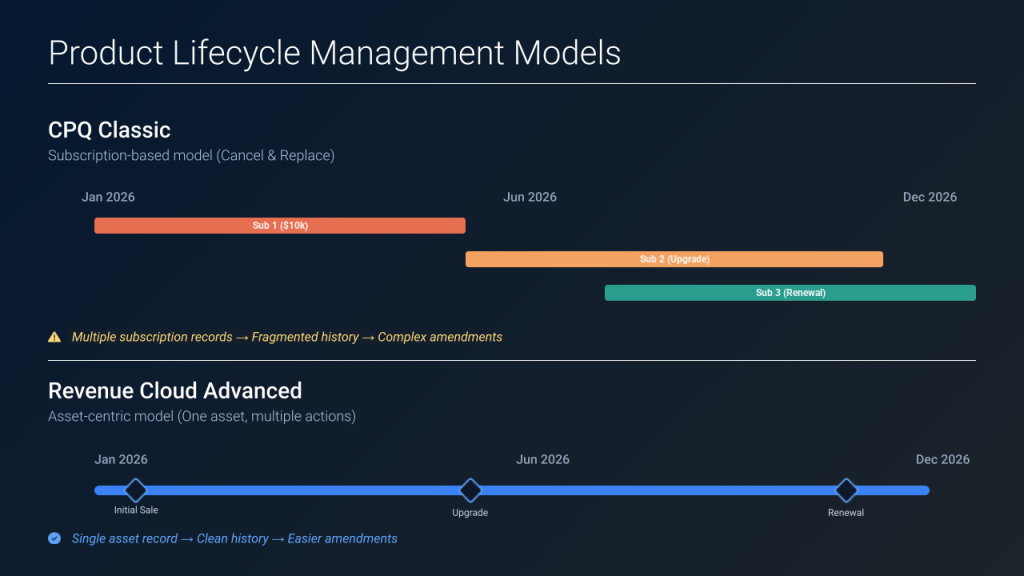
This changes how you think about:
- Renewals (no more cancel-and-replace complexity)
- Amendments (you can now extend a contract term without re-quoting)
- Revenue tracking (one asset, multiple revenue events)
- Customer history (a clean timeline of what was sold and changed)
For migration architects, this is critical to understand because it’s not just a data mapping exercise. It’s a conceptual shift in how you manage the product lifecycle for your customers.
Technical Architecture: Products, Pricing, and Attributes
Here’s another area where architects need to shift thinking. In CPQ, products are straightforward: you have a Product2 record, you attach it to Price Books, you create Price Rules for specific customers or conditions, and you manage Options and bundle rules through complex Product Rule configurations.
In Revenue Cloud Advanced, the approach to products is metadata-driven, and it’s more powerful but requires different thinking.
Products in RCA: Metadata-First
Instead of creating a separate Product2 record for every variation (like a “Software License – Enterprise – Annual” product), RCA uses Attributes. An Attribute is a metadata definition of a product characteristic that can be applied to many products at once.
Example: You sell cloud software with different editions. Instead of creating separate products for each edition, you:
- Define an Attribute called “Edition” with values: Starter, Professional, Enterprise
- Define another Attribute called “Billing Period” with values: Monthly, Annual
- Define another Attribute called “Users” as a number field
Now you create one Product record, and you can configure it with any combination of these attributes. The same Product can be quoted with Starter edition + Monthly OR Enterprise edition + Annual. RCA’s configurator handles this dynamically.
This dramatically simplifies your product catalog. A CPQ implementation with 500 products might become 50 products in RCA with attributes doing the differentiation. For organizations with massive catalogs, this is a game-changer. For your migration, it means you’ll need to rationalize your product hierarchy during the planning phase.
Pricing in RCA: Dynamic and Declarative
CPQ pricing is rules-based. You create Product Rules, Price Rules, and if those don’t work, you write Apex code. The system is powerful but requires a developer touch for anything non-standard.
RCA pricing is both more declarative and more capable. You define pricing through Pricing Procedures, which are visual configurations that don’t require coding. You can model:
- Base pricing (from price book)
- Discounts (percentage, fixed amount, tiered)
- Surcharges
- Currency conversions
- Usage-based pricing (tokens sold and consumed)
- CPI-based annual adjustments (new in Winter ’26)
And here’s the thing – these pricing procedures chain together. You can have the pricing flow through a series of steps, each modifying the price, and it all happens in a declarative model that admins can maintain without developers.
Winter ’26 introduced Formula Elements with multiple output formulas, which further reduces the need for custom calculations. Complex pricing that required Apex in CPQ can now be configured visually.
For architects, this is both an opportunity and a challenge. Opportunity because you can likely remove a lot of custom code. Challenge because you need to audit every custom pricing calculation in your CPQ implementation and figure out how to replicate it (or replace it) in RCA’s declarative model.
The Configurator: From Rules to Constraints
CPQ has a configurator, but it’s rules-based. You define Product Rules with logic like: “If the customer selects Feature A, they must also select Feature B” or “If they select Feature C, they can’t select Feature D.” These work, but they’re hard to maintain at scale, especially with large product hierarchies.
Revenue Cloud Advanced has an Advanced Configurator with a Constraint Model approach. Instead of writing rules one by one, you define constraints based on the data itself. You can use object data as the basis for constraints – supporting up to 50,000 rows of rules with object data, compared to the limitations of text-based rules in CPQ.
The constraint model is also more visual. Admins can work with constraint models directly alongside product definitions, making the relationship between product configuration and business rules clearer.
For migration, this means your existing CPQ Product Rules need to be evaluated and potentially rebuilt. Winter ’26 added a conversion tool that can help translate some rules into constraints, but complex custom logic may need to be completely rethought.
The Hard Part: Migration Challenges and Reality Checks
We want to be honest about what you’re up against, because we’ve seen too many architects underestimate these challenges.
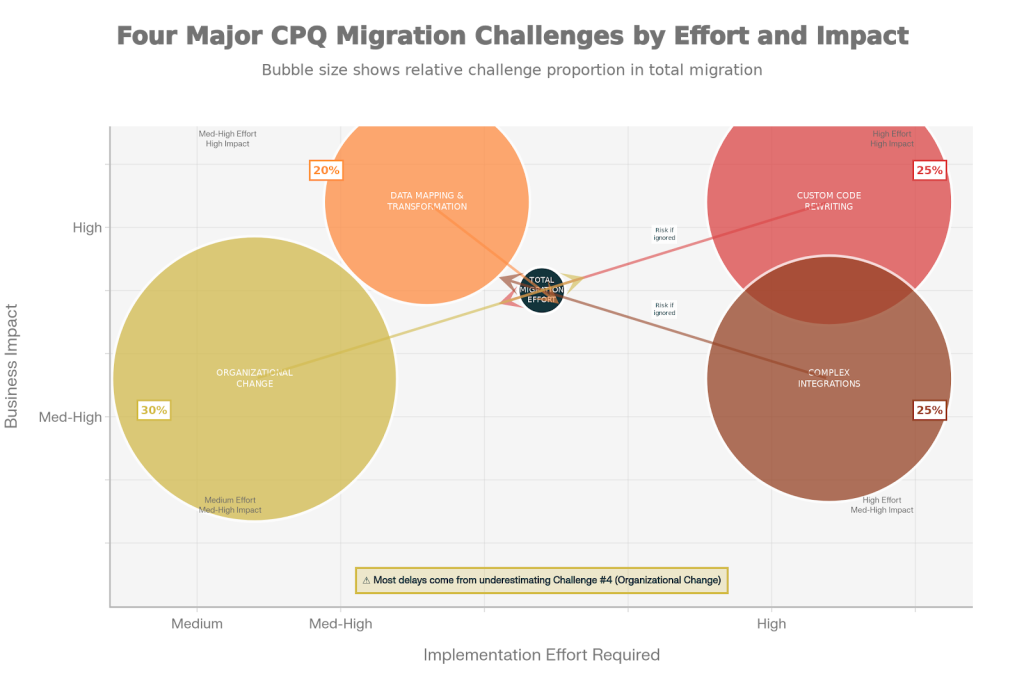
Challenge #1: Custom Code Rewriting
Most mature CPQ implementations have custom Apex code. Maybe you’ve written custom validation on quotes. Maybe you have an Apex trigger that calculates special discounts based on customer history. Maybe you built a Visualforce page to handle a specific quoting flow that CPQ’s standard UI doesn’t support.
Here’s the truth: most of this code won’t port cleanly to RCA. The object model is different (Quote instead of SBQQ__Quote__c, for example), the APIs have changed, and the underlying logic often needs to be fundamentally reconsidered because RCA does things differently than CPQ.
Our typical experience is that 20-30% of custom code can be migrated with updates, but 50-70% needs to be rewritten or replaced entirely. The good news is that much of what you built custom in CPQ can now be done declaratively in RCA using Flows, the Advanced Configurator, or Salesforce Pricing Procedures. But that requires architects and developers who understand both systems deeply.
This is often the biggest cost factor in migration that organizations underestimate. Budget time for a complete code audit and replacement planning.
Challenge #2: Data Mapping and Transformation
Your historical quote data needs to move to RCA, and it’s not a 1:1 mapping.
Let’s say you have 10,000 quotes from the past two years in CPQ that you want to preserve for reporting and history. Each quote has:
- Quote header (SBQQ__Quote__c) with fields like discount, customer payment terms, special notes
- Multiple quote lines (SBQQ__QuoteLine__c) with product configurations
- Price rules that were applied
- Approval history
When you move this to RCA:
- The quote header maps to the native Quote object, but some custom fields may not exist
- Quote lines map to Quote Line Item, but the field names are different
- Price rules don’t have a direct equivalent – you might keep them as records for reference, but the active pricing is gone
- Approval history needs to be preserved for audit purposes but may not be queryable in the same way
The data cleansing work is significant. You’ll need to:
- Identify which historical quotes actually matter for reporting (do you need 10 years of data?)
- Map custom fields and decide what happens if the target field doesn’t exist
- Validate currency values, dates, and calculations
- Create a tolerance for what doesn’t map perfectly (usually around 2-5% of data needs manual intervention)
Rule of thumb: budget 2-4 weeks for a thorough data cleansing and mapping exercise before you even start the technical migration.
Challenge #3: Complex Integrations Need Rebuilding
Your CPQ doesn’t exist in isolation. It probably integrates with:
- An ERP system (NetSuite, SAP, whatever) for order fulfillment
- A billing system (Zuora, Aria, custom solutions) for invoicing
- A contract lifecycle management (CLM) system for document generation
- Your accounting system for revenue recognition
- Maybe a revenue management system
All of these integrations are built to CPQ’s object model and APIs. When you move to RCA, those integrations often break because:
- The object structure is different (Quote vs. native Quote)
- The APIs are different (RCA has a headless API-first approach)
- Field names and values may have changed
- Data flow patterns are often different
You’ll need to audit every integration and rebuild the ones that are critical. For deep ERP integrations, this can take months. For simpler billing integrations, it might be 2-4 weeks of work.
Challenge #4: Organizational Change is Underestimated
Technical migration is one thing. Organizational migration is another. Your sales team has learned how to quote in CPQ. They know where fields are, how to add products, how to apply discounts. Revenue Cloud has a different UI, different flows, different naming conventions.
Similarly, your revenue operations team knows how to maintain CPQ – they know how to create price rules, manage product hierarchies, handle approvals. RCA pricing procedures, context definitions, and asset actions are conceptually different.
The training, change management, and user adoption effort is often the biggest delay factor. I’d estimate 4-6 weeks of dedicated effort for user training and support, with ongoing optimization work for 2-3 months post-go-live.
Migration Strategies: Which Approach Fits Your Reality?
There are essentially three ways to approach a CPQ to RCA migration. The right choice depends on your organization’s tolerance for risk, your technical capacity, and your business priorities.
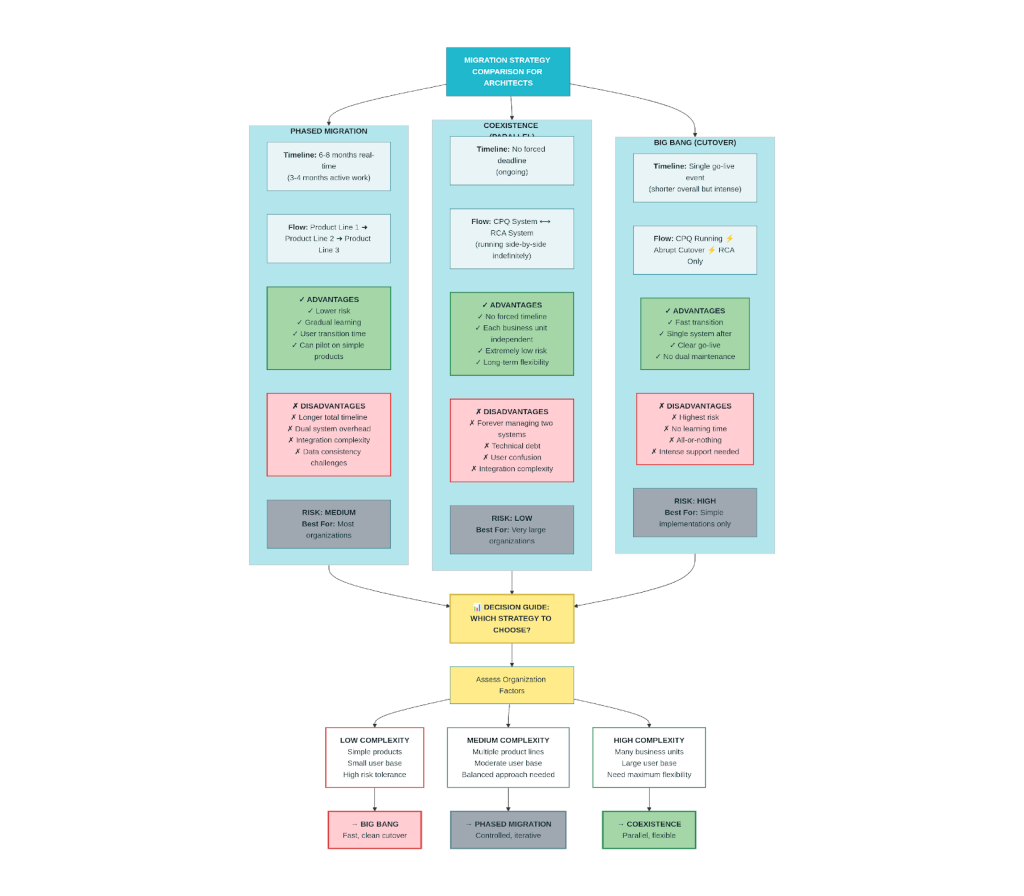
Strategy #1: Phased Migration (Most Common)
Run CPQ and RCA in parallel for a defined period (typically 3-6 months). You migrate one product family or business unit at a time to RCA while keeping CPQ live for the rest of the business.
Advantages:
- Lower risk (if something breaks in RCA, CPQ is still running)
- Time to learn RCA while still supporting the business
- Users can transition gradually
- You can pilot the migration on your lower-complexity products
Disadvantages:
- Higher operational overhead (maintaining two systems)
- Risk of data inconsistency between systems
- Longer total timeline
- Integration work needed for both systems
Best for: Most mid-market and enterprise organizations
Strategy #2: Coexistence (Underutilized Option)
This is interesting because most people don’t realize it’s possible: you can have CPQ and RCA running in the same Salesforce organization indefinitely, serving different parts of the business.
CPQ uses custom Quote objects (SBQQ__Quote__c). RCA uses the native Quote object. These don’t conflict. You could run CPQ for your legacy product lines and RCA for your new subscription business, and they’d operate independently.
Advantages:
- No forced migration timeline
- Different business units can adopt at their own pace
- Extremely low risk
Disadvantages:
- Forever managing two systems (technical debt)
- Integration complexity (two quoting engines)
- User confusion about which system to use
Best for: Very large organizations with distinctly different business lines, or as a long-term bridge strategy
Strategy #3: Big Bang (Highest Risk, Sometimes Necessary)
Cut over completely in a single go. Plan heavily, execute carefully, and move everything to RCA at once.
Advantages:
- Fast transition (no months of dual-system overhead)
- Single system to maintain afterward
- Clear, defined go-live
Disadvantages:
- If something breaks, it’s broken for everyone
- No room for learning or iteration
- Requires extremely thorough pre-go-live testing
- High stress on support team
Best for: Organizations with relatively simple CPQ implementations, or those with regulatory urgency
The Data Migration Process: Step by Step
If you’re going to migrate successfully, this is the process architects should enforce:
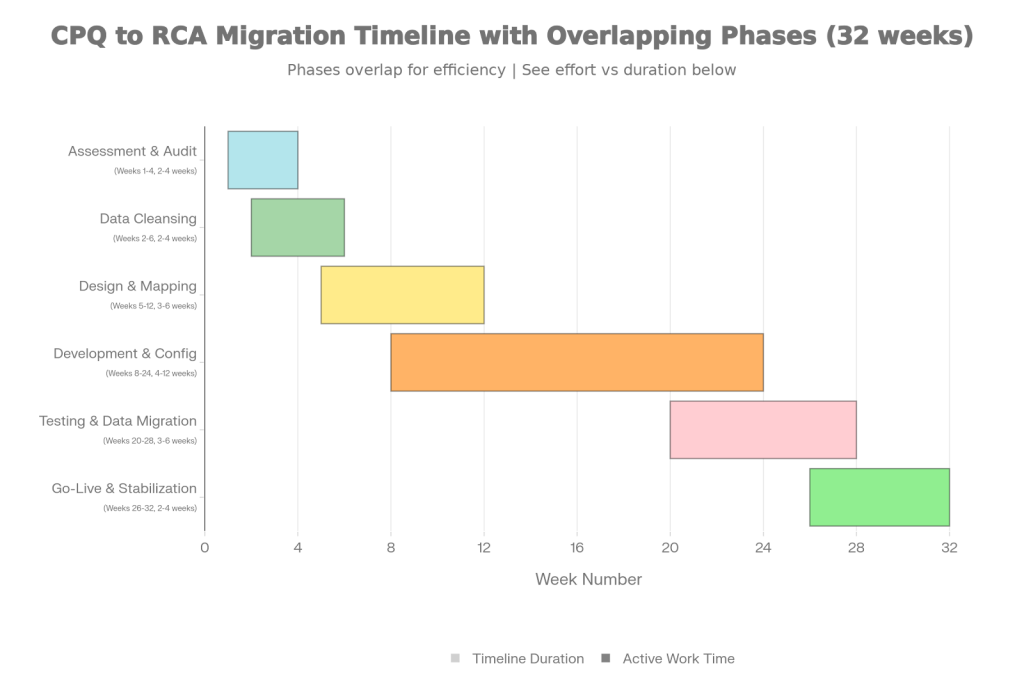
Phase 1: Assessment and Audit (2-4 weeks)
Before any data moves, you need to understand what you have:
- Document your current CPQ configuration (products, pricing rules, custom code, integrations)
- Audit your quote data – how much is actively used? How much is archive?
- Identify custom objects, custom fields, and custom logic
- Map dependencies (which systems feed into CPQ? Which consume CPQ data?)
- Build a data quality scorecard (identify bad data while you’re still in CPQ)
The output here is a detailed assessment document that becomes your blueprint for the migration.
Phase 2: Data Cleansing (2-4 weeks, can overlap with Phase 1)
Using your assessment, clean your data:
- Identify and remove duplicate product records
- Validate pricing data (do all prices make sense?)
- Clean up quote data (archive old quotes, fix corrupted records)
- Standardize naming conventions
- Ensure all users, accounts, and currency values are valid
This is unglamorous work, but it’s absolutely critical. You don’t want bad data following you to RCA.
Phase 3: Design and Mapping (3-6 weeks)
Now design your RCA configuration:
- Map CPQ Quote fields to native Quote fields (not 1:1 – think about what actually matters)
- Map Quote Line fields to Quote Line Item fields (you’ll use context definitions here)
- Design your product hierarchy and attributes
- Design your pricing procedures
- Design your asset management approach
- Document all custom code and decide: migrate, replace, or retire?
This phase produces a detailed design document and a field mapping spreadsheet that’ll guide your technical team.
Phase 4: Development and Configuration (4-12 weeks depending on complexity)
- Build your RCA product catalog
- Configure pricing procedures
- Rebuild or redesign custom functionality in Flows or declarative features
- Configure approvals
- Set up your asset management
- Create context definitions and field mappings
Parallel to this:
- Rebuild critical integrations
- Test APIs with external systems
- Configure billing workflows
- Set up revenue recognition
Phase 5: Testing and Data Migration (3-6 weeks)
- Create a sandbox with production data
- Perform data migration to sandbox
- Run user acceptance testing (UAT)
- Validate all integrations
- Test approval processes
- Verify billing and revenue recognition accuracy
This is where you find the problems you didn’t anticipate. Budget time for fixes and re-testing.
Phase 6: Go-Live and Stabilization (2-4 weeks)
- Perform final production data load
- Monitor closely during first day/week
- Be prepared with support resources
- Address issues that surface with real users
- Begin optimization work
The Quote-to-Cash Pipeline: How RCA Fixes It?
One of the most compelling reasons to migrate is the transformation of your quote-to-cash pipeline. This is where architects need to help their organizations understand the real value.
In CPQ, your pipeline is fragmented. A quote created in CPQ becomes a contract somewhere else, which spawns subscriptions, which don’t automatically feed billing, which requires manual reconciliation with revenue recognition systems. Multiple systems, multiple handoffs, multiple opportunities for data to diverge.
In RCA, the pipeline is unified. A quote flows directly to an order, to assets, to billing, to revenue recognition – all within the same data model. There’s no re-entry of data, no reconciliation work, no compliance gaps. The result is faster cycles (30-40% reduction in quote-to-close time), fewer errors (0.1% error rate vs CPQ’s 2-5%), and automatic compliance with ASC 606 and IFRS 15.
For your sales team, this means deals move faster. For your finance team, it means accurate revenue recognition with minimal audit risk. For your RevOps team, it means less reconciliation work and more time on strategy.
Winter ’26: Features Architects Should Understand
If you’re planning a migration now or soon, you need to know what RCA looks like in late 2025. Winter ’26 brought significant enhancements that should influence your architecture decisions:
- Quote Deep Clone: Users can now clone an entire quote – lines, groups, all of it – with one click. This is huge for sales teams handling similar deals. For architects, it means you need to think about what gets cloned (approvals? Historical pricing? custom fields?) and set expectations.
- Ramp Deals for Groups: Previously a pain point, you can now create multi-year deals with different products and pricing in each year-long segment. This was a major request from subscription and SaaS businesses. If your business models around multi-year contracts with different products per year, this is a game-changer.
- CSV Import for Quote Lines: You can now import quote line configurations from CSV. This is a pragmatic feature for organizations that have complex pricing in spreadsheets and aren’t ready to fully move that logic to RCA. It’s a bridge capability, not a long-term strategy, but it eases migration for complex pricing situations.
- Asset Amendment Enhancements: You can now extend asset terms without cancel-and-replace, apply price-only amendments, and handle CPI-based annual price adjustments automatically. This addresses what was probably the #1 complaint about CPQ’s renewal flow.
- Constraint Model Improvements: Direct editing from product records, conversion tools for existing rules, and support for larger rule sets (50,000 rows of object data). If you have complex product configurations, these improvements mean RCA’s configurator is finally at feature parity with CPQ.
- Approval Preview and Smart Submissions: Users can see what approval chain they’re submitting to before they submit, and they can resubmit without restarting the entire process. Operational friction gone.
- Salesforce Go for Revenue Cloud: This is huge for implementation efficiency. It’s an automated setup wizard that handles all the foundational RCA setup in one flow (vs. manually enabling Revenue Cloud, creating pricing procedures, extending contexts, etc.). For new implementations or migrations, this saves 30-60 minutes of manual setup per environment. If you’re building in a sandbox or new org, use it.
For architects evaluating RCA right now, Winter ’26 means the platform is genuinely mature. Features that were “nice to have” two releases ago are now standard capabilities.
What’s Coming in 2026: The Roadmap Signals
While Salesforce doesn’t confirm product roadmaps far in advance, based on recent releases and public statements, here are the areas to watch in 2026:
- Agentforce Revenue Management: This is the bigger story. Salesforce’s AI agents are coming deeper into Revenue Cloud. Imagine quote generation guided by AI, pricing recommendations based on historical win/loss data, and contract review with AI-suggested edits. This is coming. If your organization is building custom quoting workflows today, consider whether AI-assisted workflows make sense for your 2026 strategy.
- Usage-Based Billing Maturation: The platform added usage management in Spring ’25 and it’s been enhanced since. This will continue to evolve. If you’re billing on consumption (whether tokens, API calls, data usage, or actual product consumption), RCA’s approach will keep improving.
- Multi-Currency and Multi-Entity Enhancements: Global organizations have been asking for better support for complex currency and entity scenarios. Expect improvements here.
- Advanced Analytics and Predictive Insights: Revenue Cloud already integrates with Tableau, but expect deeper predictive capabilities around deal health, churn risk, and optimal pricing.
- For architects, the big-picture signal is clear: RCA is becoming the revenue operations backbone of Salesforce. It’s not a quoting tool anymore – it’s a complete revenue management platform that’s getting deeper AI integration, better analytics, and more automation. Plan your architecture with that trajectory in mind.
Best Practices for Architects: What We’ve Learned
After watching dozens of migrations, here are the practices that separate successful projects from painful ones:
1. Start with business process mapping, not data mapping.
Too many architects jump to “how do we move the data?” before understanding “what are we actually trying to accomplish?” Take time to map out your full quote-to-cash process in RCA terms. Often, you’ll realize you can simplify processes that were complex in CPQ. Don’t just lift-and-shift your CPQ workflows into RCA – redesign them.
2. Treat product hierarchy rationalization as a separate workstream.
In CPQ, you might have 500 products. In RCA with attributes, you might have 50 products with many attribute combinations. But this isn’t a technical conversion – it’s a business decision. Engage your product and revenue ops teams early. This work alone can save months of configuration and maintenance down the line.
3. Build governance before you build the system.
Who owns the product catalog? Who can create pricing procedures? Who approves changes? In CPQ, these governance structures often evolved ad-hoc. With RCA, establish clear data ownership and change control from day one. It pays off during migrations and afterward.
4. Plan for integration rewrites as separate projects.
Don’t treat integrations as an afterthought. If you have an ERP integration, that’s a real project with its own timeline and dependencies. Break it out, estimate it seriously, and schedule it as a dependent workstream of your migration.
5. Invest heavily in testing and validation.
The most commonly overlooked phase is testing. You’ll find issues you didn’t anticipate. Build in time for discovery, fixes, and re-testing. And validate not just functionality, but data accuracy, compliance (ASC 606 revenue recognition), and integrations with real data.
6. Use Salesforce Go for new sandbox environments.
If you’re building a new sandbox for your migration work, use Salesforce Go to set up the foundational RCA configuration. It’s fast, it’s correct, and it eliminates 30-60 minutes of manual setup busywork.
7. Plan for change management as seriously as technical implementation.
Your finance team’s month-end close process needs to change. Your sales ops team’s pricing maintenance approach needs to change. Your sales team’s quoting workflow changes. Give this real time and resources, or technical implementation will be perfect and adoption will be painful.
8. Consider running a pilot on one product line or business unit first.
If you’re large enough to segment, do it. Migrating your most complex product first is a mistake – start with something simpler, learn, then tackle complexity. A three-month pilot with one product line that sells 10-15% of your revenue is a reasonable investment in de-risking the full migration.
The Timeline Reality Check
We’ve mentioned timeframes throughout this, but let me be explicit about what typical organizations should expect:
Small organizations (under $10M revenue, simple pricing, <20 quote lines per month): 2-3 months of active work, spread over 4-5 months real-time due to testing and waiting for approvals.
Mid-market (under $100M revenue, moderate complexity): 3-4 months of active work, spread over 6-8 months real-time. This assumes you have dedicated people and the complexity is manageable.
Enterprise (large, complex, multiple product lines, global): 6+ months of active work, spread over 12+ months real-time. You’re likely doing a phased rollout, and each phase takes time.
The biggest variable is custom code. If you’re heavy on custom Apex, you’re adding 4-6 weeks minimum for code audit and rewrite. If you’re light on customization, you save that time.
Those are optimistic timelines assuming you have the right resources available and dependencies are managed. In reality, most projects run 20-30% longer due to discovery, scope changes, and integration challenges.
Conclusion: The Migration Is Real Work, But It’s Worth It
We want to be honest in closing: CPQ to RCA migration is a significant undertaking. It’s not a simple upgrade. You’ll deal with custom code rewrites, integration challenges, data transformation complexity, and organizational change. And it’ll take real time and resources.
But here’s why it’s worth doing, especially now:
The subscription economy, the complexity of modern pricing models, and the compliance demands of today’s business environment are pushing organizations toward integrated revenue operations. CPQ was designed for a different era – transaction-based sales with simple pricing and separate billing. RCA is designed for how companies actually operate now.
When you go through this migration thoughtfully – when you design your product hierarchy, rationalize your pricing, rebuild your integrations, and train your team – you come out the other side with a revenue operations platform that’s modern, scalable, and capable of supporting whatever your business evolves into next.
The work is substantial. But the payoff – faster deals, better pricing discipline, accurate revenue recognition, integrated systems, and reduced operational leakage – makes the effort real and valuable.
Start with assessment. Plan honestly. Execute rigorously. Your future self will thank you.
Ready to Plan Your CPQ to RCA Migration?
Migration from CPQ to Revenue Cloud Advanced is complex, but you don’t have to navigate it alone.
At 2Creative Solutions, we’ve guided enterprises through this transformation.
Whether you’re in the assessment phase or ready to execute, let’s talk about your migration strategy.
Get Expert Guidance
Book a 1-on-1 Consultation: https://2creative.ca/
Learn More & Stay Updated
Watch Our Video Tutorials: https://www.youtube.com/@2CreativeSolutions/
Connect on LinkedIn: https://ca.linkedin.com/company/2cretiv
The migration journey is real work, but the payoff is worth every effort.
We’re here to help you get there.
Picture this: It’s month-end, and your finance team is stuck in a spreadsheet labyrinth. A customer upgraded their seat count mid-cycle. Someone’s still billing them at the old rate. Three systems show different numbers. Your CFO is asking uncomfortable questions. Your CRO is frustrated. And nobody can quickly answer: “What are we actually earning this month?”
Welcome to the subscription business without proper revenue operations.
Now imagine a different scenario. A customer upgrades their tier on January 15th. The system automatically calculates the prorated amount for the remaining days at the old rate, generates a credit, and charges the new rate going forward. Tomorrow, when renewals kick in, 50+ customers get automatically renewed with zero manual effort. Finance closes the books with a single click – everything reconciles perfectly.
This isn’t magic. It’s Revenue Cloud Advanced (RCA) built specifically for how subscription businesses actually work.
The Subscription Billing Crisis That Nobody Talks About
Let’s talk about what’s really happening in most subscription companies right now.
You’ve probably experienced this: a customer calls and says they want to add five more seats starting tomorrow. Your sales rep manually quotes them, the deal gets approved, they send a contract, everything gets signed. Then what? Someone has to:
- Calculate what they owe for the partial month at the old rate
- Calculate the new recurring amount
- Update the invoice schedule
- Generate an amended quote
- Create a new contract
- Communicate the changes to finance
- Hope everything matches when the customer sees the invoice
And then that same company gets 50 similar requests next week, and suddenly half your team is stuck in manual amendment hell.
Or here’s another real scenario: A customer’s annual subscription renews on December 1st. Their account manager didn’t notice. They weren’t reminded. The renewal email went to spam. By the time anyone realized, the customer had already churned and left a one-star review. Revenue leakage. Customer loss. Completely preventable.
According to recent data, companies with poor subscription management lose 25-40% in potential revenue through billing errors, missed renewals, and payment failures. One study found that SaaS companies making manual subscription adjustments experienced 50% more billing disputes than those using automated systems.
This is what happens when you try to manage subscriptions with tools designed for one-time sales decades ago.
Why Traditional CPQ Breaks for Subscriptions
Before we talk about the solution, let’s understand why your current system is probably struggling.
Traditional Salesforce CPQ was brilliant when it launched. It solved the problem of complex one-time deals – you need to build a quote, apply discounts, get approvals, send it to the customer. Great.
But here’s where it fails for subscriptions: CPQ thinks in terms of transactions. Quote → Order → Done.
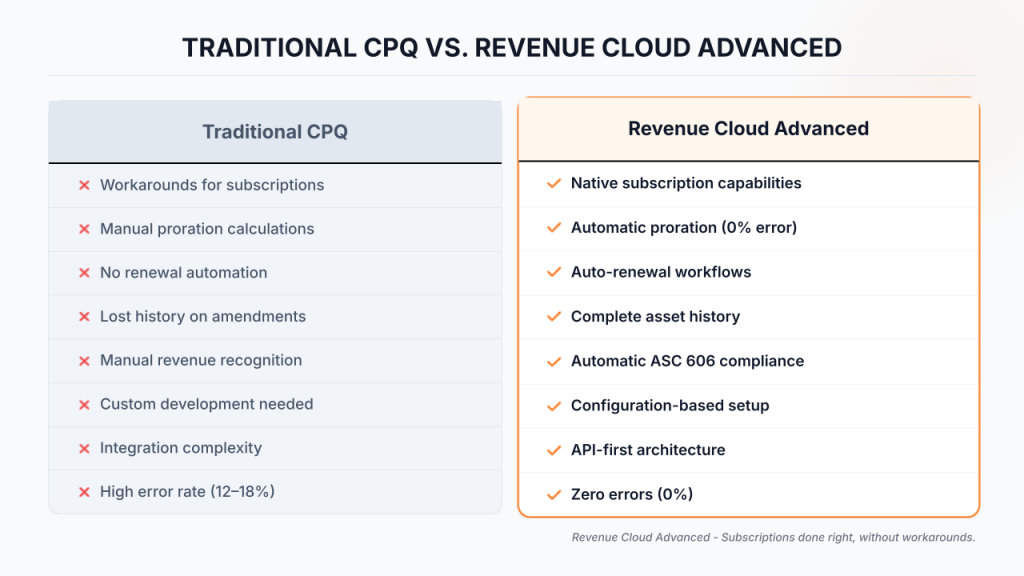
Subscriptions live in a different world. They have:
- Start dates and end dates (not just close dates)
- Renewal workflows (not just new opportunities)
- Mid-cycle amendments (not just new quotes)
- Asset history (not just deal history)
- Repeating billing (not just one invoice)
- Usage tracking (not just quantities)
- State changes (not just status updates)
CPQ forces you into workarounds. When a customer renews, you cancel their old subscription and create a new one – losing the history. When they amend, you create a new quote and cancel the old one – messy and error-prone. Usage tracking? You’re probably building that with custom code.
Revenue Cloud Advanced doesn’t work around subscriptions. It was built for them.
The Seven Pillars That Make RCA Different
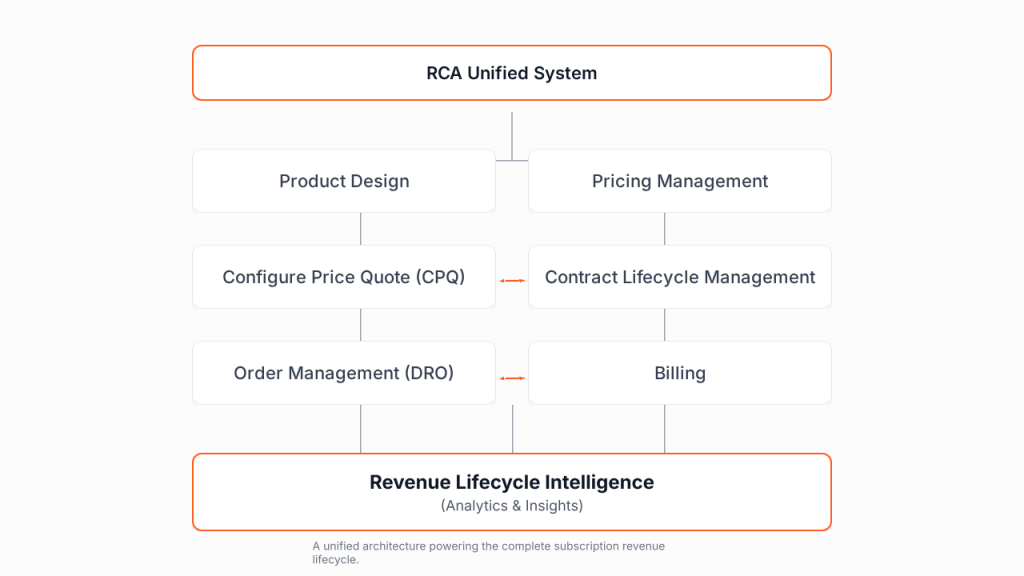
RCA is built on seven interconnected areas that create a unified revenue management system:
1. Product/Service Design – You define what you sell. For subscriptions, this means setting up your tiers (Basic, Pro, Enterprise), your billing frequencies (monthly, annual, quarterly), and your renewal rules. You’re not just listing products; you’re defining how they’re sold and renewed.
2. Pricing Management – This is where subscriptions get powerful. You create pricing not just as a number, but as a ruleset. “Annual subscriptions get 20% off monthly rates.” “Enterprise tier customers get volume discounts.” “Price increases by 5% on January 1st.” These aren’t static prices – they’re intelligent pricing rules that apply consistently.
3. Configure, Price, Quote (CPQ) – A sales rep logs in and builds a quote. They select a product tier, the billing frequency, and any add-ons. RCA automatically applies all your pricing rules, shows the monthly recurring revenue (MRR), annual recurring revenue (ARR), and total contract value. No manual math. No errors.
4. Contract Lifecycle Management (CLM) – The quote becomes a contract. RCA can auto-generate the contract (no more Conga/Nintex workarounds), route it for approvals, integrate e-signature, and archive it. For subscriptions, the contract captures the critical dates – start date, end date, renewal terms – all structured data RCA can act on.
5. Order Management – When the contract is signed, it becomes an order. RCA’s Dynamic Revenue Orchestrator takes that order and breaks it into actionable steps. For a SaaS subscription, this means: provision the account, create the support ticket, send the welcome email. For a physical subscription box, it means: schedule the first shipment. The system tracks every step and notifies teams when something completes.
6. Billing – This is where the automation magic happens. RCA automatically creates billing schedules. For a 12-month subscription, it creates 12 individual billing schedule records. On each scheduled date, it auto-generates an invoice. If the customer amended mid-cycle, the schedules reflect prorated charges. When they cancel, refunds calculate automatically.
7. Revenue Lifecycle Intelligence – Throughout this entire journey, RCA is building analytics. Dashboards show ARR at risk, renewal success rates, churn drivers, and revenue by cohort. Finance teams see real-time revenue recognition by accounting period.
Here’s what matters: These seven areas don’t exist in silos. They feed each other. A change in Billing automatically updates Revenue Intelligence. A new Order triggers Contract obligations. This integration is what makes subscription management smooth.
Real-World Use Case #1: E.ON One’s Chaos-to-Clarity Story
E.ON One is the software division of energy company E.ON. They sell complex energy management subscriptions that combine flat-rate monthly fees with usage-based charges. Think: base subscription for software access + charges for actual energy consumed.
Their problem: It was pure chaos.
Salespeople had to manually assemble complex quotes by mixing different product types. The product catalog was disorganized – no clear hierarchy, no selling models, no consistency. Renewals happened in spreadsheets (yes, really). Customer amendments meant manually rewriting contracts and hoping finance got the memo. Nobody could answer: “Which customers renew next month?”
Internally, the teams were disconnected:
- Sales didn’t know if a complex deal was even possible
- Finance couldn’t predict cash flow because renewals were unpredictable
- Customer success couldn’t manage renewals proactively
Their transformation:
E.ON One reorganized everything around a unified product catalog using RCA. They defined clear selling models – “subscription + usage,” “annual prepay,” “hybrid plans.” Sales reps could now build a complex quote in 15 minutes instead of 2 hours.
But the bigger wins came after the sale:
Renewals became automatic. When a subscription approached its end date, RCA generated a renewal quote automatically. If the customer wanted the same terms, they clicked approve. RCA created the renewal order, updated the asset end date, and created new billing schedules. Completely hands-off.
Amendments became painless. A customer called mid-cycle asking for more capacity. Instead of a 3-day process, it was: rep clicks “amend,” selects the new tier, RCA calculates proration, customer approves, new order created, billing updated. Done.
Finance gained visibility. They went from month-end reconciliation taking 5 days to happening in near-real-time. Every invoice was correct because the math was automated.
The results:
- Sales productivity up 35% (less quoting time, more selling)
- Month-end close time cut from 5 days to 1 day
- Billing error rate dropped from 7% to <0.5%
- Customer renewal rate improved 12% (because renewals were proactive, not missed)
Real-World Use Case #2: Cool Cats Technologies – Seat-Based Subscriptions Done Right
Now consider a SaaS company using seat-based pricing (you pay per licensed user). It seems simple until customers start scaling and changing their seat counts.
Cool Cats Technologies faced this problem: A customer starts with 10 seats at $50/user/month = $500/month. Three months later, they hire 15 new people and want 25 seats. What happens?
Without RCA: Someone manually calculates: They used 10 seats for 3 months ($1,500) plus they owe 15 additional seats for the partial month. Figure out the daily rate, calculate proration, generate a new invoice, hope nothing breaks.
With RCA: Customer requests amendment on day 15. RCA automatically:
- Calculates: 10 seats × 15 days at old rate = $250 (prorated amount used)
- Calculates: 25 seats × 15 days at new rate = $625 (prorated amount for remainder)
- Issues: Credit for unused days of old rate + charge for new prorated amount
- Updates: Billing schedule now shows 25 seats × $50 = $1,250/month going forward
- Logs: This entire transaction in the asset record with perfect audit trail
Most importantly – RCA tracks this in the asset record. Finance doesn’t have to reverse-engineer what happened to this customer’s subscription. The system knows:
- 10 licenses from Jan 1 – Jan 15
- 25 licenses from Jan 15 – Dec 31
When it’s time to recognize revenue, RCA has already calculated that January earned $X based on 10 seats for 15 days and 25 seats for 16 days. No spreadsheet gymnastics. No guessing.
And when Cool Cats’ sales team handles 500+ seat amendments per month? Same process, same accuracy, zero manual work.
Real-World Use Case #3: Cloud Infrastructure with Usage-Based Billing – The Complex Model
The most challenging subscription model combines a base subscription with usage-based overage charges. A cloud infrastructure company sells:
- Base plan: $500/month for 1,000 API calls + 500GB storage
- Overage: $0.10 per additional API call, $5 per additional GB storage
A customer using 1,500 API calls and 600GB storage should be billed:
- Base subscription: $500
- API overage: 500 calls × $0.10 = $50
- Storage overage: 100GB × $5 = $500
- Total: $1,050
The challenge: Tracking consumption across thousands of customers, applying tiered rates, handling refunds for prepaid credits, managing expiring credits – this is where traditional billing systems completely fall apart.
How RCA handles it:
RCA has native consumption management built into the platform. Here’s the actual workflow:
- Consumption tracking – Usage data flows in (via API integration or manual entry). The system logs every API call, every GB stored, for every customer, timestamped.
- Automated aggregation – At billing time, RCA’s consumption process runs and aggregates: This customer made 1,523 API calls this month, used 612GB storage.
- Intelligent rate application – The system applies your rate card: First 1,000 calls free with subscription, next 523 calls × $0.10 = $52.30. For storage: First 500GB free, next 112GB × $5 = $560.
- Wallet management – If this customer has $200 in prepaid credits, RCA applies those credits to the invoice automatically. Remaining credit balance updates in real-time.
- Overages and overage alerts – If they consistently exceed their base allowance, alerts notify your account team to suggest the next tier up.
- Expiration enforcement – If credits expire on March 31st and they haven’t been used, RCA automatically prevents use after that date.
The result? Accurate usage billing with zero manual calculation. Customers see detailed breakdowns on their invoices explaining exactly why they were charged what they were charged.
Asset-Based Management: The Core Architecture
Here’s where RCA fundamentally differs from any other system – everything is asset-based.
When you create an order for a subscription in RCA, the system automatically creates an asset record. This asset isn’t static. It tracks the complete lifecycle of what happened to this subscription.
Let’s say a customer has this journey:
- Month 1-3: 10 licenses, $100/month
- Month 4-8: 25 licenses, $100/month (upgraded)
- Month 9: Canceled
In legacy systems, you’d have:
- Subscription #1 (now deleted)
- Subscription #2 (now deleted)
- Cancellation record
- Nobody knows the full journey without digging through history
In RCA, you have one asset record with three asset state periods:
- State period 1: 10 units, Month 1-3, $100/month
- State period 2: 25 units, Month 4-8, $100/month
- State period 3: Canceled, Month 9

Your entire team can see this asset’s journey in one place. Finance knows exactly when the subscription changed. Sales knows the upgrade happened in Month 4. Customer success knows when they canceled.
This asset-based model is what makes renewals, amendments, and cancellations work seamlessly. Each change creates a new state period. The history is preserved. The audit trail is perfect.
The Amendment Workflow: Where RCA Shines
Let’s walk through an actual amendment to show you how this works.
Day 15 of the subscription: Customer calls and says, “We need to upgrade to the next tier, effective immediately.”
Before RCA:
- Sales rep creates a new quote for the new tier
- Quote gets approved (if needed)
- Customer signs new contract
- Finance manually calculates what to charge for the remainder of the month
- Finance manually updates the billing schedule
- Original subscription sometimes gets canceled, sometimes left orphaned
- Nobody’s completely sure the math is right
With RCA:
- Sales rep clicks “Amend Asset”
- Selects the new tier from the configurator
- RCA calculates proration automatically
- Shows the charge: “Customer will be charged $X for remaining days”
- Amendment goes through approval (if configured)
- Once approved: New order created, billing schedules updated, asset state period logged
- Done
The system automatically:
- Calculates prorated credit for unused portion of old tier
- Calculates prorated charge for new tier (effective immediately)
- Updates all billing schedules for future periods
- Logs the entire transaction
- Updates revenue recognition schedules
- Sends notifications to all relevant teams
This is repeatable. One customer, one hundred customers, one thousand customers – same process, same accuracy, zero manual work.
Renewals: From Chaos to Automation
Renewal chaos is real. Studies show that poorly managed renewals account for 30-40% of net revenue leakage in SaaS companies.
Here’s the typical problem:
- Renewal dates are scattered across months
- Renewal reminders go unsent or to wrong addresses
- Contract terms get lost
- Manual renewal quotes are error-prone
- Customers get surprised by renewal notifications
RCA’s renewal workflow:
60 days before a subscription ends, you can configure RCA to automatically create a renewal opportunity. This opportunity can include:
- Same terms as the original subscription
- Auto-calculated pricing (including any price increase you’ve configured)
- Full contract history (so nothing gets lost)
- Customer communication already scheduled
The customer gets a renewal notification early. Your account team sees it in their queue. If the customer wants the same terms, they approve and it’s done. If they want to negotiate different terms, sales opens an “override renewal” which goes through the same amendment workflow.
When the renewal is approved, RCA:
- Creates a renewal order
- Updates the asset end date
- Creates new billing schedules
- Updates revenue schedules
No renewal gets missed. No terms get lost. And customers aren’t surprised.
Proration: The Math Problem Solved
Proration is beautiful in theory, terrifying in practice.
The formula is simple: (Days Used / Days in Period) × Monthly Cost
But executing it correctly across thousands of customers with:
- Different amendment dates
- Different billing periods
- Different currencies
- Different discount structures
- Different add-on combinations
…that’s where systems fail.
RCA handles proration natively. When you amend a subscription effective mid-cycle, the system knows:
- Current rate and end date
- New rate and new effective date
- Exact number of days used at each rate
- Whether this is monthly, quarterly, or annual billing
It calculates:
- Credit owed for unused days at old rate: (Days Remaining / Days in Period) × Old Monthly Rate
- Charge for new period at new rate: (Days Remaining / Days in Period) × New Monthly Rate
- Net adjustment: Charge – Credit
And it does this with 100% accuracy, 100% of the time, with perfect audit trails showing exactly how the calculation was made.
Usage-Based and Tiered Pricing: Complex Models Made Simple
Not every subscription is flat-rate. Some charge based on consumption. Some use tiered pricing where the rate changes based on volume.
Progressive tiers work like: 1-50 units at $1 each, 51-100 units at $0.90 each, 100+ units at $0.80 each. (Not volume-based – progressive means you apply the rate to only the units in that tier.)
Block tiers work like: 1-10 units, everything is $1 each. 11+ units, everything is $0.90 each. (Volume-based – the rate applies to all units.)
Tiered pricing in RCA:
You configure these pricing structures once. RCA’s pricing procedure engine applies the correct tier to each customer based on their consumption. If Customer A uses 75 units and Customer B uses 150 units, they’re automatically charged different rates. No manual calculation. No errors.
For usage-based models, RCA has wallet management built in. If a customer prepays $5,000 in credits:
- Each billing cycle, RCA draws down from the wallet
- Remaining balance shows in real-time
- When credits run low, alerts notify the account team
- When credits expire, RCA automatically prevents use after that date
- No disputes about “I thought I had prepaid credits”
The Seven Pillars in Action: A Complete Workflow
COMPLETE SUBSCRIPTION JOURNEY IN RCA
1. QUOTING (CPQ Pillar)
Sales rep builds quote → RCA applies all rules → Shows MRR/ARR
↓
2. CONTRACT (CLM Pillar)
Auto-generated → Approved → E-signed → Key dates captured
↓
3. ACTIVATION (Order Management)
Order created → Dynamic Revenue Orchestrator → Provision, email, support
↓
4. RECURRING BILLING (Billing Pillar)
Auto-invoke schedules → Generate invoices → Track payments
↓
5. AMENDMENTS (Order Mgmt + Billing)
Customer requests change → Auto-proration → New billing schedules
↓
6. RENEWAL (Revenue Intelligence)
60-day reminder → Auto-renewal quote → Customer approval → New term
↓
7. CHURN/CANCELLATION
Customer exits → Asset closed → Final revenue recorded → Analysis
ALL STAGES CONNECTED • ZERO MANUAL WORK • PERFECT AUDIT TRAIL
Let’s trace one subscription through all seven pillars to see how this actually works:
Product Design: You’ve defined a “SaaS Pro” product with:
- Monthly and annual billing options
- Add-on options (premium support, advanced features)
- Pricing rules (20% discount for annual)
Pricing Management: You’ve set the base price at $99/month. Annual = $99 × 12 × 0.8 = $950 annually.
Quote: Sales rep builds a quote. Customer selects SaaS Pro, annual billing, adds premium support. RCA shows: Base $950 + Support $200 = $1,150 total contract value, $95.83/month MRR.
Contract: The quote becomes a contract. Customer e-signs within Salesforce. Contract captures: Start date 01/01/2025, end date 12/31/2025, renewal auto-enabled.
Order: Signed contract becomes an order. RCA’s Dynamic Revenue Orchestrator triggers: Provision account, create welcome email, generate billing schedule.
Billing: System creates 12 billing schedule records (one per month). On 01/01/2025, it generates the first invoice for $95.83 (prorated for the month). On 02/01/2025, next invoice for $95.83. On 12/01/2025, final invoice. (Annual billing would show one invoice upfront.)
Revenue Intelligence: Dashboard shows: This customer has $1,150 ARR. They’re in Month 1 of their 12-month term. Renewal is 11 months away. Revenue is recognized monthly at $95.83.
Day 45: Customer requests to upgrade to “Pro+” tier at $149/month.
RCA handles the amendment:
- Calculates days remaining in first month: 15 days
- At old tier ($99/month = $3.30/day): 15 days × $3.30 = $49.50 credit
- At new tier ($149/month = $4.97/day): 15 days × $4.97 = $74.55 charge
- Net: Customer charged $25.05
- New billing schedule: $149/month for remaining 11 months
- Revenue intelligence updates: ARR now $1,638 (based on new tier + remaining months)
All seven pillars working together. All automated. All accurate.
Updates That Matter
RCA has been evolving rapidly. Here are the updates most relevant for subscription companies:
Advanced Configurator (General Availability) – You can now build complex product hierarchies without custom code. Nested options (choose a tier → choose add-ons → choose support level) flow naturally.
Product Attributes Expansion – You can now define up to 200 attributes per product (previously 15). If your product needs rich customization, you have the space for it.
Smart Auto-Renewals – Sales reps can now override renewal terms during the initial sale. If you know a customer will want different terms at renewal, you can configure that upfront.
Wallet Management Improvements – Prepaid credit balances now display directly on account records with real-time drawdown visibility.
Large Quote Support – Quotes with 1,000+ line items no longer cause performance issues. If you’re selling complex bundles, this matters.
CPI-Based Price Adjustments – You can now automatically adjust prices based on inflation indices, monthly/quarterly/annually. One of CPQ’s biggest pain points solved.
When RCA Becomes Essential
RCA isn’t the right choice for every business. If you’re selling simple $50/month subscriptions with no amendments and basic invoicing, simpler systems might suffice.
But if you answer YES to any of these, RCA moves from “nice-to-have” to “essential”:
- ✓ Do customers ever change their subscriptions mid-cycle?
- ✓ Do you offer multiple pricing tiers or usage-based billing?
- ✓ Do renewals require any kind of management?
- ✓ Do you struggle with renewal churn?
- ✓ Does your finance team spend significant time on revenue reconciliation?
- ✓ Do you operate in regulated industries requiring audit trails?
- ✓ Do you manage subscriptions across multiple entities or currencies?
- ✓ Do you offer hybrid pricing (subscription + usage)?
These are the scenarios where RCA’s unified approach pays massive dividends.
Implementation Reality: The Honest Conversation
Let’s be real: implementing RCA is significant. You’re not just adding a new tool; you’re rethinking how your organization manages revenue.
What needs to happen:
- Product rationalization – Your product catalog gets cleaned up. Consolidate variants, document pricing logic, eliminate redundant SKUs. This alone takes 4-8 weeks.
- Process redesign – Your sales process changes (in good ways). Quote-to-close gets faster. Your billing process changes (in great ways). Manual invoicing mostly disappears.
- Data migration – Historical subscription data needs to be mapped into the new asset model. This is tedious but necessary.
- Team training – Sales reps need to learn guided selling. Finance teams need to understand new workflows. Support teams need to see how to look up subscription history.
Typical timeline:
- Mid-market company (50-100 reps): 4-6 months
- Enterprise company (200+ reps, complex pricing): 6-12 months
- Part of that is waiting for your team to learn, not just implementation work
Real ROI that companies report:
- 40-50% reduction in month-end close time
- 30-40% improvement in sales rep productivity
- 60-80% reduction in billing errors
- 2-3 months improvement in time-to-cash
For a company with $10M ARR, this ROI typically justifies the implementation cost within 12-18 months.
From Manual Chaos to Automated Excellence
Here’s what we know after talking to dozens of subscription companies: They all start in the same place. Spreadsheets. Manual processes. Multiple systems that don’t talk to each other.
They all have the same problems: Renewals get missed. Billing has errors. Finance can’t close on time. Customers get frustrated with wrong charges.
But the ones that fix it – they move to systems purpose-built for subscriptions.
RCA for subscription businesses isn’t trying to be everything to everyone. It’s built on a simple premise: subscriptions are different from transactions. They have lifecycles. They change mid-term. They renew. They need tracking. And all of this should be automated.
When a customer upgrades mid-cycle, the system should know. When a subscription renews, it should happen automatically. When a payment fails, it should retry intelligently. When finance closes the books, everything should reconcile instantly.
That’s not magic. That’s just RCA working the way subscription operations should work.
If you’re currently managing subscriptions with tools designed for one-time sales, the gap between where you are and where you could be is probably larger than you realize.
Ready to Transform Your Subscription Operations?
Managing subscriptions with tools built for one-time sales is leaving money on the table.
Here’s where to start:
– Audit your current state – Where are the manual touchpoints and billing errors?
– Define your success metrics – Faster renewals? Zero billing disputes? Better visibility?
– Understand the seven pillars – See how RCA handles your entire subscription lifecycle
– Test one use case – Start with your biggest pain point
Connect with 2Creative’s Revenue Cloud specialists to discuss your subscription challenges and how RCA could transform your operations.
Visit 2Creative Solutions for more Salesforce tutorials and resources on our platform.
The Problem That Starts Small and Explodes
Here’s something that sounds way too familiar: Your sales team can’t get quotes out on time. Your pricing is inconsistent depending on who’s quoting. And when you finally dig into why, you realize your pricing system has pieces everywhere – definitions over here, procedures over there, decision tables nobody really understands – and they’re not talking to each other properly.
This is the mess most companies end up with. They implement Salesforce Revenue Cloud or Industries CPQ, configure these three components separately (because that’s how the documentation breaks them down), then wonder why pricing feels fragmented and error-prone.
Here’s the real talk: These three components only work when they’re built to work together from day one. Get it wrong, and you’re back to manual quote reviews, pricing errors, and your team spending half their day fixing calculations instead of closing deals.
The Painful Reality Most Teams Don’t See Until It’s Too Late
Let us walk you through what actually happens when these components aren’t aligned:
Sales rep adds a product to a quote. The system freezes for 10 seconds. Why? Because your Context Definition isn’t mapped to the right data source, so the pricing procedure is running queries against the wrong Salesforce objects. Data’s taking forever to load.
Or worse: The quote generates a price. It looks reasonable. Deal closes. Then your billing team sees it and calls sales because the price doesn’t match your customer contracts. Your pricing procedure and decision tables weren’t pulling from the same source of truth.
Or your pricing logic is buried in decision tables with hundreds of entries. Nobody maintains them. Rules become outdated. Competitors’ pricing changes, and your team doesn’t know how to respond because updating decision tables requires IT involvement.
This is what happens when Context Definitions, Pricing Procedures, and Decision Tables are treated as separate config exercises instead of one interconnected system.
Context Definitions: The Often-Misunderstood Foundation Everyone Skips Over
Most technical teams treat Context Definitions as a boring prerequisite. “Just map the fields and move on,” they say.
Wrong approach. This is where everything starts. If your Context Definition is wrong, your entire pricing strategy fails silently.
Here’s what’s actually happening under the hood: When a sales rep creates a quote, Salesforce needs to know three things:
- Where to pull data from (which objects, which fields)
- How to label that data so the pricing logic knows what it’s working with
- Where to write the final calculated prices back to
Context Definitions handle all three. They’re essentially a bridge between your Salesforce data model and your pricing engine.
The Structure
You define nodes (which are basically your Salesforce objects – Quote, Product, Account, etc.) and attributes (specific fields like Product ID, Quantity, List Price, Customer Region). Then comes the critical part: context tags.
Context tags are labels you assign to each attribute. When your pricing procedure runs and needs to apply a regional discount, it doesn’t search for “Account.Industry” – it searches for the attribute tagged as “CUSTOMER_INDUSTRY.” This tag-based connection is what makes everything plug together cleanly.
The mapping process ties this all together. You tell the system: “The attribute I tagged ‘CUSTOMER_INDUSTRY’ in my context definition corresponds to the Industry field on the Account object in my Salesforce org.” Done. Now when pricing runs, the system knows exactly where to fetch data and where to store results.
The Common Mistake
Here’s the thing most teams get wrong: They map to the wrong object. A telco team might create a Context Definition for Product Catalog (standard setup), but they actually need to map to their Communication Bundle object because that’s where the actual product configurations live. Then pricing never pulls the right product attributes, and their discount logic breaks.
What Actually Breaks?
- Your pricing procedure can’t find the data it needs, so it defaults to null values, resulting in broken prices
- Your team has to manually enter prices into quotes
- Reporting breaks because the data relationships are damaged
- You end up maintaining pricing rules in two places – context definitions and somewhere else – because the first mapping didn’t work
Pricing Procedures: The Execution Engine Where Your Business Logic Lives
Once your Context Definition is dialed in, Pricing Procedures are where your actual pricing policy happens. They’re the workflow that transforms raw data into a final customer price.
Think of a Pricing Procedure as a choreographed sequence of pricing steps. Each step performs a calculation, looks up a value, or applies a rule. The output from one step feeds into the next. The final output is what your customer sees on their quote.
Real-World Example: Telecom Bundle Pricing
Let me show you a real example. Here’s a typical pricing waterfall for a telecom company bundling internet, phone, and managed services:
Step 1: Base Price Lookup → Procedure queries a decision table to fetch the list price for Internet service from the product catalog. Returns $99.
Step 2: Quantity Adjustment → For every line item added (3 managed services), the base price increases by $15/unit. Calculation: $99 + (3 × $15) = $144.
Step 3: Volume Discount → The customer’s purchase history shows they’re buying for 50 locations. The procedure queries the volume discount decision table: “If order quantity > 25 AND product category = Telecom AND customer segment = Enterprise, apply 12% discount.” Applied: $144 × 0.88 = $126.72.
Step 4: Contract-Specific Pricing → The customer has a master agreement with a 10% service discount. Another decision table lookup: “If contract type = Master Service Agreement AND customer = [this customer], apply additional discount.” Applied: $126.72 × 0.90 = $114.05.
Step 5: Regional Adjustment → The customer is in EMEA. A final decision table returns the regional surcharge: +8% for compliance and infrastructure costs. Calculation: $114.05 × 1.08 = $123.17.
Step 6: Tax & Final Price → Tax calculation adds 17% (Germany VAT). Final: $123.17 × 1.17 = $144.11.
Your customer’s quote shows $144.11/month for bundled services, and your sales rep can see exactly how that price was built. Audit trail? Clean. Transparency? Perfect. Sales rep’s confidence that this price is correct? Very high.
Why This Design Matters?
This is what a well-designed Pricing Procedure looks like. Every step is documented. Rules are applied in order. Nothing’s hidden.
Common Mistakes
- Hardcoding values: They build the procedure with hardcoded values instead of decision table queries. When pricing changes, someone has to request a code change. It takes days. Meanwhile, your market’s moving.
- No step testing: They string together 20+ pricing steps without testing each one. When pricing breaks, it’s unclear which step is failing. Debugging becomes a nightmare.
- Copy-paste logic: They build different pricing procedures for different sales channels but copy-paste logic everywhere. When a rule needs to change, they have to update 5 places and forget one, causing inconsistent pricing.
The procedure should be your single source of truth for how you price anything. Every sales channel, every geography, every customer type – all driven by the same core pricing procedure, with decision tables controlling the variations.
Decision Tables: The Business Rules Engine That Actually Scales Your Pricing
This is where your pricing decisions live. Decision Tables aren’t just lookup tables. They’re a business rules engine that handles complex multi-condition logic.
The Fundamental Difference
A basic lookup table says: “If quantity > 100, discount = 10%.”
A decision table says: “If (Quantity > 100 AND Product Category = Hardware AND Customer Segment = Reseller AND Region = North America AND Customer Payment Status = Current), then Discount = 15%, but only if Contract Type = Volume License.”
Multiple conditions. Multiple possible matches. Layered business logic. That’s what decision tables enable.
How They’re Structured
In a Salesforce Revenue Cloud or Industries CPQ setup, decision tables are usually structured like this:
Inputs: The conditions you’re evaluating (Quantity, Product Category, Customer Segment, Region, Contract Type, etc.)
Outputs: The values you’re returning (Discount %, Surcharge, Price Override, Approval Threshold, etc.)
Rows: Each row represents a specific business rule. Multiple rows can match simultaneously, and the decision table returns all matching rules so your pricing procedure can stack them (apply multiple discounts, for example) or pick the best one.
Real-World Example: SaaS Enterprise Pricing
Here’s a real-world example from a SaaS company selling to enterprises:
| Product Tier | Contract Length | Upfront Commitment | Discount % | Output |
| Enterprise | 3-year | $100k+ | 25% | Apply 25% discount |
| Enterprise | 2-year | $50k-$100k | 18% | Apply 18% discount |
| Enterprise | 1-year | $25k-$50k | 12% | Apply 12% discount |
| Pro | Annual | $10k-$25k | 8% | Apply 8% discount |
| Startup | Annual | <$10k | 0% | No discount |
When a customer comes through with Tier=Enterprise, Length=2-year, Commitment=$75k, the decision table matches the second row and returns 18% discount instantly.
The Operational Reality: Maintenance & Governance
But here’s the operational part most teams overlook: Decision tables need to be refreshed.
If your price book changes on Friday, but your decision table still has Tuesday’s prices, you’re quoting stale prices. The sales team doesn’t know why customers are complaining. Finance doesn’t know why the margin is lower than expected. And by the time someone figures it out, you’ve already quoted 50 deals with wrong pricing.
Salesforce provides a Sync Pricing Data function specifically to refresh decision tables with current information from your Salesforce objects. But this only works if someone owns it and runs it regularly. Or you set up automation to trigger it when price books update.
What Breaks with Decision Tables
- Nobody maintains them, so rules become obsolete. A competitor drops pricing; your decision tables still quote the old prices.
- They’re so enormous (500+ rules) that finding why a specific price was calculated requires hours of detective work.
- They’re fragmented across multiple decision tables that don’t reference each other, so the same business rule exists in three places, and when policy changes, one gets updated and the others don’t.
Decision tables are only powerful if they’re maintained as a single source of truth for pricing rules.
How These Actually Work Together: The Complete Flow
Here’s what happens from start to finish when all three components work in harmony:
Sales rep creates a quote and adds a telecom bundle product with 5 add-ons. They click “Calculate Price.”
Step 1: Context Definition Loads Data
The system uses your context definition to pull all relevant data. It knows where to get:
- Product ID (from Quote Line Item)
- Quantity (from Quote Line Item)
- Customer Segment (from Account)
- Region (from Account)
- Contract Type (from Contract)https://2creative.ca/revenue-cloud-advanced/
- Any other attributes tagged in your context definition
Step 2: Pricing Procedure Starts Executing
The procedure runs its first element: “Look up List Price.” The procedure queries a decision table (called “Product List Prices”) with inputs like Product ID and Price Book. The decision table returns $99.00 for this product.
Step 3: Volume Discount Element
The procedure checks the Quantity attribute (5 units). It queries another decision table (“Volume Discounts”) with Quantity=5, Product Category=Telecom, Customer Segment=Enterprise. Decision table returns: Apply 10% discount. Calculation: $99 × 0.90 = $89.10.
Step 4: Regional Adjustment Element
The procedure pulls the Region attribute (EMEA). Queries decision table (“Regional Pricing”) with Region=EMEA. Returns: +8% surcharge for compliance costs. Calculation: $89.10 × 1.08 = $96.23.
Step 5: Customer-Specific Pricing Element
Queries decision table (“Contract Pricing”) with Customer ID and Contract Type. Returns: This customer has a Master Agreement with +5% service bundle discount. Calculation: $96.23 × 0.95 = $91.42.
Step 6: Tax Calculation Element
Queries decision table (“Tax Rates”) with Region=EMEA. Returns: 19% VAT. Calculation: $91.42 × 1.19 = $108.79.
Step 7: Write Results Back
The procedure writes $108.79 back to the Quote Line Item’s Unit Price field (thanks to context definition mapping). It also writes a “Price Breakdown” field so your rep sees:
Base $99 → Volume Discount -$9.90 → Regional +$7.13 → Contract -$4.81 → Tax +$17.38 = $108.79
This entire sequence happens in 2–3 seconds. Your sales rep sees an accurate, policy-compliant, audit-ready price without doing any math. That’s the power of these three components working together.
Visual: The Data Flow Architecture
To visualize how these three components interact, imagine the pricing calculation as a data pipeline:

Key insight: The Context Definition feeds data → Pricing Procedure orchestrates the sequence → Decision Tables provide the business rules → Results write back to Quote. It’s a closed loop. If any link breaks, the entire system fails.
Governance: The Critical Element That Prevents Pricing Chaos
Here’s what nobody talks about until it becomes a disaster: pricing governance.
You can build the most beautiful Context Definitions, Pricing Procedures, and Decision Tables in the world. But if you don’t govern them, you’ll end up with:
- Sales reps using outdated pricing rules because decision tables weren’t refreshed
- Finance unable to explain why margins are inconsistent across quotes
- Regulatory audits failing because nobody can trace how a specific price was calculated
- Pricing changes applied inconsistently because multiple people are updating rules without coordination
What Governance Actually Means in Revenue Cloud?
Governance in pricing isn’t about bureaucracy. It’s about control, consistency, and accountability.
Here are the key governance elements you must implement:
1. Clear Ownership & Roles (RACI Model)
Define who owns what:
- Pricing Data Owner: Accountable for business rules in decision tables (usually Finance/Pricing)
- Context Definition Owner: Responsible for data mapping and maintenance (usually IT/Technical)
- Pricing Procedure Owner: Accountable for pricing logic and testing (usually CPQ Admin)
- Decision Table Steward: Responsible for regular refresh and accuracy (usually Finance)
Without clear ownership, nobody maintains anything.
2. Change Control Process
Every pricing change must follow a formal process:
- Proposal: Pricing team proposes a rule change (e.g., “Update volume discount threshold from 25 to 20 units”)
- Review: Finance + Sales + Compliance review for impact
- Testing: CPQ Admin tests the change in a sandbox decision table
- Approval: Decision table owner approves
- Deployment: Change goes to production with version control
- Communication: Sales team is notified before the change goes live
Without this process: Someone changes a decision table at 2 PM on Friday, sales quotes wrong prices over the weekend, and you don’t discover it until Monday morning when customers complain.
3. Version Control for Decision Tables
Decision tables must be versioned, especially in regulated industries:
- Track who changed what, when, and why
- Maintain a historical record of all versions
- Never delete old rules – mark them as “deprecated” with a sunset date
- Use date-based naming for seasonal or temporary rules (e.g., “Promotion_Q2_2026”)
Real scenario: Tax rates change January 1. You update your Tax Rate decision table. But sales is still using a cached version from December. They quote with old tax rates. Your CFO discovers the error weeks later during margin analysis. If you have version control, you can see exactly when the rule changed and audit all affected quotes.
4. Audit Trails & Traceability
Your pricing system must answer: “Why was this customer quoted $X.XX?”
This requires:
- Quote-level audit trail: Every price calculation should show the decision table rows that matched
- Decision table change log: Track all modifications to rules with timestamps and user IDs
- Data refresh log: Document when decision tables were last synced with source data
- Approval records: Show who approved the pricing change and when
Compliance reality: If you operate in regulated industries (Insurance, Healthcare, Financial Services), auditors will ask for this documentation. If you can’t produce it, you fail the audit.
5. Regular Refresh & Sync Strategy
Decision tables become stale. You must establish:
- Daily automated sync for frequently changing data (price books, tax rates)
- Weekly manual audits of decision table accuracy
- Monthly governance reviews where the Pricing Data Owner validates all active rules
- Clear ownership of the sync process – if nobody owns it, it doesn’t happen
Process that works:
- Set up Salesforce Flow to auto-refresh decision tables when price book updates
- Configure alerts if a refresh fails
- Assign a “Pricing Data Steward” to validate table accuracy weekly
- Document the refresh schedule publicly so sales knows when rules are current
6. Segregation of Duties
Don’t let one person control everything. Implement:
- Different users for creating, testing, and deploying decision tables
- Approval gates so changes don’t go live without review
- Restricted access to production decision tables (read-only for most, write for stewards only)
- Audit tracking to identify who made unauthorized changes
Why this matters: Preventing fraud and errors. One sales manager shouldn’t be able to modify discount rules without oversight.
7. Pricing Exception Handling
Not every quote fits the rules. You need a process for exceptions:
- Exception approval workflow: If a quote falls outside the pricing rules (custom discount, special customer situation), it requires approval from Pricing Manager + Finance
- Exception documentation: Log every exception with business justification
- Monthly exception review: Analyze exceptions to identify if rules need updating
- Escalation matrix: Define who approves exceptions at different discount thresholds
Real-world: $100k deal with a customer who wants 40% discount (your rules allow max 25%). Sales submits an exception request. Pricing Manager reviews and approves at 32% after verifying customer lifetime value. Finance gets visibility. No surprises.
8. Regulatory Compliance & Audit Readiness
In certain industries, pricing governance is non-negotiable:
- Insurance companies: Must show rating compliance with state regulations
- Healthcare orgs: Must demonstrate pricing transparency and anti-kickback compliance
- Telecom/Communications: Must prove pricing consistency and non-discrimination
- Financial services: Must have audit-ready documentation for pricing decisions
What you need: A governance documentation pack that includes:
- Pricing policy (written, approved by leadership)
- Decision table definitions (what each rule does)
- Change history (what changed, when, why)
- Audit trail (every quote and its pricing calculation)
- Exception log (every deviation from standard pricing)
If an auditor asks for documentation on why Customer X was quoted Price Y, you can produce it in minutes, not weeks.
Industry-Specific Examples: Why This Matters in the Real World
Telecom/Communications Companies
Context Definitions map to Communication Bundles and Service Components (not just standard Products).
Pricing Procedures handle complex bundling logic (when you add one service, what else gets included?).
Decision Tables store pricing rules for thousands of combinations – different pricing for wireline vs. wireless, enterprise vs. consumer, new vs. retention, promotional windows, regional regulations.
Governance requirement: Document which decision tables apply to which markets to ensure compliance with regional pricing rules.
Without this architecture working together, your sales team is manually building bundles in spreadsheets. That’s where the errors come from.
Insurance Companies
Context Definitions include Underwriting Attributes (risk factors, claim history, coverage level).
Pricing Procedures apply rating rules – base rate gets modified by underwriting factors in sequence (age, location, driving record, etc.).
Decision Tables store the rating matrix: “If age 25-35 AND location=Urban AND claim_history=None, apply base rate × 0.95.”
Governance requirement: State regulators require documentation of all rating rules and proof that rates are applied consistently. Decision table version control and audit trails are mandatory for compliance.
Rebuild this manually or get it wrong, and you’re either overpricing (losing deals) or underpricing (losing margin). Worse, you fail regulatory audits.
Energy/Utilities
Context Definitions include Usage Patterns and Contract Terms.
Pricing Procedures handle consumption-based pricing (the more you use, the tiered rate changes).
Decision Tables store consumption tiers, seasonal adjustments, and regulatory surcharges by region.
Governance requirement: When regulations change (carbon tax, renewable surcharges), you update decision tables with effective dates and track the change for audit purposes. No code changes needed, but all changes are logged.
Setting This Up Right: The Sequence That Actually Works
If you’re building this from scratch, here’s the correct order:
Phase 1: Context Definitions
Identify which Salesforce objects hold your pricing inputs and where final prices need to be written. Don’t build from scratch – extend Salesforce’s standard context definitions. Map your attributes to Salesforce fields. Most importantly: assign context tags to every attribute so your pricing procedure knows how to reference them.
Test the mapping with real data before moving forward. Nothing worse than discovering mid-implementation that your mapping pulls from the wrong field.
Phase 2: Decision Tables
Build your lookup tables once your context definitions are locked. These hold your business rules and pricing data. Populate them with current price book entries, discount schedules, tax rates, and any custom rules your business uses.
Don’t populate decision tables with incomplete data hoping you’ll fill it in later. Incomplete tables lead to incomplete pricing. Test with edge cases: what happens if a lookup finds no match? Intentionally create test scenarios that fail.
Establish governance: Document who owns each decision table. Define the refresh schedule. Create a change log template.
Phase 3: Pricing Procedures
Now build your procedures. Start simple – just base pricing and one discount type. Get that working and tested. Then incrementally add complexity: additional discounts, taxes, surcharges, approval workflows. Build once and test thoroughly before adding the next step.
The Simulate function is your best friend here. Run test quotes through your procedure before it goes live. Test scenarios like:
- A product with no matching decision table entry (does it handle null gracefully?)
- Overlapping discount rules (does your procedure stack them or pick the highest?)
- Edge cases like zero quantity or negative amounts
- Different customer types and regions
Fix issues before sales is quoting.
Phase 4: Sync Pricing Data & Governance Activation
Once you have procedures running, sync your decision tables with current Salesforce data. Then schedule regular syncs or trigger them automatically when prices, discounts, or tax rates change.
Document who owns this refresh. If nobody owns it, it won’t happen, and you’ll be quoting stale prices.
Activate governance controls:
- Create an approval workflow for decision table changes
- Set up automated refresh schedules
- Document the RACI model (who owns what)
- Create an exception approval process
- Set up audit logging to track all changes
Common Disasters and How to Avoid Them
Disaster 1: Building All Three, Then Realizing They Don’t Fit Together
Most companies configure these components following documentation (which breaks them down separately) instead of designing them as an integrated system from the start.
Result: Context Definition pulls one set of data. Pricing Procedure expects different data. Decision Tables are built for yet a different data model. Nothing works together. Full rework required.
Avoid it: Bring your entire team (pricing, sales, IT) into the design phase. Map out the complete data flow before configuring anything. Make sure pricing procedures match what context definitions can actually provide. Create a data flow diagram before you write a single config.
Disaster 2: Decision Tables Nobody Maintains
You build them beautiful on day one. Then Q2 hits, pricing changes, and nobody updates decision tables. By Q4, you’re quoting prices from six months ago.
Result: Margin issues. Customer complaints. “Why did we quote $50k for this service? It should be $35k.”
Avoid it: Assign someone to own decision table maintenance. Or build automation that syncs decision tables when source data changes. Make it a scheduled, accountable process, not a “whenever someone remembers” task. Use your Pricing Data Steward role to own this.
Disaster 3: Pricing Procedure Has No Audit Trail
You can’t see why a specific price was calculated the way it was. Sales can’t explain discounts. Finance can’t verify. Auditors ask questions nobody can answer.
Avoid it: Build your pricing procedure so each step is clearly visible. The price waterfall should show: Base → Discount → Tax → Final. Sales team and finance should be able to trace exactly how pricing was calculated from quote to invoice.
Salesforce provides quote line item fields specifically for this – use them. Capture the decision table results, not just the final number.
Disaster 4: Hardcoding Pricing Rules Into Procedures Instead of Decision Tables
Someone configures a pricing procedure with hardcoded values: “If quantity > 100, discount = 10%.” When that rule changes, they request a change to the procedure code. Takes weeks.
Result: Agility dies. You can’t respond to market changes quickly.
Avoid it: Move all business rules into decision tables. Procedures should reference tables, never hardcode rules. This way, the pricing team can update rules without IT involvement. Changes happen in hours, not weeks.
Disaster 5: No Governance = Chaos
Different people update decision tables at different times. Pricing rule changes without notification. Conflicting rules in different tables. Audits fail because you can’t prove why prices were calculated.
Avoid it: Implement the governance framework described above. It’s not bureaucracy – it’s protection. Formal change control, version history, audit trails, and clear ownership prevent disasters before they happen.
Why Getting This Right Transforms Your Business?
Here’s what happens when these three components are working together properly:
- Your sales team quotes accurately on the first try. No manual calculations. No price reviews. Deals move faster.
- Your pricing is consistent across channels, geographies, and customer types. No surprises for finance. No margin leakage.
- Your pricing team can test new strategies, update rules, and deploy changes without requesting IT support. They own their pricing strategy.
- Your audit trail is perfect. You can show exactly why every customer was quoted the price they saw.
- Your business can respond to market changes in hours. Competitor drops pricing? Update decision tables. New regulation? Sync tax rules. Promotional window? Set up temporary rules and test before launch.
- Compliance audits pass on the first try because you have complete documentation and traceability.
And here’s the real payoff: your sales team spends time selling, not calculating. Your finance team spends time analyzing trends, not explaining why margins are off. Your pricing team can actually be strategic instead of reactive.
This is only possible when Context Definitions, Pricing Procedures, and Decision Tables are built as one integrated system from the start, backed by governance that ensures consistency and compliance.
The Bottom Line
Your pricing strategy is only as strong as the connection between its components.
Context Definitions, Pricing Procedures, and Decision Tables aren’t three separate pieces – they’re one integrated engine. Get any one wrong, and the whole thing breaks.
Add governance, and you transform pricing from a chaotic, error-prone manual process into a scalable, auditable, strategic asset.
Here’s the formula:
- Map your data properly (Context Definitions)
- Build your business rules cleanly (Decision Tables)
- Chain them together in a transparent, auditable procedure (Pricing Procedures)
- Govern the whole system (Ownership, Change Control, Audit Trails, Regular Maintenance)
Do this right, and your team quotes faster, your margins are healthier, your business can pivot pricing strategy in real time, and you pass compliance audits without scrambling.
That’s how modern revenue operations should work. And that’s exactly what we help clients build at 2Creative.
Key Takeaways for 2Creative’s Audience
For Salesforce Administrators & CPQ Specialists:
- Context Definitions are more than data mapping – they’re the foundation of your entire pricing engine
- Decision tables must be version-controlled and refreshed regularly, or pricing calculations become unreliable
- Pricing governance isn’t optional – it’s what separates companies that quote right from those that create margin disasters
For Finance & Pricing Teams:
- These three components working together give you the visibility and control you need to enforce pricing policy
- Governance ensures that pricing changes happen consistently and can be audited for compliance
- Decision table ownership should sit with Pricing (not IT) so business teams can respond to market changes quickly
For Implementation Partners & Consultants:
- Always design these three components as an integrated system, not separately
- The governance framework is often overlooked but is what makes implementations sustainable long-term
- Clients who implement proper change control and audit trails avoid expensive rework later
Appendix: Governance Checklist
Use this checklist to audit your pricing governance:
Ownership & Roles
- Pricing Data Owner assigned
- Context Definition Owner assigned
- Pricing Procedure Owner assigned
- Decision Table Steward assigned
- RACI matrix documented and communicated
Change Control
- Change request process documented
- Approval gates in place (Review, Test, Approve, Deploy)
- Testing happens in sandbox before production
- Sales notification process established
- Change logs maintained
Decision Table Management
- Version history tracked
- Change timestamps recorded
- User IDs logged for accountability
- Deprecated rules marked (not deleted)
- Refresh schedule documented and followed
- Automated sync triggers configured where applicable
Audit & Compliance
- Quote-level audit trail captures decision table matches
- Exceptions logged with business justification
- Exception approval workflow active
- Monthly exception reviews conducted
- Documentation ready for auditor requests
Testing & Validation
- Edge cases tested (null returns, overlapping rules, zero values)
- Different customer types/segments tested
- Regional variations tested
- Test cases documented
- Results documented before production deployment
Communication & Training
- Sales team trained on current pricing rules
- Finance team trained on audit trail review
- IT team trained on governance process
- Pricing changes communicated before go-live
- New team members onboarded on governance process
Learn More About Revenue Cloud Pricing
2Creative Solutions specializes in Salesforce Revenue Cloud and Industries CPQ implementations. If you’re struggling with pricing fragmentation, decision table maintenance, or governance, we can help you build the right system from the start.
Resources:
- Learn Salesforce: YouTube Channel
- Our Website: 2creative.ca
Landing a Salesforce Architect role requires mastering behavioral questions, technical depth, and architectural thinking. This guide provides complete, production-ready answers for 20+ interview questions that candidates can confidently deliver. Every answer is specific, actionable, and based on real scenarios.
Salesforce Architect Role Overview
A Salesforce Architect designs enterprise solutions by conducting discovery, recommending best practices, creating technical designs, and communicating strategic decisions to stakeholders. Unlike developers who build features, architects make decisions that serve organizations for years. The role demands technical expertise, business acumen, and leadership skills.
Architect Types:
- Solution Architect: Designs within Salesforce – data models, security, custom code, clouds
- Technical Architect: Handles integrations, APIs, external system connections
- Data Architect: Specializes in data structure, normalization, large volumes
- Application Architect: Masters native features before recommending custom development
- System Architect: Focuses on off-platform integrations and governance
Behavioral Questions (STAR Method)
1. What is your approach to designing a Salesforce solution?
Walk through methodology: discovery sessions to understand pain points, evaluate standard functionality versus custom development, design data model first (everything depends on it), create security and automation architecture, document in solution design documents, validate with stakeholders and technical teams.
Real example: Architected telecommunications multi-org solution with hub-and-spoke pattern. Master org held product catalog; 15 regional orgs subscribed via Platform Events. Result: 40% reduction in duplicate config effort, product launch time decreased 3 weeks to 5 business days.
2. Describe a complex project and how you approached it architecturally.
Situation: Global company with 15 separate Salesforce orgs, duplicate product definitions, inconsistent pricing, no coordinated partner relationships.
Task: Centralize shared data while allowing local customization without disrupting operations.
Action: Designed hub-and-spoke architecture with master org for products/pricing/partners. Regional orgs subscribe to updates via Platform Events. Used Integration Procedures with error handling. Implemented Batch Apex nightly validation for consistency across orgs. Phased rollout – pilot two regions, then wave rollout.
Result: 40% config reduction, time to market decreased from 3 weeks to 5 days, saved $500K annually in configuration effort.
3. How do you manage stakeholder expectations?
Communicate transparently from day one. Involve stakeholders in architectural decisions showing trade-offs. Set realistic timelines based on complexity. Provide weekly updates, bi-weekly demos. Communicate roadblocks immediately, not surprises later. Establish change control for scope changes showing impact on features and timeline.
4. How do you stay current with Salesforce?
Multiple channels: Trailhead for structured learning, quarterly release notes (Winter/Spring/Summer), community user groups, Dreamforce attendance, hands-on sandbox experimentation with new features. Block 3 hours weekly for learning new capabilities.
5. Describe influencing a team to adopt a new approach.
Situation: Team relied on Process Builder; facing maintenance issues and governor limit violations.
Action: Built business case showing metrics (15 hours/month troubleshooting, 8 Process Builders hitting limits). Created side-by-side demo showing Flow simplicity. Proposed gradual approach – new automation uses Flow, migrate existing gradually. Provided training, templates, pair programming with junior developers.
Result: Migrated 23/47 Process Builders in 4 months. The team became Flow advocates. Maintenance time dropped 35%.
Technical Deep-Dives
1. How do you ensure scalability and performance?
Data layer: Normalize by default. Design queries to be selective (filter on indexed fields: Id, Name, CreatedDate, SystemModstamp, RecordType, relationships). For 5M+ record objects, request custom indexes on frequently queried fields. Use skinny tables for custom database access.
Code layer: Bulkify everything – never SOQL/DML in loops. Use collections for lookups. For long operations, implement Batch Apex (up to 200 records/batch), Queueable (chaining), or Future methods. Use Platform Cache for frequently accessed data.
Integration: Batch API calls. Use Bulk API for large volumes. Implement intelligent queueing.
Monitoring: Event Monitoring identifies slow queries. Salesforce Optimizer finds issues. Load testing before production.
Real metric: 50M Account records, queries timed out. Added CreatedDate filter (indexed field), query returned ~5M records. Report loaded in 2 seconds instead of timing out.
2. What OAuth 2.0 flows are available and when to use each?
Web Server (Authorization Code + Secret): Trusted server authenticates to Salesforce. Enterprise web apps.
User-Agent (Implicit Grant): Mobile SDK apps. Less secure; use PKCE instead.
PKCE (Authorization Code + PKCE): Modern choice for mobile/SPA without secure backend. Best for custom apps.
JWT Bearer Token: Server-to-server without user interaction. Upload X.509 certificate, create signed JWT. Perfect for ETL, middleware, CLI tools.
SAML Bearer Assertion: Leverage existing SSO infrastructure. Enterprise Okta/Azure AD integration.
Username-Password: Legacy, not recommended.
Decision: JWT for server-to-server, PKCE for mobile/SPA, Web Server for web apps with secure backend.
3. How do you handle Large Data Volumes (LDV)?
Query selectivity: Filter on indexed fields (CreatedDate, OwnerId, Status). Avoid formula fields, NULLS, wildcards. Queries must return <10% total records.
Custom indexes: Request for frequently filtered fields.
Skinny tables: Custom database tables with subset of fields for faster access.
Batch processing: Batch Apex for 50K+ records, chunking by 200 records.
Data archiving: Move inactive records to Big Objects; keeps active database lean.
Real example: 30M Account records, reports timed out. Implemented selective queries on indexed fields, requested skinny tables for reporting fields, archived inactive accounts to Big Objects. Report load time: 2 seconds (was timing out).
4. How do you design the Salesforce sharing model and security?
Layer 1 – Org-Wide Defaults: Start restrictive (Private or Public Read Only), open via rules only.
Layer 2 – Role Hierarchy: Managers see subordinates’ records automatically. Represents vertical org structure.
Layer 3 – Sharing Rules: Owner-based (share records by owner group) or criteria-based (share by field values).
Layer 4 – Manual Sharing: Ad-hoc collaboration on specific records.
Layer 5 – Programmatic Sharing: Complex logic using Apex when declarative insufficient.
Layer 6 – Field-Level Security: Profiles and permission sets control field visibility.
Test thoroughly with different personas – sales rep sees own opportunities, manager sees team’s, executive sees all.
Real example: Financial services company restricted client data. OWD: Private. Role hierarchy for organizational structure. Criteria-based sharing for compliance team. Profiles restricted sensitive fields. Result: Perfect separation – no cross-contamination.
5. What are integration patterns and when to use each?
Request-Reply (Synchronous): Salesforce calls external system, waits for response. Users need immediate results (address validation, inventory check). Trade-off: users wait, 10-second limit.
Fire-and-Forget (Asynchronous): Salesforce triggers process, doesn’t wait. Background operations (post to accounting nightly). Must implement monitoring.
Batch Data Synchronization: Large volumes on schedule via Bulk API. Nightly data warehouse loads.
Remote Call-In: External systems push to Salesforce via APIs. Website forms creating leads.
Data Virtualization: Display external data without storing. Real-time inventory from the warehouse system.
Decision framework: Synchronous for immediate feedback, asynchronous for background processes, batch for large volumes, Remote Call-In when external system initiates, Data Virtualization for frequently changing data.
Advanced 2025-2026 Topics
Agentforce & Agentic Architecture
How do you design multi-agent orchestration?
Design agent topology – which agents handle which functions. Use Atlas Skill Router for intelligent task routing. Implement agent handoffs when escalation is needed. Design state management so agents understand context. Plan monitoring and logging for compliance.
Zero Trust Architecture (Winter ’26 Update)
How do you implement Zero Trust without breaking integrations?
Assume no trust by default. Implement mandatory MFA for all users. Use device fingerprinting. For integrations, move from user-based to app-based auth (JWT, OAuth). Implement IP allowlisting. Create a gradual transition plan. Legacy integrations may need modernization.
Data Cloud for Architects
Design Data Cloud architecture for multi-org enterprise planning Agentforce.
Implement Data Cloud as a central repository ingesting from all orgs plus external systems. Use Einstein Identity to resolve duplicate records. Build insights aggregating across orgs. Connect Agentforce to Data Cloud for 360-degree customer context.
B2B vs B2C Architecture
B2B: Complex sales cycles with multiple stakeholders. Advanced CPQ configurations, account hierarchies, Revenue Cloud, approval workflows.
B2C: High volume, scalability focus. Commerce Cloud for shopping, Marketing Cloud for journeys, self-service mechanisms, personalization.
Key difference: B2B emphasizes account complexity; B2C emphasizes volume and personalization.
Project Management & Soft Skills
Managing Technical Debt
Assess using System Overview, Salesforce Optimizer, Schema Builder. Score by impact/effort – prioritize high impact/low effort. Allocate 10-15% sprint capacity to debt reduction. Prevent new debt via governance (object approvals, coding standards). Track Technical Debt Ratio<15%.
Bridging Technical/Non-Technical Teams
Translation: Don’t say “OAuth 2.0 JWT Bearer Flow.” Say “systems use temporary tokens instead of passwords – more secure.”
Visuals: Use diagrams showing data flow, not technical jargon.
Demos: Conduct bi-weekly demos of working software with feedback loops.
Workshops: Facilitate cross-functional design sessions with business, tech, end-users.
Bidirectional education: Help businesses understand technical constraints; help developers understand business context.
Well-Architected Framework (Trusted, Easy, Adaptable)
Trusted: Secure (encrypt sensitive data, least-privilege), Reliable (system dependability, integration retry logic).
Easy: Simple (use standard features first), Automated (reduce manual work), Engaging (intuitive UX).
Adaptable: Resilient (survive requirement changes), Composable (reusable components).
Apply when making decisions: choose the simplest approach, implement security from day one, design for future flexibility.
Certifications & Career Path
Application Architect Path: Platform App Builder → Platform Developer I → Data Architect → Sharing/Visibility Architect → Application Architect exam
System Architect Path: Dev Lifecycle → Identity/Access → Integration Architecture → Platform Developer I → System Architect exam
Certified Technical Architect (CTA): Requires both architect certs + rigorous 8-hour review board exam before panel of judges. Only ~400 people globally hold this credential.
Timeline: 18-24 months to CTA if studying and working on real projects. Study 1-2 hours daily, weekend projects, join study groups.
Real-World Scenarios
Scenario 1: 50M Accounts Timing Out
Problem: Sales managers’ list views timeout on 50M Account records.
Root cause: Queries not selective – no filters using indexed fields.
Solution: Optimize queries (filter on CreatedDate which is indexed), request custom indexes on frequently filtered fields, create skinny tables for reporting, archive inactive accounts to Big Objects.
Result: List view load time 0.5 seconds (was timing out).
Scenario 2: Multi-Org Acquisition Integration
Challenge: Acquired competitor with separate Salesforce org, different data models.
Strategy: Start multi-org (preserve operations), gradually migrate to single-org. Design unified data model, migrate Company B records to Company A structure, deduplicate customers, train users, cutover.
Timeline: 4 months. Data loss: 0. Annual savings: $500K from avoiding two-org maintenance.
Interview Day Preparation
Before interview:
- Review this guide 2x
- Prepare 3-5 STAR stories with metrics
- Research company’s Salesforce architecture
- Prepare 3-5 questions to ask interviewer
- Get 8 hours sleep
During interview:
- Listen carefully, ask clarification
- Provide specific metrics, not vague statements
- Draw architecture diagrams when explaining
- Acknowledge trade-offs
- Stay calm if you don’t know answer
Recommended Trailhead Practice
Don’t just read the answers – build muscle memory. Here are the specific Trailhead modules to practice the concepts discussed above.
| Interview Topic | Recommended Trailhead Module |
| Architecture Strategy | Build Well-Architected Solutions |
| Data & Performance | Large Data Volumes |
| Integration | Integration Patterns and Practices |
| Security (Zero Trust) | Data Security |
| Identity & OAuth | Identity Basics |
| AI (Agentforce) | Agents and Agentforce Basics |
| Data Cloud | Data Cloud Basics |
| DevOps | Application Lifecycle and Development Models |
Key Takeaways
✓ Every answer should be specific with metrics and examples
✓ Architects think in trade-offs and constraints
✓ Security and performance are foundational, not afterthoughts
✓ Real projects teach more than certifications
✓ Communication skills matter as much as technical depth
✓ Staying current with quarterly releases is critical
✓ Governance prevents technical debt accumulation
Ready to Master Salesforce Architecture?
For more Salesforce architecture insights and real-world implementation guidance, visit 2creative.ca or subscribe to our YouTube channel. We share in-depth technical content on complex Salesforce solutions, architectural patterns, and best practices.
Implementing enterprise Salesforce architecture? Whether you’re designing multi-org strategies, optimizing Large Data Volumes, or building complex integrations, 2creative specializes in helping organizations architect scalable solutions. From interview prep to enterprise implementations, we’re here to help you succeed.
Learn more at 2creative.ca
If you’re working with Salesforce – whether you’re building simple automation, managing complex revenue operations, or handling enterprise-scale integrations – you need to understand Transaction Management in Salesforce. It’s the invisible safety net that keeps your data consistent, your processes reliable, and your business logic intact even when things go wrong.
Think about it this way: You’re processing a customer order. You need to create an Order record, add Order Line Items, update the Account’s Annual Revenue, calculate billing schedules, and trigger fulfillment. All of this has to happen as one atomic unit – if any step fails, the entire order should fail. You can’t end up with an Order but no Line Items. You can’t partially bill a customer. That’s what transaction management guarantees.
But here’s the thing – most developers understand transactions at a surface level. They know DML statements succeed or fail, but they don’t dig into why, how to handle partial failures, what happens under the hood in Salesforce’s multi-tenant architecture, or how to navigate the gotchas that trip up even experienced developers.
This guide walks through everything. Not just the basics, but the edge cases, the architectural decisions, the patterns that work in production, and the mistakes that’ll cost you hours of debugging.
What Exactly Is a Transaction in Salesforce?
A transaction is fundamentally a sequence of database operations – inserts, updates, deletes, upserts – that must complete as a single logical unit. The promise is simple: either all operations succeed, or all operations fail. There’s no middle ground.
But why does this matter in a business context? Imagine you’re building a quote-to-cash system. A quote converts to an Order. That Order should immediately trigger:
- Order Line Item creation with correct pricing
- Account revenue update
- Subscription record creation (if applicable)
- Revenue Recognition entry setup
- Fulfillment notification to warehouse systems
If any of these fails – say, a product is no longer available and Line Item creation fails – you want the entire order conversion to fail. You don’t want an Order without Line Items sitting in your system, waiting to be manually cleaned up.
This is where transactions become critical to business logic, not just database theory.
The ACID Principles: The Foundation of Reliability
Salesforce implements the ACID principles for every transaction. Understanding these isn’t academic – it directly impacts how you design your code.
Atomicity: All or Nothing
Atomicity means that a transaction is indivisible. When you commit changes, either all of them persist, or none of them do. There’s no partially committed state.
Here’s what this looks like in practice:
try {
    Account acc = new Account(Name = 'Enterprise Corp', Industry = 'Technology');
    insert acc;

    Contact con = new Contact(FirstName = 'John', LastName = 'Doe', AccountId = acc.Id);
    insert con;

    Opportunity opp = new Opportunity(Name = 'Enterprise Deal', StageName = 'Prospecting', AccountId = acc.Id);
    insert opp;

} catch (Exception e) {
    // If the Opportunity insert fails, Account and Contact are ALSO rolled back
    System.debug('All records rolled back: ' + e.getMessage());
}
In this code, if the Opportunity insert fails (say, a required field is missing), Salesforce rolls back the Account and Contact inserts too. Your database is left in the state it was before the transaction started.
Without atomicity, you’d end up with orphaned accounts and contacts with no related opportunities.
Consistency: Database Stays Valid
Consistency means that every transaction moves the database from one valid state to another. Validation rules, required fields, foreign key relationships – all constraints are enforced.
If you have a validation rule on Account that says “Annual Revenue must be greater than 0,” and a transaction tries to set Annual Revenue to -1000, the transaction fails. The database stays consistent.
This is particularly important in multi-user environments. When User A updates an Account, they don’t see a partially modified record that User B is still writing to. They see either the old state or the new state – never an in-between.
Isolation: Transactions Don’t Interfere
Isolation ensures that concurrent transactions don’t step on each other’s toes.
Imagine two users simultaneously updating the same Opportunity:
- User A reads the current Close Date: March 31
- User B reads the current Close Date: March 31
- User A updates Close Date to April 15
- User B updates Close Date to May 30
Without isolation, User B’s update might overwrite User A’s update. User A’s change gets lost.
Salesforce prevents this through exclusive row locking. When User A starts modifying the Opportunity, Salesforce locks that record. User B’s request to modify the same record waits (up to 10 seconds) for the lock to be released. If it doesn’t get released in time, User B gets UNABLE_TO_LOCK_ROW error.
The tradeoff? Performance. Locking prevents data corruption but can slow down systems under heavy load.
Durability: Committed Data Survives
Once a transaction commits, it’s permanent. Even if Salesforce’s infrastructure fails immediately after, your data is safe. Salesforce uses write-ahead logging to ensure this – every change is logged to a permanent store before being applied to the database.
Understanding Salesforce’s Architecture for Transactions
Knowing how Salesforce processes transactions under the hood helps you write better code. Here’s the reality:
Salesforce’s infrastructure consists of multiple tiers:
- Application Server Tier: Handles API requests, web UI interactions, and decision-making
- Core App Servers: Typically 10-40 Java Virtual Machines per instance that execute your Apex code, flows, and business logic
- Database Tier: The actual data storage where all changes are committed
But here’s the critical part that most people miss: every single DML operation from a customer must pass through a single database gateway. This isn’t a bottleneck – it’s a design choice to guarantee consistency. All updates are serialized. If two users try to update the same record simultaneously, one transaction must complete before the other can proceed.
This explains why:
- Record locking is necessary
- Deadlocks are possible (and how to avoid them)
- Bulk operations are faster (one serialized request instead of many)
- Concurrent updates on the same record cause contention
When you’re processing thousands of records, you need to be aware of this architecture. Updating records in a random order might cause deadlocks. Updating in a consistent order (always Account before Contact before Opportunity) minimizes lock contention.
Transaction Finalization: When Data Actually Commits
Official Salesforce Order of Execution Flowchart
This is where most developers get confused. Data is not committed to the database until the very end of the order of execution, after all after-triggers have successfully completed.
Here’s the precise flow:
- Before Triggers Execute → Record is modified in memory
- Validation Rules Execute → Check constraints
- Record is Saved to Database Buffer (but NOT committed yet)
- After Triggers Execute → Can modify related records
- All Automation Completes (Flows, Processes, Workflows)
- Only Then: Data is Committed → Now it’s permanent
This is critical because if an after-trigger throws an exception, or a flow fails, or any subsequent logic fails, the entire transaction rolls back – including the record that was “saved” in step 3.
trigger AccountTriggerAfter on Account (after insert) {
    if (Trigger.isAfter && Trigger.isInsert) {
        for (Account acc : Trigger.new) {
            // This executes after the Account insert, but before commit
            List<Contact> contacts = new List<Contact>();
            contacts.add(new Contact(FirstName = 'Default', LastName = 'Contact', AccountId = acc.Id));
            insert contacts; // If this fails, Account insert is ROLLED BACK
        }
    }
}
If the Contact insert fails in this after-trigger, the Account that was inserted in step 3 is not committed. It’s rolled back as if the entire transaction failed.
This is why after-triggers are risky – they can undo work done by before-triggers if they fail.
DML Operations: The Different Execution Paths
Not all DML operations behave the same way. This distinction is crucial for production code.
Standard DML: All-or-Nothing Semantics
Standard DML statements (insert, update, delete, upsert) follow strict all-or-nothing semantics:
List<Account> accounts = new List<Account>();
accounts.add(new Account(Name = 'Company A'));
accounts.add(new Account(Name = 'Company B'));
accounts.add(new Account()); // Missing required Name field

// This entire statement fails - ALL three accounts fail to insert
insert accounts;
If even one record fails validation, the entire operation rolls back. No records are inserted. The database is left unchanged.
This is great for data integrity but problematic if you’re trying to process a large batch where some records might legitimately fail (like in an integration scenario where some external records are invalid).
Database Methods: Partial Success Semantics
The Database class provides methods that allow partial success:
List<Account> accounts = new List<Account>();
accounts.add(new Account(Name = 'Company A'));
accounts.add(new Account()); // Missing required Name

// With second parameter as false, allows partial success
List<Database.SaveResult> results = Database.insert(accounts, false);

for (Database.SaveResult result : results) {
    if (result.isSuccess()) {
        System.debug('Account inserted: ' + result.getId());
    } else {
        for (Database.Error error : result.getErrors()) {
            System.debug('Error on account: ' + error.getMessage());
        }
    }
}
In this case, Company A inserts successfully. Company B fails validation, but you’re aware of the failure and can handle it. The transaction succeeds (at least partially).
This matters enormously in real scenarios:
- Bulk API integration: Some external records are valid, some aren’t. You want to save what you can.
- Data imports: Process 10,000 records. If 9,900 are valid and 100 are malformed, you want to import the 9,900.
- Async processing: Batch apex processes large datasets. You don’t want one bad record to fail the entire batch.
But partial success also means you need robust error handling. You can’t assume all records succeeded.
Savepoints: The Undo Button Within a Transaction
One of the most powerful features in Salesforce transaction management is the savepoint. A savepoint marks a specific point in your transaction where you can later roll back if something goes wrong.
Think of it like this: You’re editing a document. You save it (savepoint). Then you make some changes. If those changes are bad, you reload from the last save.
Savepoint sp = Database.setSavepoint();

try {
    Account acc = new Account(Name = 'Test Account');
    insert acc;
    System.debug('Account inserted successfully');

    // Now try to do something risky
    Integer result = 1 / 0; // This will throw an exception

} catch (Exception e) {
    // Roll back to the savepoint - the Account insert is undone
    Database.rollback(sp);
    System.debug('Transaction rolled back. Account was NOT inserted.');
}
Savepoints are incredibly useful for complex business logic where you want to partially undo work:
Savepoint beforeBillingCalculation = Database.setSavepoint();

try {
    // Create order
    Order ord = new Order(AccountId = accId, Status = 'Draft');
    insert ord;

    // Create line items
    List<OrderItem> lineItems = new List<OrderItem>();
    for (Product2 prod : products) {
        lineItems.add(new OrderItem(OrderId = ord.Id, Product2Id = prod.Id, Quantity = 1));
    }
    insert lineItems;

    // Calculate billing
    calculateBillingSchedules(ord);

} catch (BillingCalculationException e) {
    // Only the billing calculation failed, not the order or line items
    Database.rollback(beforeBillingCalculation);

    // Now we can try an alternative billing approach
    calculateDefaultBilling(ord);
}
However, savepoints have important limitations:
You can only create 5 savepoints per transaction. Each savepoint counts as a DML statement against your limit. If you need more than 5 undo points, you need a different strategy.
// This will fail after the 5th savepoint
Savepoint sp1 = Database.setSavepoint(); // 1st
Savepoint sp2 = Database.setSavepoint(); // 2nd
Savepoint sp3 = Database.setSavepoint(); // 3rd
Savepoint sp4 = Database.setSavepoint(); // 4th
Savepoint sp5 = Database.setSavepoint(); // 5th
Savepoint sp6 = Database.setSavepoint(); // EXCEPTION: Too many savepoints
Savepoint scope doesn’t cross trigger invocations. If you set a savepoint in a before-insert trigger and try to roll back in an after-insert trigger, it won’t work. Each trigger context has its own transaction.
Once you roll back to a savepoint, any savepoints created after it become invalid. You can’t selectively “undo” specific savepoints.
These limitations mean savepoints are best used for handling a specific risky operation, not for designing complex transaction flows.
Governor Limits: The Constraints That Define Your Transaction Scope
Every Salesforce transaction has hard limits on resources. These exist to protect the multi-tenant platform and ensure no single customer’s code hogs resources.
Here are the limits that matter most for transaction management:
Per-Transaction DML Limits
- Synchronous transactions: 150 DML statements
- Asynchronous transactions (Batch/Future): 1,650 DML statements
- Batch Apex execute method: 150 DML statements (limits reset for each batch)
A “DML statement” is a single insert, update, delete, or upsert call. Bulking helps you stay under this limit:
// BAD: 100 DML statements (hits limit immediately)
for (Integer i = 0; i < 100; i++) {
    insert new Account(Name = 'Account ' + i);
}

// GOOD: 1 DML statement
List<Account> accounts = new List<Account>();
for (Integer i = 0; i < 100; i++) {
    accounts.add(new Account(Name = 'Account ' + i));
}
insert accounts;
Per-Transaction Query Limits
- Synchronous: 100 SOQL queries
- Asynchronous: 200 SOQL queries
Exceeding these is common in loops:
// BAD: If accounts has 100+ records, you hit 100 queries
for (Account acc : accounts) {
    Contact con = [SELECT Id FROM Contact WHERE AccountId = :acc.Id];
    // Process contact
}

// GOOD: 1 query
Map<Id, Contact> contactsByAccountId = new Map<Id, Contact>();
for (Contact con : [SELECT Id, AccountId FROM Contact WHERE AccountId IN :accountIds]) {
    contactsByAccountId.put(con.AccountId, con);
}

for (Account acc : accounts) {
    Contact con = contactsByAccountId.get(acc.Id);
    // Process contact
}
Record Retrieval Limits
- Total records retrieved per transaction: 50,000
- This counts all records returned by SOQL/SOSL queries
If you’re processing large datasets, this becomes a real constraint. Batch Apex exists partly to overcome this – each batch execution gets a fresh 50,000-record limit.
Other Critical Limits
- Heap Size: 6 MB for synchronous, 12 MB for asynchronous
- CPU Time: 10,000ms for synchronous, 60,000ms for batch
- Callouts: 100 per transaction (but can’t be mixed with uncommitted DML)
When you hit a governor limit, Salesforce throws a LimitException and your entire transaction rolls back:
for (Integer i = 0; i <= 150; i++) {
    List<Account> accounts = [SELECT Id FROM Account LIMIT 1];
    // After 100 queries, you get:
    // QueryException: Too many SOQL queries: 101
}
Understanding these limits is essential for designing scalable solutions. It’s why:
- Batch Apex is better than loops for large datasets (resets limits per batch)
- Bulk operations are essential (one DML = one statement)
- You can’t call out from triggers without careful planning
- Async processing is necessary for complex operations
Record Locking and Concurrency: The Hardest Part of Transactions
Record locking is where transaction management gets genuinely complex. It’s also where most production issues come from.
When a transaction modifies a record, Salesforce places an exclusive lock on that record. No other transaction can modify it until the lock is released (when the first transaction commits or rolls back).
This prevents data corruption but creates the potential for deadlocks and lock contention.
Exclusive Locking and Lock Contention
Imagine a busy system processing orders. Thousands of users are simultaneously creating, updating, and converting orders.
When User A updates an Order:
Order ord = [SELECT Id, Amount FROM Order WHERE Id = :orderId FOR UPDATE];
ord.Amount = ord.Amount + 100;
update ord;
The FOR UPDATE clause explicitly acquires an exclusive lock before modifying. This prevents other transactions from reading the record (in a consistent way) or modifying it.
If User B tries to update the same Order while User A’s transaction is still running, User B’s request waits. For up to 10 seconds. If the lock isn’t released by then, User B gets UNABLE_TO_LOCK_ROW.
In high-volume systems, this timeout happens constantly. Users see errors. Integrations fail.
The solution is to minimize lock contention:
- Keep transactions short: Don’t perform long-running operations while holding locks
- Update in consistent order: Always update Accounts before Opportunities before Orders
- Avoid hot records: If certain records are updated constantly, consider denormalizing to separate, less-contended records
- Use batch processing for bulk updates: Instead of updating 10,000 records in real-time, batch them in scheduled jobs
Deadlocks: The Classic Problem
A deadlock occurs when two transactions are waiting on each other, neither able to proceed.
User A’s Transaction:
- Locks Opportunity 1
- Tries to lock Opportunity 2 (waiting…)
User B’s Transaction:
- Locks Opportunity 2
- Tries to lock Opportunity 1 (waiting…)
Neither can proceed. Salesforce detects this and kills one of the transactions with UNABLE_TO_LOCK_ROW.
The classic way to prevent deadlocks is lock ordering: Always acquire locks in the same order.
// In Transaction A
Opportunity opp1 = [SELECT Id FROM Opportunity WHERE Id = :opp1Id FOR UPDATE];
Opportunity opp2 = [SELECT Id FROM Opportunity WHERE Id = :opp2Id FOR UPDATE];

// In Transaction B (different user)
Opportunity opp2 = [SELECT Id FROM Opportunity WHERE Id = :opp2Id FOR UPDATE];
Opportunity opp1 = [SELECT Id FROM Opportunity WHERE Id = :opp1Id FOR UPDATE]; // This causes deadlock!
If Transaction B always queries in the same order (opp1 then opp2), deadlocks are prevented.
Parent-Child Locking Complexity
Here’s something many developers don’t realize: when you update a child record, Salesforce also locks the parent.
If you have a deeply nested relationship:
- Account (parent)
- Order (child of Account)
- OrderItem (child of Order)
- Order (child of Account)
And you update OrderItem, you implicitly lock:
- OrderItem
- Order
- Account
If you have 100 concurrent threads updating OrderItems on the same Account, they’re all waiting on the Account lock. This creates massive contention.
Solutions:
- Denormalize to reduce relationship depth
- Batch updates to non-peak hours
- Use scheduled Apex for bulk updates instead of real-time processing
- Consider separating concerns into different objects
Transaction Boundaries and Trigger Context
Triggers are often misunderstood in terms of transaction boundaries. The key rule: a trigger fires within the transaction of the record being modified.
So when you update an Account:
- Before-insert trigger fires (still in original transaction)
- Record is inserted
- After-insert trigger fires (still in original transaction)
- Transaction commits only after all after-insert logic completes
All within a single transaction boundary. If the after-insert trigger throws an exception, the Account insert is rolled back.
Trigger Execution Order Gotchas
If you have multiple triggers on the same object for the same event (e.g., two before-insert triggers), the order in which they fire is not guaranteed. This is a major gotcha because your code might depend on execution order.
If Trigger A updates a field that Trigger B reads, and they fire in reverse order, your logic breaks.
The solution is to use a trigger framework that controls execution order:
// Trigger framework pattern
trigger AccountTrigger on Account (before insert, after insert, before update, after update) {
    TriggerDispatcher.run();
}

public class TriggerDispatcher {
    public static void run() {
        if (Trigger.isInsert && Trigger.isBefore) {
            // Call before-insert handlers in specific order
            AccountBeforeInsertHandler.handle(Trigger.new);
        } else if (Trigger.isInsert && Trigger.isAfter) {
            // Call after-insert handlers in specific order
            AccountAfterInsertHandler.handle(Trigger.new, Trigger.oldMap);
        }
        // ... etc
    }
}
Flow Transaction Boundaries (Critical Detail)
This is where things get tricky. When you have a Flow triggered on a record update:
Transaction 1 (synchronous): Record is updated by the original action
Flow starts → If it contains a Screen element
Transaction 2 (new synchronous): After the screen, a new transaction starts
If something fails in Transaction 2, Transaction 1 isn’t rolled back. Your original update is committed even if downstream operations fail.
This is a major source of data inconsistency bugs:
// Flow triggered on Order update
// Transaction 1: Order.Status updated to "Activated"
// [Flow reaches Screen element - Transaction 1 ends here, Transaction 2 starts]
// Transaction 2: Create fulfillment records
// If fulfillment creation fails, Order is still "Activated"
This is why you need to be careful with Flow design. If a Flow has a Screen element followed by Create Record actions, and the Create fails, your original update isn’t undone.
Local Action and Wait elements also create transaction boundaries.
Asynchronous Processing: Different Transaction Boundaries
When you use asynchronous processing (Batch Apex, Queueable, Future methods, or Scheduled Apex), each execution runs in a separate transaction with its own governor limits.
Batch Apex: Transaction Per Batch
Batch Apex runs records in batches. Each batch gets its own transaction:
global class ProcessAccountsBatch implements Database.Batchable<sObject> {
    global Database.QueryLocator start(Database.BatchableContext bc) {
        return Database.getQueryLocator('SELECT Id FROM Account');
    }

    global void execute(Database.BatchableContext bc, List<Account> accounts) {
        // This is ONE transaction
        // Governor limits reset here
        for (Account acc : accounts) {
            acc.Description = 'Processed';
        }
        update accounts;
    }

    global void finish(Database.BatchableContext bc) {
        // Another transaction
    }
}
Each execute() call is a separate transaction. If batch 1 succeeds but batch 2 fails, batch 1’s changes are NOT rolled back.
This is by design. It allows processing of massive datasets without one bad batch killing everything.
The tradeoff: You can’t guarantee transaction consistency across batches. If you’re processing a million-record migration and batch 500 fails, you’ve already committed 499 batches. You have a partially migrated database.
This is why Batch Apex often needs a “finish” method that validates and potentially triggers compensation logic.
Queueable Apex: Separate Transaction, Job Chaining
Queueable is similar to Batch but more flexible. Each execute() runs in its own transaction, and you can chain jobs:
public class FirstJob implements Queueable {
    public void execute(QueueableContext context) {
        // Insert some records
        insert new Account(Name = 'From Job 1');

        // Chain the next job
        if (shouldContinue()) {
            System.enqueueJob(new SecondJob());
        }
    }
}

public class SecondJob implements Queueable {
    public void execute(QueueableContext context) {
        // Insert more records
        insert new Account(Name = 'From Job 2');
    }
}
Each job is a separate transaction, but you can chain them. This is useful for modularizing long operations or processing based on runtime conditions.
Important: The maximum stack depth for chained jobs is 5 in most orgs (meaning you can chain 4 times). In Developer Edition, it’s limited to 5 total depth.
Future Methods: Simple Async, No Job Info
Future methods are the simplest form of async:
@future
public static void sendNotification(Id orderId) {
    Order ord = [SELECT Id, AccountId FROM Order WHERE Id = :orderId];
    // Send notification
}
Fired when system resources are available. Runs in its own transaction. Can’t return data to the calling transaction.
Scheduled Apex: Deterministic Timing
Scheduled Apex runs at specific times but still respects transaction boundaries:
global class DailyOrderProcessing implements Schedulable {
    global void execute(SchedulableContext context) {
        // Process orders
        List<Order> orders = [SELECT Id FROM Order WHERE Status = 'Pending'];
        for (Order ord : orders) {
            ord.Status = 'Processing';
        }
        update orders;
    }
}
The execution runs in a transaction. If it fails, everything rolls back.
Bulk API 2.0 Transaction Management
Bulk API 2.0 is fundamentally different from Apex in terms of transactions. It’s designed for massive data operations.
Key difference: Bulk API 2.0 doesn’t use traditional Apex transaction semantics. Instead:
- You create a job
- Upload data in batches
- Tell Salesforce processing is complete
- Salesforce processes each batch independently
- Each batch has its own transaction
This means if Batch 1 fails, Batch 2 might still succeed. Bulk API doesn’t enforce atomicity across batches.
Bulk API Job Lifecycle:
1. Create Job
   ↓
2. Upload Batch 1 → Processes with separate transaction
3. Upload Batch 2 → Processes with separate transaction
4. Mark job complete
   ↓
5. Salesforce processes all batches independently
   - Batch 1 succeeds? Commits.
   - Batch 2 fails? Rolls back just Batch 2.
   - Overall job status: "Partial Success"
For Bulk API 2.0, the effective governor limits are the higher of synchronous or asynchronous limits, so you get the async limits (more lenient).
This is perfect for bulk data loads but means you need to handle partial success in your code.
The Callout Conundrum: Why You Can’t Mix Callouts and DML
Here’s a rule that confuses everyone: You can’t make HTTP callouts with uncommitted DML.
try {
    Account acc = new Account(Name = 'New Account');
    insert acc; // Insert happens, but not yet committed

    // This will throw CALLOUT_NOT_AVAILABLE exception
    Http http = new Http();
    HttpRequest req = new HttpRequest();
    req.setEndpoint('https://api.example.com/verify');
    req.setMethod('GET');
    HttpResponse res = http.send(req);

} catch (CalloutException e) {
    System.debug('Callout failed: ' + e.getMessage());
}
Why? Because callouts are inherently unreliable. They can timeout, fail, or hang indefinitely. Salesforce can’t guarantee that a callout will succeed, so it won’t let you make a callout while changes are pending – it could leave your database in an inconsistent state.
The workaround is to commit the transaction before calling out:
try {
    Account acc = new Account(Name = 'New Account');
    insert acc; // Committed

    // Now we can call out (transaction is closed)
    Http http = new Http();
    HttpRequest req = new HttpRequest();
    req.setEndpoint('https://api.example.com/verify?accountId=' + acc.Id);
    req.setMethod('GET');
    HttpResponse res = http.send(req);

} catch (Exception e) {
    System.debug('Error: ' + e.getMessage());
}
Or use a Future method to separate the callout into its own transaction:
// In your main transaction
Account acc = new Account(Name = 'New Account');
insert acc;

// Enqueue the callout separately
sendVerificationAsync(acc.Id);

@future(callout = true)
private static void sendVerificationAsync(Id accountId) {
    Http http = new Http();
    // Make the callout
}
This is crucial for integrations. You can’t validate external systems within the same transaction as your Salesforce DML.
Mixed DML Operations: The Setup Object Constraint
Salesforce has an unusual constraint: you can’t mix DML operations on setup objects and non-setup objects in the same transaction.
Setup objects affect user access. They include:
- User
- UserRole
- Permission Set
- Permission Set Assignment
- Territory
- User Territory
- ObjectPermissions
- FieldPermissions
Non-setup objects are everything else (Account, Contact, Opportunity, custom objects, etc.).
This restriction exists to prevent permission-related issues. If you’re updating a User’s permission set and simultaneously creating records that the user would see, Salesforce can’t guarantee the user sees the correct records.
try {
    // Update a non-setup object
    Account acc = new Account(Name = 'Test');
    insert acc;

    // Try to update a setup object
    PermissionSet ps = [SELECT Id FROM PermissionSet WHERE Name = 'Custom_Permission'];
    // This throws MIXED_DML_OPERATION exception

} catch (Exception e) {
    System.debug('Mixed DML error: ' + e.getMessage());
}
The solution is to separate them into different transactions:
// Async method for setup object operations
@future
public static void updatePermissionsAsync() {
    PermissionSet ps = [SELECT Id FROM PermissionSet WHERE Name = 'Custom_Permission'];
    PermissionSetAssignment psa = new PermissionSetAssignment(
        PermissionSetId = ps.Id,
        AssigneeId = userId
    );
    insert psa;
}

// Main transaction handles non-setup objects
Account acc = new Account(Name = 'Test');
insert acc;

// Trigger permission update separately
updatePermissionsAsync();
Platform Events and Transaction Finalization
Platform events are a powerful pattern for decoupling operations within a transaction. They’re published either immediately or after commit, depending on configuration.
// In your transaction
Order ord = new Order(AccountId = accId);
insert ord;

// Publish event
OrderCreated__e event = new OrderCreated__e(
    Order_Id__c = ord.Id,
    Account_Id__c = ord.AccountId
);
EventBus.publish(event);
If the event is configured to publish after commit, it’s only sent to subscribers once your transaction successfully commits. If something fails and rolls back, the event is never published.
This is perfect for triggering downstream processes (like fulfillment notifications) only after you’re sure the order is committed.
// The event is only published after this transaction commits successfully
try {
    createOrder(orderId);
} catch (Exception e) {
    // If order creation fails, the event is never published
}
Real-World Patterns in Revenue Cloud
Revenue Cloud (formerly RLM) is where transaction management gets complex. The entire quote-to-cash flow is a series of dependent transactions.
Quote Creation Transaction
When a user creates a quote:
- Quote record is inserted
- Quote Line Items are created based on product selections
- Pricing calculations occur
- Discounts are applied
- Commission calculations happen
All of this must succeed atomically. If pricing calculation fails, the entire quote creation fails.
Quote Validation and Approval
Once created, quotes go through validation:
- Required fields are checked
- Discount limits are validated
- Product availability is confirmed
- Customer credit checks happen (possibly via callout)
These validations create separate transaction boundaries. If a callout (credit check) fails, the quote isn’t rolled back – just the approval is denied.
Quote to Order Conversion
The most complex part. Converting a quote to an order:
- Create Order record with quote data
- Create Order Line Items matching Quote Line Items
- Lock prices (prevent future changes)
- Calculate line-item net amounts
- Calculate totals and tax
- Create subscription records (if applicable)
- Mark original quote as superseded
If any step fails, the entire conversion should fail. This is where savepoints become useful:
Savepoint beforeConversion = Database.setSavepoint();

try {
    Order ord = new Order(
        AccountId = quote.AccountId,
        QuoteId = quote.Id
    );
    insert ord;

    List<OrderItem> items = new List<OrderItem>();
    for (QuoteLineItem qli : quote.QuoteLineItems) {
        items.add(new OrderItem(
            OrderId = ord.Id,
            Product2Id = qli.Product2Id,
            Quantity = qli.Quantity,
            UnitPrice = qli.UnitPrice
        ));
    }
    insert items;

    // Calculate taxes and totals
    calculateOrderTotals(ord);

} catch (Exception e) {
    Database.rollback(beforeConversion);
    throw new QuoteConversionException('Conversion failed: ' + e.getMessage());
}
Error Handling and Exception Management
Production transaction management isn’t just about preventing errors – it’s about handling them gracefully.
Here’s a realistic production pattern:
public class OrderProcessor {
    public static void processOrder(Id orderId) {
        Savepoint sp = Database.setSavepoint();

        try {
            Order ord = [SELECT Id, AccountId, Amount, Status FROM Order WHERE Id = :orderId];

            // Validate before doing anything
            validateOrder(ord);

            // Create billing records
            List<Billing__c> billings = createBillingRecords(ord);
            insert billings;

            // Create fulfillment records
            List<Fulfillment__c> fulfillments = createFulfillmentRecords(ord);
            insert fulfillments;

            // Mark order as activated
            ord.Status = 'Activated';
            ord.Activated_Date__c = System.now();
            update ord;

            // Log success
            logTransaction(orderId, 'SUCCESS', null);

            // Publish event for downstream processes
            EventBus.publish(new Order_Activated__e(Order_Id__c = orderId));

        } catch (ValidationException e) {
            // Business logic failed - roll back and notify
            Database.rollback(sp);
            logTransaction(orderId, 'VALIDATION_FAILED', e.getMessage());
            sendErrorNotification(orderId, 'Order validation failed: ' + e.getMessage());

        } catch (Exception e) {
            // Unexpected error - log everything
            Database.rollback(sp);
            logTransaction(orderId, 'SYSTEM_ERROR', e.getMessage() + ' | ' + e.getStackTraceString());

            // Publish error event for alerting
            EventBus.publish(new Order_Processing_Error__e(
                Order_Id__c = orderId,
                Error_Message__c = e.getMessage(),
                Stack_Trace__c = e.getStackTraceString()
            ));

            // Re-throw if appropriate
            throw e;
        }
    }

    private static void validateOrder(Order ord) {
        if (String.isBlank(ord.AccountId)) {
            throw new ValidationException('Order must have an Account');
        }

        if (ord.Amount <= 0) {
            throw new ValidationException('Order amount must be greater than 0');
        }

        if (ord.Status != 'Draft') {
            throw new ValidationException('Only Draft orders can be activated');
        }
    }

    private static void logTransaction(Id orderId, String status, String errorMsg) {
        Order_Transaction_Log__c log = new Order_Transaction_Log__c(
            Order__c = orderId,
            Status__c = status,
            Error_Message__c = errorMsg,
            Processed_At__c = System.now()
        );
        insert log;
    }

    private static void sendErrorNotification(Id orderId, String message) {
        // Send async to avoid mixing with DML
        sendNotificationAsync(orderId, message);
    }

    @future
    private static void sendNotificationAsync(Id orderId, String message) {
        // Send email or post to Slack
    }
}
This pattern:
- Uses savepoints for rollback control
- Validates early (fail fast)
- Has specific exception handling for different failure modes
- Logs all transactions for audit
- Uses async for notifications (avoid callout constraints)
- Re-throws for caller notification when appropriate
Limits Class: Monitoring Your Transaction
Salesforce provides the Limits class to monitor your resource consumption within a transaction:
public static void monitorTransactionLimits() {
    System.debug('DML Statements: ' + Limits.getDmlStatements() + ' / ' + Limits.getLimitDmlStatements());
    System.debug('SOQL Queries: ' + Limits.getQueries() + ' / ' + Limits.getLimitQueries());
    System.debug('Heap Size: ' + Limits.getHeapSize() + ' / ' + Limits.getLimitHeapSize());
    System.debug('CPU Time: ' + Limits.getCpuTime() + ' / ' + Limits.getLimitCpuTime());
    System.debug('Callouts: ' + Limits.getCallouts() + ' / ' + Limits.getLimitCallouts());
}
Use this to understand your transaction’s resource consumption and optimize accordingly:
List<Account> accounts = [SELECT Id FROM Account LIMIT 1000];

System.debug('Before loop - Queries: ' + Limits.getQueries());

for (Account acc : accounts) {
    // This is inefficient but Limits will show it
    List<Contact> contacts = [SELECT Id FROM Contact WHERE AccountId = :acc.Id];
}

System.debug('After loop - Queries: ' + Limits.getQueries()); // Shows 1001 queries
Governor Limits in Action: Practical Examples
Let’s see how governor limits actually play out in real scenarios.
Scenario 1: Bulk Update That Hits DML Limit
// Your requirement: Update all Accounts created in the last 30 days
List<Account> accountsToUpdate = [
    SELECT Id, CreatedDate
    FROM Account
    WHERE CreatedDate = LAST_N_DAYS:30
]; // Might return 2000 records

// WRONG: This hits DML limit
for (Account acc : accountsToUpdate) {
    acc.Description = 'Recently reviewed';
    update acc; // This is 2000 DML statements!
}

// RIGHT: Bulk the update
List<Account> accountsToUpdate = [
    SELECT Id, CreatedDate
    FROM Account
    WHERE CreatedDate = LAST_N_DAYS:30
    LIMIT 1000 // Stay under record limit
];

for (Account acc : accountsToUpdate) {
    acc.Description = 'Recently reviewed';
}
update accountsToUpdate; // 1 DML statement
Scenario 2: Query Limit in a Loop
// WRONG: Queries in loop
for (Account acc : accounts) {
    // This query executes for every account - 100+ queries!
    Contact con = [SELECT Id, Email FROM Contact WHERE AccountId = :acc.Id];
    sendEmail(con.Email);
}

// RIGHT: Bulk query
Map<Id, Contact> contactsByAccountId = new Map<Id, Contact>();
for (Contact con : [SELECT Id, Email, AccountId FROM Contact WHERE AccountId IN :accountIds]) {
    contactsByAccountId.put(con.AccountId, con);
}

for (Account acc : accounts) {
    Contact con = contactsByAccountId.get(acc.Id);
    if (con != null) {
        sendEmail(con.Email);
    }
}
Scenario 3: Batch Processing for Large Datasets
// Requirement: Process 100,000 orders
// You can't do this in a synchronous transaction (150 DML limit, 100 query limit)

global class BulkOrderProcessor implements Database.Batchable<sObject> {
    global Database.QueryLocator start(Database.BatchableContext bc) {
        // Query returns up to 50 million records, but processed in batches
        return Database.getQueryLocator([SELECT Id FROM Order WHERE Status = 'Pending']);
    }

    global void execute(Database.BatchableContext bc, List<Order> orders) {
        // Each batch gets fresh limits (150 DML, 100 queries)
        for (Order ord : orders) {
            ord.Status = 'Processing';
        }
        update orders;
    }

    global void finish(Database.BatchableContext bc) {
        // Final cleanup
    }
}

// Execute it
Database.executeBatch(new BulkOrderProcessor(), 200); // 200 records per batch
Testing Transactions: Unit Test Considerations
Testing transaction management requires specific approaches. Standard unit tests run in a transaction that’s rolled back, which masks some real-world behaviors.
@isTest
private class OrderProcessingTest {
    @isTest
    static void testOrderProcessingSuccess() {
        // Setup
        Account acc = new Account(Name = 'Test Account');
        insert acc;

        Order ord = new Order(
            AccountId = acc.Id,
            Status = 'Draft',
            Amount = 10000
        );
        insert ord;

        // Test
        Test.startTest();
        OrderProcessor.processOrder(ord.Id);
        Test.stopTest();

        // Verify
        Order updatedOrder = [SELECT Status FROM Order WHERE Id = :ord.Id];
        System.assertEquals('Activated', updatedOrder.Status);
    }

    @isTest
    static void testOrderProcessingValidationFailure() {
        Order ord = new Order(
            AccountId = null, // Invalid
            Status = 'Draft',
            Amount = -1000 // Invalid
        );
        insert ord;

        Test.startTest();
        try {
            OrderProcessor.processOrder(ord.Id);
            System.assert(false, 'Should have thrown exception');
        } catch (ValidationException e) {
            System.assert(e.getMessage().contains('validation failed'));
        }
        Test.stopTest();
    }
}
Key considerations:
- Use Test.startTest() and Test.stopTest() to isolate async operations
- For savepoint testing, verify that rollback actually undoes changes
- Test both success and failure paths
- Verify that error logging captures the right details
Production Best Practices
After working with hundreds of Salesforce implementations, here’s what actually works in production:
1. Validate Early, Fail Fast
Don’t start DML operations if you know they’ll fail. Validate everything first:
public static void validateBeforeDML(List<Order> orders) {
    for (Order ord : orders) {
        if (ord.Amount <= 0) {
            throw new ValidationException('Amount must be positive');
        }
        if (String.isBlank(ord.AccountId)) {
            throw new ValidationException('Account is required');
        }
    }

    // Only if validation passes, proceed with DML
    update orders;
}
2. Use Batch Apex for Large Volumes
Never process more than a few thousand records in a synchronous transaction:
// Requirement: Update a million records
Database.executeBatch(new MassUpdateBatch(), 2000);
3. Monitor and Log Transactions
Every transaction should produce a log entry. This is invaluable for debugging:
public static void logTransaction(String operation, Integer recordCount, String status) {
    Transaction_Log__c log = new Transaction_Log__c(
        Operation__c = operation,
        Record_Count__c = recordCount,
        Status__c = status,
        Limits_Used__c = Limits.getDmlStatements() + ' of ' + Limits.getLimitDmlStatements(),
        Timestamp__c = System.now()
    );
    insert log;
}
4. Design for Concurrency
Assume multiple users will perform the same operation simultaneously:
- Order updates in consistent order (by Id)
- Use exclusive locking (FOR UPDATE) only when necessary
- Keep transactions short
- Minimize contention on frequently-updated records
5. Use Asynchronous Processing Strategically
- Heavy computation → Batch Apex
- Chained operations → Queueable
- Simple fire-and-forget → Future method
- Scheduled tasks → Scheduled Apex
6. Separate Concerns with Platform Events
Use Platform Events to decouple your core transaction from downstream notifications:
// Core transaction
Order ord = new Order(...);
insert ord;

// Downstream logic triggered via event
EventBus.publish(new Order_Created__e(Order_Id__c = ord.Id));
Conclusion
Transaction management in Salesforce is both simple and complex. Simple because the fundamental rule is clear: either all operations succeed or all fail. Complex because the details matter – record locking, governor limits, savepoint scope, concurrent updates, multi-tenant architecture, and the specific way Salesforce finalizes transactions all impact how you design production code.
The key is understanding not just the rules, but the why behind them. Why does Salesforce have governor limits? To protect the shared platform. Why exclusive locking? To prevent data corruption under concurrent access. Why can’t you mix callouts and DML? Because callouts are unreliable. Why separate transaction boundaries in Flows? To allow more flexible automation.
Once you understand the reasoning, the patterns become clear. Bulk operations. Async processing for large volumes. Early validation. Proper error handling. Logging everything. Design for concurrency.
Build with these principles, and your Salesforce solutions will be reliable, scalable, and maintainable – even under stress. Your users will never see transaction-related errors. Your data will stay consistent. Your revenue operations will flow smoothly from quote to cash.
When you’re building modern applications, you’re probably juggling multiple frameworks, platforms, and tools. Your main Salesforce org sits at the heart of your business, but your data and workflows need to live everywhere else too – in customer portals, partner sites, your custom applications built on React or Angular, or internal enterprise tools. And here’s the thing: you don’t want to rebuild everything from scratch just because it needs to work outside of Salesforce.
That’s where Lightning Out 2.0 comes in. It’s Salesforce’s fresh take on bringing your Lightning Web Components (LWCs) directly into any external application. If you’ve heard of Lightning Out (Beta), this is completely different – it’s a ground-up rewrite using modern web standards and the Lightning Web Runtime, and it’s now Generally Available in Winter ’26.
Let me walk you through what makes this such a big deal for developers, and then we’ll get into the practical stuff.
What’s Wrong with Lightning Out (Beta)? Why Do We Need 2.0?
Before we celebrate Lightning Out 2.0, it helps to understand what it’s replacing.
Lightning Out (Beta) was around for a while, and it did let you embed Aura components into external apps. But it had real limitations. It required you to tie everything to Aura architecture, components ran directly on the host page without isolation, and there were security concerns because malicious scripts from the host page could interfere with your Salesforce components. Plus, if you had CSS conflicts or JavaScript conflicts, you were stuck dealing with them.
The beta version also forced you to handle authentication manually using session IDs or OAuth access tokens – which meant more code you had to write and maintain. And you could only use Aura components, not the modern Lightning Web Components everyone’s moving toward.
Lightning Out 2.0 threw all of that out the window. It’s a brand new feature built on Lightning Web Runtime (LWR) – the same runtime that powers modern Salesforce Experience Cloud sites. It’s completely separate from Lightning Out (Beta), not an extension of it.
Lightning Out 2.0: Here’s What You’re Actually Getting
At the most basic level, Lightning Out 2.0 lets you take Lightning Web Components you’ve already built inside Salesforce and embed them into any external application. React, Angular, Vue, plain JavaScript – it doesn’t matter. Your component loads, connects securely to your Salesforce data, and works like it was native to the host app.
But there’s more depth to it than that.
It’s Powered by Lightning Web Runtime (LWR)
Lightning Web Runtime is Salesforce’s lightweight JavaScript runtime built for performance and flexibility. Unlike the older Aura framework, LWR uses standards-based web components. What that means practically is faster performance, smaller bundle sizes, and compatibility with modern JavaScript practices.
The architecture is designed to handle scale. If you’re embedding components into a customer portal that gets millions of visits, Lightning Out 2.0 is built to handle that traffic without choking.
Iframe Isolation: The Security Game-Changer
Here’s something that matters a lot but people sometimes gloss over: Lightning Out 2.0 runs each embedded component inside an iframe with a closed shadow DOM. This is intentional, and it’s actually great for security.
In Lightning Out (Beta), components ran directly on the host page. That meant a malicious script on the host page could reach into your Salesforce component, mess with its JavaScript, manipulate its CSS, or even try to intercept events. It was a real attack surface.
With iframe isolation in Lightning Out 2.0, your Salesforce components are locked away in their own sandbox. The host page’s CSS can’t bleed into your component. The host page’s JavaScript can’t touch your component’s code. And hostile scripts on the host page have no way to reach across that iframe boundary.
Salesforce uses a Content Security Policy (CSP) directive that explicitly says “only this external app is allowed to load the Lightning Out 2.0 script.” That’s strong. And on top of that, Lightning Web Security (LWS) is automatically applied to your embedded components, giving you modern security features by default.
Now, you might be wondering: “If my components are locked in an iframe, how do they actually talk to the host page?” That’s a great question, and Salesforce solved it with postMessage().
Communication Across the Iframe Boundary
Lightning Out 2.0 wraps custom events using window.postMessage() to let components and the host page talk to each other safely. Here’s the important part: from your perspective as a developer, you don’t need to think about postMessage directly. You still create and dispatch custom events exactly like you normally would in LWC using the CustomEvent constructor and dispatchEvent() method.
Behind the scenes, Lightning Out 2.0 is handling the cross-iframe communication. An event fired inside the embedded component bubbles up through the iframe boundary, gets wrapped in a postMessage call, travels across to the host page, unwraps, and your host page receives it as a normal JavaScript event. It works in both directions too – the host page can dispatch events down to the component the same way.
This is actually really clever because it means your component code stays clean and familiar. You’re not writing iframe-specific code.
Performance That Matters
LWR components are noticeably faster than their Aura counterparts. The runtime is optimized for modern browsers, the component rendering engine is efficient, and the lazy loading capabilities mean you only load what you need when you need it.
For external embedding, this matters because every millisecond counts when your portal or partner site is loading. Lightning Out 2.0 is designed with performance in mind from the ground up.
How Lightning Out 2.0 Actually Works: The Flow
Let me break down what actually happens when you embed a component.
Step 1: Setup in Salesforce
First, you configure your Lightning Out 2.0 app in Salesforce. You go to Setup, find the Apps section, and there’s now a new menu for Lightning Out 2.0 App Manager. You create an app, add the custom LWC components you want to embed, and configure any styling or properties those components should have.
When you save your Lightning Out 2.0 app, Salesforce generates a script tag – a specific JavaScript snippet that you’ll copy and paste into your external application.
Step 2: Authentication Setup
Here’s where the UI Bridge API comes in. The UI Bridge API is how your external app exchanges a valid Salesforce access token (or the current session ID if you’re in a Salesforce context) for what’s called a frontdoor URL.
The frontdoor URL is basically a secure bridge that tells Salesforce “this person is authenticated, I’ve verified their credentials, let them access their data.” It’s how Lightning Out 2.0 maintains a secure session without exposing sensitive information to the host app.
If the user isn’t already logged into Salesforce, the OAuth authorization flow gets triggered automatically. Your users don’t need to log in twice – the system figures it out.
Step 3: Loading the Script and Initializing
On your external host page, you include the Lightning Out 2.0 JavaScript library that was generated in the App Manager. Then you add the lightning-out-application component to your HTML. This component needs two attributes:
- frontdoor-url: The secure bridge URL you got from the UI Bridge API
- components: A comma-separated list of the component names you want to embed
The script bootstraps the connection to Salesforce using that frontdoor URL, establishes the session, and then initializes each component you specified.
Step 4: Components Render in Iframes
Once the session is established, Lightning Out 2.0 creates an iframe for each embedded component. Inside each iframe, the actual LWC component runs in the Salesforce context. From the host page’s perspective, it just sees the iframe. Inside the iframe, the component has full access to Salesforce data services, the Lightning UI components, and everything else it would have inside the Salesforce Platform.
The lightning-out-application element fires custom events to let you know what’s happening:
- lo.application.ready: Fires when the Salesforce session is successfully established
- lo.application.error: Fires if something goes wrong with authentication
- lo.component.ready: Fires when individual components finish initializing
You can listen for these events on the host page and respond accordingly – show a loading spinner until lo.component.ready, display an error message if lo.application.error fires, that kind of thing.
Setting Up Lightning Out 2.0: What You Actually Need to Do
If you want to actually embed components, here’s the practical checklist.
In Salesforce Setup
- Make sure you’re on Winter ’26 or later (this feature needs the latest platform)
- Navigate to Setup > Apps > Lightning Out 2.0 App Manager
- Create a new Lightning Out 2.0 app
- Add your custom LWC components to the app (standard components and base components aren’t supported yet – just custom LWCs)
- Configure any default styles or properties using SLDS styling hooks or CSS custom properties
- Save the app and copy the generated script
That’s the Salesforce side. The script Salesforce generates is your starting point for the external app.
In Your External App
- Add the Lightning Out 2.0 script to your HTML page
- Create a div or container where your component will mount
- Add the lightning-out-application component with your frontdoor-url and component list
- Set up the UI Bridge API call to get your frontdoor-url from a valid Salesforce session
- Listen for the lifecycle events to know when things are ready
Here’s what a simplified example looks like:
<!DOCTYPE html>
<html>
<head>
  <title>External App with Embedded LWC</title>
</head>
<body>
  <div id="app-container"></div>

  <script src="https://your-salesforce-instance.lightning.force.com/lightning/lightning-out.js"></script>
  <script>
    // Get frontdoor URL from UI Bridge API
    // This assumes you have a valid Salesforce session
    async function initLightningOut() {
      const frontdoorUrl = await getFrontdoorUrl(); // Your auth logic here

      const lightningOutApp = document.createElement('lightning-out-application');
      lightningOutApp.setAttribute('frontdoor-url', frontdoorUrl);
      lightningOutApp.setAttribute('components', 'c-my-component,c-another-component');

      lightningOutApp.addEventListener('lo.application.ready', () => {
        console.log('Salesforce session established');
      });

      lightningOutApp.addEventListener('lo.application.error', (e) => {
        console.error('Authentication failed:', e.detail.message);
      });

      document.getElementById('app-container').appendChild(lightningOutApp);
    }

    initLightningOut();
  </script>
</body>
</html>
Styling: Making Components Match Your App
One thing people worry about is: “Will my Salesforce component look out of place in my external app?”
Lightning Out 2.0 handles this with CSS custom properties and SLDS styling hooks. You can override styles at runtime without touching your component code.
When you set up your Lightning Out 2.0 app, you can declare CSS custom properties in the App Manager. Your embedded component can reference these properties in its CSS, and the host app can set the values. So if your external app uses a different primary color, different typography, different spacing – your component adapts.
The way this works is through SLDS 2 (Salesforce Lightning Design System version 2), which is based on CSS custom properties. Your component declares something like:
--slds-c-button-color-background: var(--primary-color);And the external app provides:
<c-my-component style="--primary-color: #FF6B35;"></c-my-component>Your component inherits the color from the host app. Clean and simple.
Component Communication: Talking Between Iframe and Host
Let’s say you have an embedded component that displays a data table, and when a user clicks a row, you want the host app to update something on its side. Or vice versa – the host app wants to tell the component to refresh its data.
Custom events handle this. Inside your LWC component, you dispatch a custom event like normal:
this.dispatchEvent(new CustomEvent('rowselected', {
  detail: { recordId: this.selectedRecord.Id },
  bubbles: true,
  composed: true
}));
On the host page, you listen for it:
const lightningOutComponent = document.querySelector('c-my-component');
lightningOutComponent.addEventListener('rowselected', (e) => {
  console.log('Row selected:', e.detail.recordId);
  // Update your host app
});
The iframe boundary is transparent to you. Lightning Out 2.0 wraps the event in a postMessage call, sends it across, and your host page receives it.
Going the other direction, the host page can dispatch an event:
const event = new CustomEvent('loadnewdata', {
  detail: { filter: 'active' },
  bubbles: true,
  composed: true
});
lightningOutComponent.dispatchEvent(event);
Your component receives it and responds. It’s bidirectional communication with standard JavaScript events.
Let us give you some scenarios where Lightning Out 2.0 shines.
- Customer Portal with Embedded Components: A SaaS company built their main web portal in React. They want to show customers a case status component that pulls live data from their Salesforce Service Cloud. Instead of building a duplicate case status view in React, they embed their existing Lightning Web Component.
The component updates in real time with new cases, the styling matches the portal’s design, and they don’t have to write a single line of duplicate code.
- Partner Portal with Account Information: A B2B company wants their partners to see their account details, available products, and pricing through a custom portal. They build this portal as an Angular app, but instead of hooking up all the data queries themselves, they embed their Lightning Web Components that already handle account queries, product filtering, and pricing logic.
The partner portal is now a thin UI on top of their Salesforce data, and any changes to their pricing logic automatically flow through to all partners.
- Internal Tools Dashboard: An enterprise has built custom internal tools in Vue.js for their operations team. They want to show Salesforce data dashboards in these tools without maintaining separate dashboard views.
They embed Lightning components that already exist in their Salesforce org. Now operators see their tools and their Salesforce data in one interface.
- External Application Integration: A company uses a third-party platform for inventory management. They want to add a “create Salesforce opportunity” button that’s smart – it pulls pricing from Salesforce, applies account discounts, and creates the opportunity with all the right data.
Instead of building a standalone API integration with a UI, they embed a custom Lightning component. The component knows how to talk to Salesforce, and the inventory app just hosts it.
What’s NOT Supported Yet (And What’s Coming)
Lightning Out 2.0 is GA, but it’s also relatively new. There are some things that aren’t on the table yet.
No Aura Components: You can only embed custom Lightning Web Components right now. If you’ve got legacy Aura components you want to share, they won’t work with Lightning Out 2.0. Salesforce is working on this, but it requires deeper architectural work because Aura has tight integrations that LWC doesn’t have.
No Standard/Base Components (Yet): You can’t directly embed standard Lightning base components like lightning-button or lightning-card into external apps through Lightning Out 2.0 – at least not right now. You need to wrap them in your own custom component. Again, Salesforce is working on this for post-GA releases.
Unauthenticated Access Is on the Roadmap: Right now, Lightning Out 2.0 requires authenticated users. You can’t embed a public-facing component that anyone can see without logging in. But this is actively being developed.
OmniStudio Functionality: If your use case heavily depends on OmniStudio features (like complex integration procedures, datamappers, etc.), Salesforce recommends checking out Omni Out instead, which is specifically designed for OmniStudio components.
Third-Party Cookies Required: Browsers need to allow third-party cookies for Lightning Out 2.0 to work. Cross-domain Salesforce session cookies also need to be enabled in your org. This is a security consideration some organizations need to think through.
CORS Configuration: Setting Up the Bridge
For Lightning Out 2.0 to work, your external app’s domain needs to be in Salesforce’s Cross-Origin Resource Sharing (CORS) allowlist. This is a security feature that explicitly says “these external domains are allowed to load Lightning Out 2.0 components.”
In Setup, you go to CORS settings and add your domain. This is pretty straightforward but it’s something to remember – you can’t just embed Lightning components from random external domains. It’s intentional, explicit, and controlled by the org admin.
Lightning Out 2.0 vs. Lightning Out (Beta): The Feature Comparison
If you’re trying to decide whether to upgrade from Lightning Out (Beta), here’s what changed:
| Feature | Lightning Out 2.0 | Lightning Out (Beta) |
| Technology | Lightning Web Runtime (LWR) | Aura Framework |
| Component Types | Custom LWCs only | Custom LWCs, Aura, some base components |
| Isolation | Iframe with closed shadow DOM | Direct DOM insertion |
| Security | Lightning Web Security (LWS) + CSP | Lightning Locker |
| Authentication | UI Bridge API + OAuth 2.0 | Manual session ID or OAuth token |
| Styling | CSS custom properties via SLDS 2 | Limited styling options |
| Events | Fully supported via postMessage | Not supported |
| Configuration | Declarative + Programmatic | Programmatic only |
| Performance | Lighter, faster | Heavier |
| Unauthenticated Access | Not yet (roadmap) | Supported |
Lightning Out 2.0 is clearly the future. It’s cleaner, more modern, more secure, and performs better. If you’re starting a new project, use Lightning Out 2.0.
Security: How Your Data Stays Safe
Security is baked into Lightning Out 2.0’s architecture, not bolted on.
Iframe Isolation: Your components run in iframes, which are their own execution context. Code in the host page can’t reach your component’s code.
Shadow DOM: Each component’s DOM is in a closed shadow DOM. The host page can’t traverse into it or modify elements.
Content Security Policy: Salesforce uses CSP headers to explicitly allow only your external app to load the Lightning Out 2.0 app. No other domain can sneak in and try to embed your components.
Lightning Web Security: LWS is applied automatically to embedded LWCs. It provides API distortions that prevent unsafe operations and keep code in a secure sandbox.
Session Management: Your component gets access through a frontdoor URL, not a raw session ID or token. This frontdoor URL is a temporary, secure bridge that Salesforce validates on each request.
Event Communication: Events are wrapped in postMessage calls, which only work between explicitly related frames. An unrelated iframe can’t intercept or manipulate events between your component and the host.
It’s hard to break this model. That doesn’t mean it’s impossible – no security is perfect – but it’s built on solid foundations.
Performance Considerations: Making It Fast
Lightning Out 2.0 is optimized for performance, but there are still things to think about.
Bundle Size: LWR is lighter than Aura, so your components have a smaller footprint. But you’re still loading a JavaScript runtime and your components. On the first load, there’s some overhead. Subsequent loads are faster because browsers cache the runtime.
Network Latency: Every component in an iframe makes a connection to Salesforce. If you’re embedding five components on a page, that’s multiple connections. It usually isn’t a problem, but it’s worth being aware of.
Lazy Loading: You don’t have to load all components at once. Load them as needed, show a spinner while they’re loading, and the page feels responsive.
Caching: Use @wire with cacheability turned on for Apex methods. LWC handles client-side caching automatically, so repeated calls for the same data don’t go back to the server.
Data Transfer: Only query and transfer the data you actually need. Don’t pull massive datasets into components if you’re only displaying a summary.
For most use cases, Lightning Out 2.0 performs really well. But like any technology, thoughtful architecture matters.
Getting Started: Your First Lightning Out 2.0 App
Here’s a practical path forward if you want to try this:
- Make Sure You’re on Winter ’26: Check your org’s release version. You need Winter ’26 or later.
- Create a Simple LWC: Build a basic component that does something useful – displays data, has a button that dispatches an event, something concrete. Nothing fancy for your first one.
- Configure in App Manager: Go to Setup > Apps > Lightning Out 2.0 App Manager and create a new app. Add your component to it.
- Get the Script: Copy the generated script snippet.
- Set Up CORS: Add your external app’s domain to the CORS allowlist in Salesforce Setup.
- Test Locally: Create a simple HTML page locally that loads the script and embeds your component. Get the authentication flow working.
- Expand: Once you have the basics down, add event communication, multiple components, styling customization, whatever your use case needs.
The learning curve isn’t steep if you already understand LWC. The main new pieces are the UI Bridge API for authentication and understanding how postMessage event wrapping works – but honestly, you can mostly ignore that implementation detail and just use events normally.
Wrapping Up: Why Lightning Out 2.0 Matters
At the end of the day, Lightning Out 2.0 is about breaking down the walls between Salesforce and the rest of your tech stack. For years, if you wanted to use Salesforce data somewhere else, you had to either:
- Build a REST API and duplicate UI logic
- Use Lightning Out (Beta) and deal with its limitations
- Accept that your Salesforce and external systems would be separate
Lightning Out 2.0 changes that equation. You can reuse your Salesforce components. You can deploy once and use it everywhere. You get consistency – both for developers (one codebase) and for users (one look and feel).
It’s built on modern web standards. The security is solid. The performance is good. And it works with whatever framework your team is using – React, Angular, Vue, or plain JavaScript.
If you’re building anything that needs to span Salesforce and external applications, Lightning Out 2.0 is worth your time. Try it out, build something, see how it fits into your architecture. The future of extending Salesforce beyond the platform starts here.
Avoid common Lightning Out 2.0 mistakes. Request expert guidance. (https://2creative.ca/) from our Salesforce team on architecture and security.
Pricing management in Salesforce is the backbone of every sales operation. It’s where strategy meets execution – the intersection between what your company charges and how accurately that price reflects your value, accounts for costs, and drives profitability. Get it right, and you’re controlling margins, accelerating deal velocity, and building scalable revenue operations. Get it wrong, and you’re either leaving money on the table or dealing with constant billing disputes and manual interventions that slow everything down.
The challenge isn’t implementing a price book. Any Salesforce org has one of those out of the box. The real complexity emerges when you need to handle fractional pricing for telecom customers, price products based on hundreds of configurable attributes, apply volume discounts that vary by customer segment, ensure multi-currency accuracy across global sales teams, and eventually pass all that pricing data to billing and finance systems that need it to be exact.
This guide walks through the full landscape of Salesforce pricing management – from foundational concepts that anyone managing pricing should understand, through advanced mechanisms that separate basic implementations from sophisticated revenue operations, all the way to real-world configurations that handle scenarios that would otherwise require spreadsheets and manual overrides.
The Pricing Management Foundation: How Price Books Work
Everything in Salesforce pricing starts with price books. Not because they’re complicated, but because they’re fundamental. A price book in Salesforce is essentially a list of products and their prices. That’s it at the surface. But the architecture beneath that simplicity matters.
Standard Price Book vs. Custom Price Books
When you create a Salesforce org, you get a Standard Price Book automatically. This is the master list – every product in your org must have an entry here. The Standard Price Book entry for a product contains what Salesforce calls the “list price,” which serves as the baseline for all pricing logic downstream.
Custom Price Books layer on top of this foundation. They let you define different pricing for different market segments, sales channels, or customer tiers without duplicating your product catalog. For example, you might have one price book for direct enterprise sales, another for partners (which might include partner markups or smaller margins), and a third for a specific geography where local pricing regulations require different rates.
The key insight: a product must have an active entry in the Standard Price Book before it can appear in any custom price book. And once you’ve selected a price book on an opportunity or quote, Salesforce pulls prices from that specific book. The sales rep can still apply additional discounts, but the starting point – the list price – comes from the selected price book.
Understanding Price Book Entries
A Price Book Entry is the record that connects a Product to a Price Book and assigns a price to it within that specific book. When you create one, you’re defining:
- Which Product this entry represents
- Which Price Book this entry belongs to
- The Unit Price (the per-unit cost)
- The Product Selling Model (for subscription products, this becomes important later)
The unit price field in a Price Book Entry defaults to 2 decimal places – standard currency precision. But if your business model requires fractional pricing (like telecom billing at $0.0020 per megabyte, or SaaS platform pricing at $0.33333 per compute credit), you’ll need to enable Salesforce’s “More Decimals on Price” feature, which we’ll cover in depth later.
Once a Price Book Entry is created and active, sales reps can add products from that price book to opportunities and quotes. The system will automatically pull the price from the Price Book Entry, making it the baseline for all discount and margin calculations that follow.
Core Pricing Mechanisms: Rules, Adjustments, and Discounts
With price books as your foundation, the next layer is how prices actually change – the mechanisms that let you apply business logic to take the list price and arrive at the final customer price.
Discount Schedules: Volume-Based and Tiered Pricing
Discount Schedules are one of the most common pricing mechanisms in Salesforce. They define discounts based on quantity tiers. Here’s how they work in practice:
Your company sells software licenses. The list price is $100 per license. But you want to offer volume discounts:
- 1-10 licenses: full price ($100)
- 11-50 licenses: 5% discount
- 51-100 licenses: 10% discount
- 100+: 15% discount
You create a Discount Schedule with four tiers, each specifying a quantity range and a discount percentage. Then you attach this schedule to your product. When a sales rep adds this product to a quote and enters a quantity of 75, the quoting engine automatically applies the 10% discount because 75 falls in the 51-100 range.
Discount Schedules can be applied in multiple ways:
- Percentage Discount: A percentage off the list price (e.g., 10% discount = pay 90% of list)
- Fixed Amount Discount: A dollar amount off (e.g., $15 off per unit)
- Hard Price: Set a specific price point for that tier (regardless of list price)
They can also be scoped to the entire quote or to individual quote lines, and they support different aggregation methods – you can calculate discounts based on total quote quantity or by individual line item quantity.
Price Rules: Conditional Pricing Logic
Price Rules take discount scheduling further by adding conditional logic. A Discount Schedule says “if quantity is between X and Y, apply Z discount.” Price Rules let you layer conditions on top of that: “if quantity is between X and Y AND the customer is in segment ‘Enterprise’ AND the opportunity originated from a partner channel, then apply Z discount.”
This is where you start enforcing business logic instead of just applying flat discounts. You can create rules that:
- Vary discounts by customer type or industry
- Apply different discount caps for different sales channels
- Provide education discounts or non-profit pricing
- Enforce minimum pricing floors so reps can’t accidentally undercut your margins
- Combine multiple discount types (volume discount + channel discount + customer loyalty)
Price Rules also integrate with approval workflows, which we’ll cover later. A rule might specify that any discount above a certain threshold requires manager approval.
Price Adjustments: Beyond Standard Discounts
Price Adjustments in Salesforce Industries (Vlocity) go further – they let you apply rules-driven adjustments that consider product attributes, customer context, and complex business logic.
There are several types of price adjustments:
- Flat Adjustments: A fixed dollar amount (e.g., add $50)
- Percentage Adjustments: Multiply the current price by a percentage (e.g., apply a 12% uplift)
- Attribute-Based Adjustments: Adjust price based on product configuration (if a customer selects “premium support,” add $500 to the price)
- Volume-Based Adjustments: Tiered adjustments similar to discount schedules, but for increases as well as decreases
Each adjustment lives in what Salesforce calls a “Price Adjustment Schedule” with multiple “Price Adjustment Tiers.” You define the tier (what condition applies), the type of adjustment (amount or percentage), and the value. Then you map this to a product so the pricing engine applies it during quote generation.
Qualification Rules: Controlling When Adjustments Apply
Qualification Rules are Salesforce Industries’ way of adding guardrails around pricing adjustments. A Qualification Rule answers the question: “When is it okay to apply this adjustment?”
You might have a rule that says: “Allow a manual pricing adjustment of up to 15% for Platinum SLA accounts, but only 10% for Silver SLA accounts.” Or: “Manual pricing adjustments are only allowed through our internal sales team, not through partner portals.”
These rules evaluate context – data from the account, opportunity, quote, or order – and determine whether a pricing adjustment is allowed and under what constraints. If a sales rep tries to apply an adjustment that violates a qualification rule, Salesforce either blocks it outright or routes it to an approval workflow.
The Quote Line: Where Pricing Actually Happens
All those pricing mechanisms (discount schedules, price rules, adjustments) converge at the Quote Line Item level. A quote line is a single product on a quote, and it’s where Salesforce calculates the actual price the customer will pay.
Quote Line Item Pricing Fields
When a quote line is created, Salesforce calculates and populates several pricing fields:
- List Unit Price: The list price from the selected Price Book Entry – the baseline
- Regular Unit Price: The price after any volume discounts or special pricing tiers are applied
- Sales Price (or Special Price): The final price after all discounts, adjustments, and rules are applied
- Total Amount: The Sales Price multiplied by Quantity
Each of these fields flows through a calculation waterfall. And here’s what matters for operations: if any pricing rule fails or produces an unexpected result, you need visibility into which rule caused the issue and how the price was calculated.
The Price Waterfall: Transparent Pricing Calculations
The Price Waterfall is a feature that logs each step of the pricing calculation. When a quote line is calculated, Salesforce records:
- Starting list price
- What discount schedules were evaluated
- Which price rules matched (and which didn’t)
- What adjustments were applied
- What the final price is
Sales reps can hover over a price or click an info icon to see the waterfall and understand exactly why a price is what it is. Finance teams can audit it. If a customer disputes why they were charged a certain amount, you can pull the waterfall and explain it step-by-step.
This transparency is crucial when pricing gets complex – especially with attribute-based pricing or multiple overlapping discount rules.
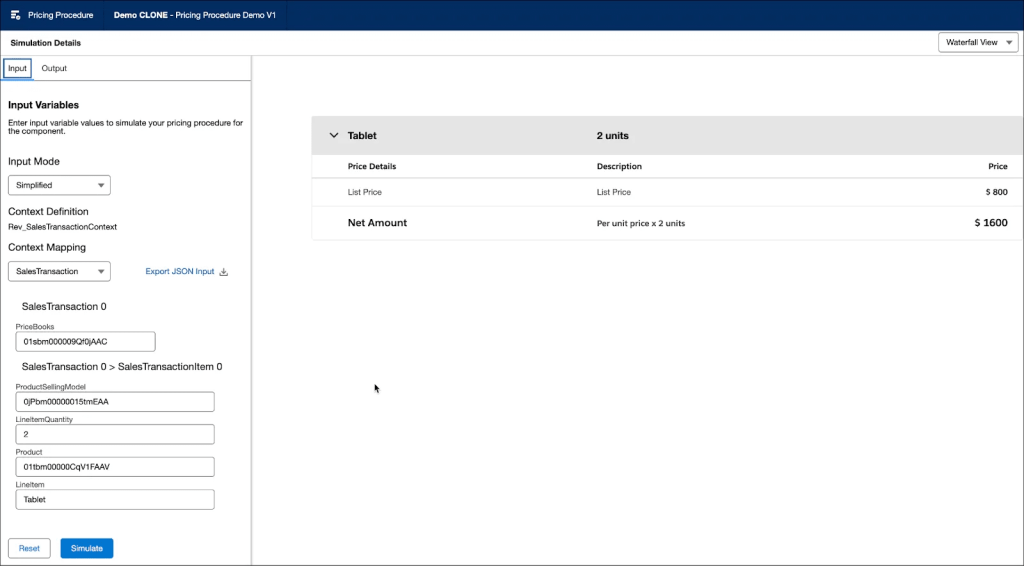
Multi-Currency Pricing: Selling Globally
If your sales teams operate across multiple countries or currencies, multi-currency pricing adds another layer to manage. It’s not just about exchange rates – though those matter. It’s about maintaining pricing strategy consistency while handling currency-specific price books, dated exchange rates, and billing in local currencies.
Setting Up Multi-Currency
Salesforce has two multi-currency options:
Standard Multi-Currency: You enable multiple currencies and set exchange rates. When a sales rep creates a quote in EUR, Salesforce automatically converts it to your corporate currency (USD, for example) using the conversion rate you set. This is simple but static – the conversion rate doesn’t change based on when the deal closes.
Advanced Currency Management (ACM): This option lets you use dated exchange rates. You can say “on this date, 1 EUR = 1.10 USD, and on that date, 1 EUR = 1.12 USD.” When a quote closes on a specific date, the conversion uses the exchange rate from that date. This is critical if you’re reporting under accounting standards like ASC 606 or IFRS, where you need historical accuracy.
Price Books and Currency
Here’s where it gets important: each Price Book has a specific currency. You can’t create one price book with prices in both USD and EUR. Instead, you create separate Price Book Entries for each currency.
This means if you have customers in five countries, you need price book entries in those five currencies for every product you sell. If you have 500 products, that’s 2,500 price book entries to maintain.
Most organizations handle this by:
- Maintaining prices in a spreadsheet with all currencies
- Setting up automated uploads or integrations to sync price book entries
- Using dated formulas to auto-calculate adjusted prices for new currencies
The key consideration: conversion rates for price book entries are not automatic. If you update an exchange rate in Setup, the price book entries don’t recalculate. You need to manually update them or use an automation tool.
Cost Books and Margin Management: Understanding True Profitability
While price books handle customer-facing pricing, cost books track what you actually spend to deliver the product. This separation is fundamental to modern revenue operations.
A Cost Book Entry specifies the actual cost associated with a product. This might include:
- Manufacturing cost for a physical product
- Acquisition cost for a software license
- Infrastructure cost for a SaaS platform
- Materials and labor for a service
Unlike a Price Book (which is mandatory), Cost Books are optional but highly recommended. Without them, you can’t calculate gross margins at the quote level, and your sales teams don’t understand how much profit they’re actually making on each deal.
Setting Up Cost Books
Cost Books follow the same structure as Price Books:
- Create a Cost Book record (e.g., “2024 Standard Costs”)
- Create Cost Book Entries that associate a Product with a Cost
- Optionally set a default cost book in your org
You can create multiple cost books for different scenarios:
- Current year vs. historical costs
- Different cost structures for different business units
- Planned vs. actual costs for forecasting
Once cost books are configured, Salesforce Pricing (the newer pricing engine in Revenue Cloud) can reference them to calculate margins directly on quote lines.
Margin Calculations on Quotes
With both price books and cost books configured, you can set up pricing procedures (we’ll cover those shortly) that calculate:
- Gross Profit: Sales Price minus Cost
- Margin Percentage: (Sales Price – Cost) / Sales Price * 100
This gets populated on the Quote Line and aggregated to the Quote header, giving sales teams immediate visibility into deal profitability.
Why does this matter? It prevents race-to-the-bottom pricing. If a sales rep sees that a deal at a 15% margin is below your company’s profitability threshold, they can adjust either the scope (reduce what they’re selling) or the price before the deal goes to the customer.
Revenue Cloud Advanced and Pricing Procedures: The Modern Approach
Salesforce has been consolidating its revenue management offerings into something called Revenue Cloud Advanced (RCA). It combines CPQ, billing, and revenue recognition into a unified platform. At the heart of RCA is a concept called Pricing Procedures.
What Is a Pricing Procedure?
A Pricing Procedure is a workflow that defines how to calculate a final price. Instead of individual discount schedules and rules scattered around, a procedure is a single, orchestrated sequence of steps that takes all your pricing logic and executes it in order.
A Pricing Procedure might look like:
- Load the product’s list price from the price book
- Apply volume discounts based on quantity
- Check if the customer has a contracted price; if yes, use that
- Apply bundle discounts if this product is part of a bundle
- Apply attribute-based adjustments if the customer selected premium options
- Apply margin floor checks; if the resulting price would create less than 20% margin, set price to minimum acceptable level
- Apply customer-specific discounts (if this is a VIP account)
- Round the price to nearest .05 if required
- Output the final price to the quote line
Each step is a Pricing Element. Salesforce provides standard elements for common scenarios (list price, discount schedules, formula-based pricing, rounding, etc.), but you can also create custom pricing elements using Apex or Flows.
The Price Waterfall in Pricing Procedures
Because Pricing Procedures are structured, they automatically generate a Price Waterfall that shows exactly which step produced which price. This is invaluable for troubleshooting and auditing.
Procedures aren’t mandatory – you can continue using individual discount schedules and rules – but they become essential as your pricing logic grows more complex.
Attribute-Based Pricing: When Products Have Infinite Variations
Some products can’t be priced with simple rules because they have too many variations. A telecom company selling mobile plans might offer:
- Different data allowances (1GB, 10GB, unlimited)
- Different device options (phone, tablet, smartwatch)
- Different contracts (month-to-month, 12-month, 24-month)
- Different add-ons (international roaming, premium support)
A watch retailer might price based on color, size, band material, water resistance rating, and processor power.
Creating a separate product for every combination is impractical. Instead, Salesforce Industries (Vlocity) uses Attribute-Based Pricing.
How Attribute-Based Pricing Works
An Attribute in Salesforce Industries describes a characteristic of a product that influences its price. You define:
- The attribute name (e.g., “Data Allowance,” “Band Material”)
- The possible values (e.g., “1GB,” “10GB,” “Unlimited” for data; “Silicone,” “Leather,” “Metal” for band)
- Whether this attribute is “price-impacting” (meaning it changes the final price)
Then you set up a Calculation Matrix that defines the pricing logic:
| Product | Data Allowance | Device | Contract | Price Adjustment |
| Mobile Plan | 1GB | Phone | Month-to-month | $0 |
| Mobile Plan | 1GB | Phone | 12-month | -$10 |
| Mobile Plan | 10GB | Phone | Month-to-month | +$30 |
| Mobile Plan | 10GB | Phone | 12-month | +$15 |
| Mobile Plan | Unlimited | Phone | 24-month | +$60 |
When a customer configures a product by selecting its attributes, Salesforce looks up the matching row in the matrix and applies the price adjustment. The final price = list price + adjustment.
Complex Pricing with Calculation Procedures
Attributes alone handle simple variations. For more complex logic, you use Calculation Procedures. These are step-by-step workflows (similar to Pricing Procedures, but built specifically for Industries) that can:
- Evaluate multiple attributes simultaneously
- Apply conditional logic (“if data is unlimited AND contract is 24-month, apply X pricing”)
- Reference cost tables for automatic margin calculations
- Chain multiple adjustments together
Calculation Procedures integrate with OmniStudio, Salesforce Industries’ visual configuration platform, so non-developers can build and test them.
Subscription and Usage-Based Pricing: Modern Revenue Models
Traditional pricing – one-time purchases at a fixed price – is becoming less common. Subscriptions, metered billing, and usage-based pricing are increasingly the standard.
Subscription Pricing Mechanics
A subscription product has a start date, a duration (e.g., 12 months), and a billing frequency (e.g., monthly, quarterly, annual). When a subscription is created:
- Salesforce calculates the total contract value
- It divides that across billing periods
- It creates billing records for each period
- Each billing record eventually becomes an invoice
This seems straightforward, but complications emerge:
Mid-cycle changes: If a customer upgrades from a Basic plan to a Premium plan on day 15 of a 30-day month, how much do they pay for the rest of the month? The answer is proration.
Proration ensures customers pay only for what they use. You calculate a proration factor (days remaining / days in month) and apply it to the price difference. For an upgrade, you credit the unused portion of the old plan and charge the prorated portion of the new plan.
Salesforce Billing automates this, but you need to configure it:
- Define proration rules on the product (proration type: daily, monthly, etc.)
- When an amendment is made, Salesforce calculates the proration and creates credit memos and new invoice lines
- The net effect ensures the customer pays the right amount
Usage-Based and Metered Pricing
Usage-based pricing (also called consumption-based) charges customers based on actual usage, not ahead of time. A SaaS platform might charge:
- $0.02 per API call
- $5 per active user per month
- $0.50 per GB of data stored
The business needs to:
- Meter the usage (collect data on how much the customer used)
- Rate the usage (apply the price per unit)
- Aggregate it into usage summaries
- Invoice based on those summaries
Salesforce Billing handles this with Consumption Schedules and Usage Records.
A Consumption Schedule defines how often to meter and bill:
- Billing frequency (monthly, quarterly, etc.)
- How to aggregate usage (all customers together, or by account)
Usage Records capture the actual consumption data. These can be:
- Rated: Salesforce calculates the charge (quantity × unit price)
- Prerated: The customer or a third-party system specifies the charge directly (useful for pass-through costs)
When the billing cycle ends, Salesforce generates a Usage Summary that totals all the rated and prerated records, then includes that on the customer’s invoice.
The challenge: accuracy. Even small per-unit prices compound at scale. If you’re billing $0.0020 per transaction and a customer processes 10 million transactions monthly, that’s $20,000 in charges. Get the metering wrong by 1%, and you’ve lost $200 in revenue – across a customer base, that’s significant.
Approval Workflows and Pricing Governance
Not every sales rep should be able to set any price. Governance is essential – enforcing minimum margins, discount caps, and approval chains.
Approval Rules and Workflows
You configure approval rules in Salesforce that specify when a quote or discount needs approval. For example:
- Any discount greater than 10% requires manager approval
- Any deal below 20% margin requires VP approval
- Any contract with custom pricing requires legal review
When a sales rep creates a quote that violates these rules, the quote is locked into an “Approval Required” state. An automated workflow notifies the approver, they review the deal (hopefully the pricing waterfall provides visibility into why the rep requested that price), and they either approve or reject it.
Approval chains can have multiple steps:
- Sales rep enters discount > 10%
- Quote goes to direct manager for review
- Manager approves or denies
- If approved, but discount is > 20%, it goes to VP for secondary review
- If all approvals clear, quote is unlocked and rep can send to customer
Approval Workflow Best Practices
The most common mistake: too many approval levels. Organizations think “more oversight = better control,” but in practice, slow approvals kill deal velocity. Sales reps work around them by structuring deals differently or going to the wrong approver.
Best practice: Keep approval levels minimal and use clear, rule-based criteria. If a discount is under 9%, the rep’s manager can approve. If it’s 9-20%, the VP approves. Above 20%, it goes to the CFO. Make authority levels clear so reps know exactly who to ask.
Another practice: Set discovery questions on the approval form so approvers understand why the discount was necessary (customer had a competing offer, it was needed to close a strategic account, etc.). This provides context for the decision.
The More Decimals on Price Feature: Solving Fractional Pricing Challenges
Many industries rely on fractional pricing – prices with more precision than the standard two decimal places. This is where the “More Decimals on Price” feature becomes critical.
The Problem Scenario
Imagine a telecom company that charges $0.0020 per megabyte of data. In standard Salesforce:
- You try to enter $0.0020 in a Price Book Entry unit price field
- Salesforce rounds it to $0.00
- A customer using 5,000 MB should be charged $10.00
- Instead, the quote calculates $0.00 × 5,000 = $0.00
- You’ve lost $10 per customer, and at scale, that’s significant revenue leakage
This scenario isn’t hypothetical. It affects telecommunications, utilities, SaaS platforms with metered billing, and manufacturing companies buying raw materials at fractional rates.
Enabling More Decimals on Price
The “More Decimals on Price” feature extends pricing precision from 2 decimal places to 8. This means you can enter:
- $0.00200000 (telecom data per MB)
- $2.54632100 (manufacturing materials per gram)
- $0.33333333 (fractional SaaS credits)
Once enabled, these fields support full 8-decimal precision:
- Price Book Entry: Unit Price field
- Quote Line Item: Sales Price field
- Opportunity Line Item: Sales Price field
- Product custom fields (if created)
Important limitation: The Quantity field still defaults to 2 decimal places. You can price something at $0.12345678 per unit, but you’re entering quantities like 100.00, not 100.12345678. If your business needs high-precision quantities, contact Salesforce Support for a separate feature request.
Enabling More Decimals: Prerequisites and Process
Critical pre-activation checks:
Before requesting this feature, audit every system connected to your Salesforce org:
- ERP Integration: Does your ERP (SAP, Oracle, NetSuite, etc.) accept 8-decimal currency values in its data model?
- Billing System: Can your billing system (Zuora, Stripe, etc.) handle 8-decimal precision?
- Accounting Software: Does your accounting platform (QuickBooks, Xero, etc.) support it?
- Custom Middleware: Any custom integrations or APIs that handle pricing?
Most databases define currency columns as DECIMAL(10,2) – meaning 10 digits total with 2 after the decimal. This format can store values like $999999.99 but can’t store $0.12345678. Before requesting this feature, you need to update all database schemas to DECIMAL(18,8) or similar to accommodate 8-decimal values.
Testing in Sandbox:
Never enable this in production first. Request it in a full-copy or partial-copy sandbox that mirrors production data. Then:
- Create Price Book Entries with extended decimals (e.g., $0.00200000)
- Add products to opportunities and quotes
- Run complete quote-to-cash workflows
- Trigger any Apex code that touches price fields and verify it handles 8 decimals
- Push data through all integrations and confirm they process correctly
Org-Wide Setting:
Important: This is an org-wide setting. You can’t selectively enable it for certain products and not others. Once enabled, every price field in your entire org supports 8 decimals. Products with fractional pricing display as $599.00000000 (trailing zeros), which is technically correct but visually cluttered. This is not a problem functionally, just a display consideration.
The Activation Process:
More Decimals on Price is not a self-service feature – it requires a database schema change that only Salesforce Support can make. Here’s the process:
- Log into your Salesforce Help Portal (
- https://help.salesforce.com
- )
- Click Support, select “Contact Support,” and choose your org
- Create a Case with:
- Category: Feature Activations & Limits
- Product: Sales Cloud or Service Cloud (depending on your org)
- Sub-Category: Pricing Features or Product Configuration
- In the case description, provide:
- Your business need (e.g., “We charge $0.0020 per MB for telecom services”)
- Current issue (e.g., “Prices are rounding to $0.00”)
- Estimated impact (e.g., “$XX,XXX quarterly revenue leakage”)
- Confirmation that you’ve tested in sandbox
- Confirmation that your integrations support 8 decimals
Salesforce typically responds within 1-2 business days and completes activation within 3-5 business days.
Post-Activation Behavior:
After activation:
- You can enter prices like 0.12345678 in Price Book Entry Unit Price fields
- These prices persist exactly as entered – no rounding
- Lightning Experience displays all 8 decimals for any price that has them (even if most are zeros)
- Regular 2-decimal pricing (like $599.00) still works fine and displays as you’d expect
The visual behavior – those trailing zeros – is not wrong, just present. Some teams accept it; others create a custom display component to hide unnecessary zeros. That’s a presentation choice, not a functional requirement.
Common Pricing Implementation Mistakes and How to Avoid Them
After years of Salesforce implementations, certain pricing mistakes recur across organizations. Learning from them can save you months of rework.
Mistake 1: Overcomplicating Product Configuration
The Issue: You try to create 50 discount schedules, 100 price rules, and custom Apex classes all at once. The system becomes hard to maintain, documentation is poor, and nobody remembers why rule #47 exists.
The Solution: Start simple. Create only the pricing rules you actually need right now. Test them thoroughly. Add more rules as you encounter real business needs, not hypothetical ones. Keep product configurations simple and documented.
Mistake 2: Ignoring Legacy Data and Contracts
The Issue: You’re implementing CPQ with existing contracts worth millions in revenue, but you don’t plan how to integrate them. Existing deals stay in spreadsheets while new deals go through the system, creating two sources of truth.
The Solution: Plan legacy data handling in your project kickoff. Decide whether legacy contracts will be migrated into the system or tracked separately. If migrating, do it early. If tracking separately, create a clear process for renewal and amendments – legacy deals can’t stay in spreadsheets forever.
Mistake 3: Inadequate Data Cleanup Before Go-Live
The Issue: Your product catalog has duplicates, pricing is inconsistent across price books, and your currency data is outdated. You go live with this data, and now your reps are confused about which products to use and which prices are current.
The Solution: Invest time in data cleanup before implementation. De-duplicate products, validate price book entries, update currency and exchange rates. Run audits to catch issues. It’s boring work but essential.
Mistake 4: Not Testing Renewals and Amendments
The Issue: You test new quotes thoroughly, but you don’t test what happens when a customer renews their subscription. Or you don’t test mid-contract amendments. Then a customer tries to renew, and the pricing calculates incorrectly because the renewal logic wasn’t configured.
The Solution: Test every scenario: new deals, renewals, amendments with upgrades, amendments with downgrades, plan cancellations. For subscription products, test proration at various mid-cycle points. Don’t just test “happy path” scenarios.
Mistake 5: Ignoring Price Changes Over Time
The Issue: You set up pricing once and assume it’s static. But prices change. Products have end-of-life dates. New pricing models are introduced. Competitors adjust their pricing. Your pricing system reflects a point-in-time snapshot, not the reality of ongoing pricing evolution.
The Solution: Build a plan for pricing updates into your governance model. Decide how frequently price books are updated, who owns that process, how old pricing is archived, and how historical pricing is tracked for revenue recognition purposes. Implement this process before go-live, not after.
Mistake 6: Poor Integration Planning
The Issue: You enable More Decimals on Price, but your ERP can’t handle 8-decimal values. Data flows from Salesforce to the ERP, and the integration breaks. Or you implement multi-currency pricing without verifying that your billing system handles currency-specific price books.
The Solution: Before enabling any advanced pricing feature, audit integrations. Verify database schemas, API limitations, and data format requirements. Test in sandbox environments that mirror your production integrations, not just toy environments. Integration issues often catch edge cases that functional testing misses.
Practical Pricing Strategy: Aligning Technology with Business Goals
Technology enables pricing strategy, but it doesn’t create one. Here are some principles that separate mediocre pricing implementations from excellent ones.
Principle 1: Pricing Should Be Transparent
Your sales team should understand why a price is what it is. The Price Waterfall helps with this, but so does clear documentation. Document your discount policies, approval criteria, and pricing rules in plain language. When a rep has a question, they should be able to find an answer without escalating to the VP of Sales.
Principle 2: Margins Matter More Than Volume
It’s tempting to chase every deal with aggressive discounting. Cutting prices by 20% to win a customer feels like a “win.” But if that deal is already at a thin 12% margin, and discounting takes it to 9.6%, you’ve just made the deal less profitable. Build visibility into margins at the quote line, and make reps accountable for profitability, not just volume.
Principle 3: Pricing Rules Should Enforce, Not Restrict
The best approval workflows don’t say “no”; they guide reps toward better outcomes. Instead of “discounts above 10% are rejected,” try “discounts above 10% require approval, and here are the factors we consider when approving.” This keeps reps engaged in the process instead of frustrated by arbitrary rules.
Principle 4: Regular Audits Catch Drift
Pricing works fine for the first month, then slowly degrades as exceptions accumulate. A customer gets a one-time discount in January and it stays in the system through December. A price rule is “temporarily” disabled and never re-enabled. A price book entry is outdated. Regular audits – quarterly at minimum – catch these issues before they compound.
Principle 5: Cost Visibility Drives Better Pricing
If your sales team doesn’t know what a product costs to deliver, they’re pricing blind. Implement cost books and make margin information visible on quotes. This shifts conversations from “we’re leaving money on the table” to “here’s how we can structure this profitably.”
Conclusion: Building a Pricing System That Scales
Pricing management in Salesforce is rarely a “set it and forget it” configuration. It’s an ongoing operational capability that evolves as your business scales, your market changes, and your product offerings expand.
The implementations that work best share some common characteristics:
- They start simple: Basic price books and discount schedules, then layer complexity as needed
- They’re well-documented: Future implementers understand what exists and why
- They’re tested thoroughly: Edge cases and exception scenarios are validated before go-live
- They’re audited regularly: Data quality and rule effectiveness are checked quarterly
- They’re tied to business outcomes: Pricing isn’t just a technical exercise; it’s measured against margins, deal velocity, and revenue goals
If your current pricing system feels like it’s held together by duct tape and spreadsheets, investing in a proper Salesforce pricing implementation pays dividends. If you’re just starting, building it right the first time prevents the debt you’d otherwise accumulate.
The organizations that win are those that make pricing a strategic advantage – using Salesforce’s tools (price books, discount schedules, pricing procedures, pricing guidance, cost books, and margin analytics) not just to execute transactions, but to drive consistent, profitable growth.
Need Help Implementing Salesforce Pricing Management?
Pricing management can get complex fast – especially when you’re dealing with multi-currency configurations, attribute-based pricing, or precision billing with fractional rates. If you’re implementing Revenue Cloud Advanced, migrating from legacy CPQ, or troubleshooting pricing challenges in Salesforce Industries, our team at 2Creative Solutions specializes in exactly these scenarios.
We’ve helped enterprises across telecommunications, healthcare, insurance, and manufacturing build pricing systems that scale – from basic price book setups to sophisticated pricing procedures with cost tracking and margin analytics.
Visit 2creative.ca to explore our Salesforce Industries expertise, check out our latest blog articles, and see how we’ve solved complex pricing challenges for organizations like yours.
Ready to discuss your pricing implementation? Get in touch with our team and let’s build a pricing strategy that drives profitability, not just transactions.